
Introduction
The conversational AI market is projected to hit $49.8 billion by 2031, signaling that human-like dialogue with machines is no longer a novelty, it's becoming core business infrastructure. Yet scale isn’t the only driver. Research shows people notice conversational lag in as little as 100 milliseconds, meaning latency and timing can make or break the illusion of a natural exchange.
From real-time interview coaches to digital teammates on video calls, AI is rapidly moving beyond static chatbots into immersive, multi-modal experiences that feel closer to human interaction than ever before. For businesses, this shift isn’t just about convenience, it's about differentiation: enabling always-on engagement, scalable expertise, and new levels of accessibility.
But delivering on that promise takes more than clever models. It demands modular, low-latency, video-enabled architectures that can keep pace with evolving use cases and rising user expectations.
The Vision: Modular, Real-Time Video AI for the Next Generation
Our goal was simple but ambitious: build a proof-of-concept (POC) for real-time, scalable, video-enabled AI conversations, one that could be adapted to any domain, from recruitment to coaching to customer support.
We wanted to validate:
- That modern pipelines like pipecat can orchestrate complex AI flows with plug-and-play flexibility.
- WebRTC and Next.js can deliver seamless, real-time user experiences in the browser.
- That integrating video AI into conversations is not just possible, but practical for future products.
Architecture Overview
To achieve this vision, we architected a modular, future-proof stack:
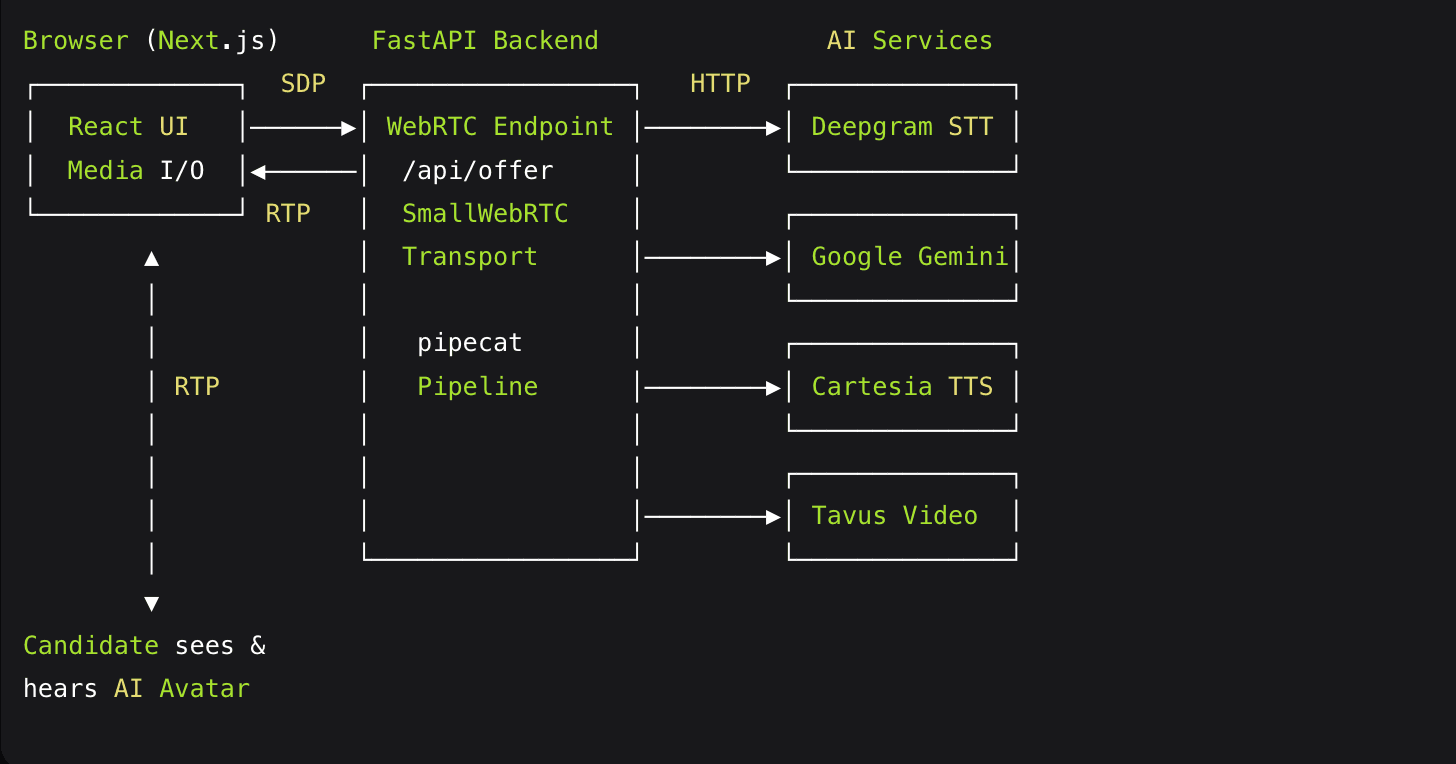
Key components:
- Frontend: Next.js 13 (React 18) for fast, interactive UI and SSR capabilities.
- Backend: FastAPI (Python) for async signaling, static file serving, and API endpoints.
- Media Transport: SmallWebRTCTransport (via pipecat) abstracts away ICE/SDP headaches and enables real-time audio/video.
AI Services:
- STT: Deepgram Streaming for sub-300ms transcription.
- LLM: Google Gemini for long-context, high-accuracy dialogue.
- TTS: Cartesia for natural, high-fidelity speech.
- Video: Tavus for fast, lip-synced avatar generation.
Building the Pipeline
At the heart of our proof-of-concept is a Pipecat driven, modular media pipeline that moves seamlessly from browser-captured audio/video to a fully rendered, lip-synced AI avatar — and back again — all in real time.
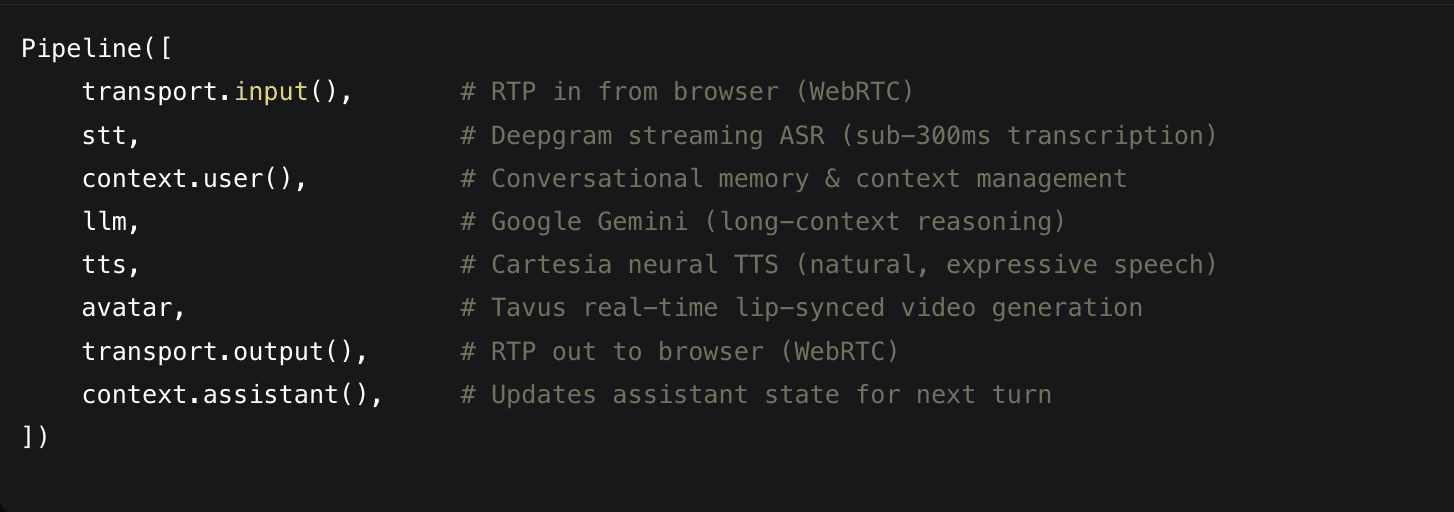
This modular design means each stage is loosely coupled yet deeply integrated, allowing us to replace, extend, or reorder components with minimal refactoring. For example, swapping Deepgram for Whisper or integrating a different TTS provider is a matter of minutes, not days.
Why Pipecat?
Pipecat powers the flow of real-time conversational AI enabling modularity, adaptability, and precision at every stage:
- Plug-and-Play Components – Swap STT, LLM, or TTS modules without touching the rest of the pipeline.
- Back-Pressure Awareness – Dynamically adapts to load, preventing buffer overflows and ensuring smooth audio/video playback even under high concurrency.
- Frame-Level Observability – Emits granular metrics per stage (e.g., STT delay, LLM token generation speed, TTS synthesis time) for proactive performance tuning.
- Extensible by Design – Adding emotion detection, sentiment scoring, or domain-specific reasoning is as simple as inserting another pipeline block.
WebRTC + Next.js: Real-Time Frontend Stack
- WebRTC for Media Transport – Enables direct, low-latency audio/video streaming between the browser and backend, reducing round-trip delays compared to traditional HTTP-based media flows.
- Next.js 13 + React 18 – Gives us server-side rendering (SSR) for initial load speed, concurrent React for responsiveness, and a modern developer experience for rapid iteration.
- Media I/O Integration – Our React components handle microphone, camera, and playback streams while seamlessly interfacing with the WebRTC transport layer.
Video AI Integration: Beyond Voice:
Adding Tavus into the chain transforms the experience from “hearing an AI” to “meeting one face-to-face”:
- Lip-Synced, Expressive Avatars – Matches generated speech perfectly to facial movement, making interactions more natural and engaging.
- Low Overhead, High Impact – Video synthesis is batched and streamed back with minimal latency overhead (~500–1000 ms), preserving conversational flow.
- Scalable Personalization – Avatars can be branded, personalized per user, or adapted to specific cultural and linguistic contexts.
In short, this pipeline isn’t just about making the AI talk, it's about making it feel present, all while keeping the architecture flexible, observable, and production-ready.
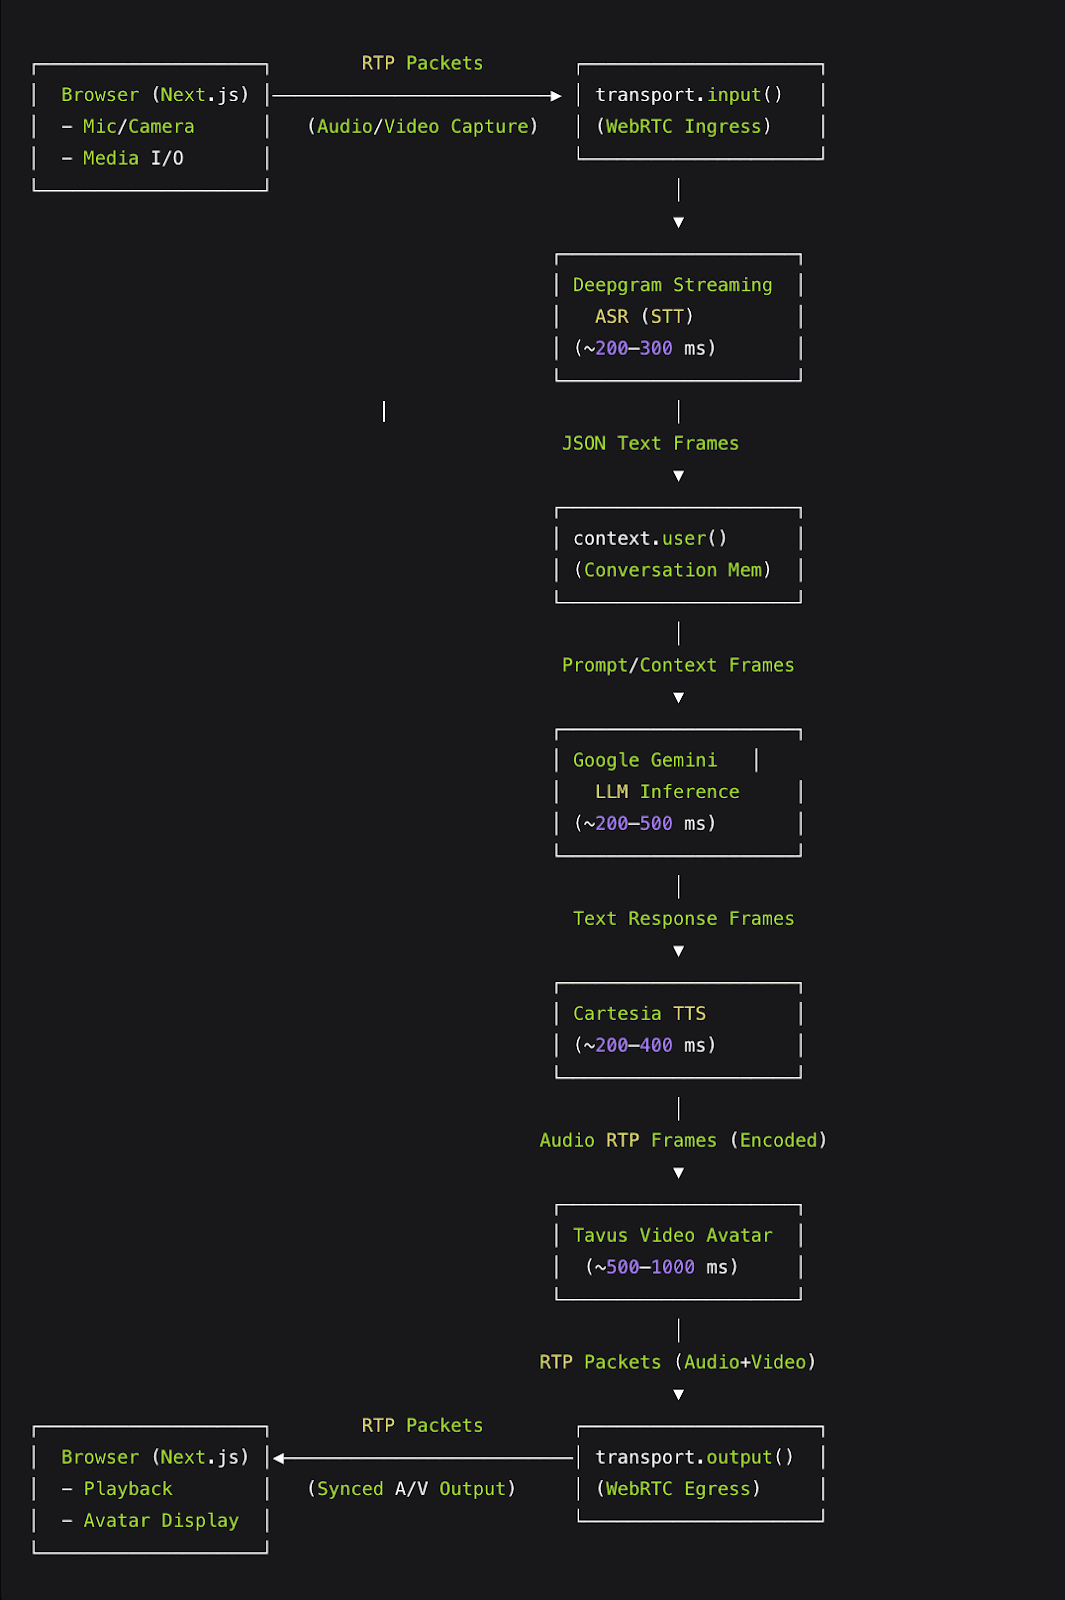
Real-Time AI Conversation Pipeline: Frame & Packet Flow
High-Level Latency Overview
Component | Service | Typical Latency | Notes |
|---|---|---|---|
STT | Deepgram Streaming | ~200–30 ms | Ultra-low latency transcription from audio to text under optimal network conditions. |
LLM | Google Gemini | ~200–500 ms | Latency depends on token count and compute provisioning; optimized APIs or batching help reduce time. |
TTS | Cartesia | ~200–400 ms | Generates high-fidelity, natural-sounding speech. |
Video | Video | ~500–1,000 ms | Fast lip-synced avatars; varies with resolution, duration, and GPU provisioning. |
Overall Pipeline Latency (Browser ↔ AI ↔ Browser): Around 1–2 seconds, depending on infrastructure, load, and optimization. Real-world performance might be closer to ~1.5 seconds under production conditions.
High-Level Pricing Overview
Component | Pricing Model | Accurate Cost (per minute) | Notes |
|---|---|---|---|
Deepgram STT | Standard streaming tier: $0.08 per audio minute | $0.08 | Published list price for Speech-to-Text API streaming mode. |
Google Gemini | Gemini 2.5 Flash paid tier: $0.30 input + $2.50 output per 1M tokens (~750 tokens ≈ 1 min) | $0.0041 | (0.30 / 1,000,000) × 750 + (2.50 / 1,000,000) × 750 ≈ $0.0041/min. |
Cartesia TTS | Startup plan: $49/month for 1.25M credits (1 credit = 1 char; ~750 chars ≈ 1 min) | $0.0294 | $49 / (1,250,000 ÷ 750) ≈ $0.0294 per minute of TTS at Startup tier. |
Tavus Video | Starter plan video generation overage: $1.10 per minute | $1.10 | Pay-as-you-go overage rate for AI video generation minutes beyond included quota. |
Total | $1.2135/min | Sum of individual per-minute costs. |
Note: These are ballpark figures. Actual costs vary by vendor, volume discounts, or enterprise contracts. Best practice: consult vendor rate cards or get quotes for precise numbers.
Scope and Reuse: Where This Pipeline Can Go
The strength of a modular, low-latency, video-enabled conversational AI pipeline lies in its flexibility. Once the foundation is built, it can be adapted to diverse domains with minimal changes to the architecture. Swap models, adjust prompts, or rebrand avatars the underlying system remains the same.
Demo in Action: AI Conversational Interview
Here’s a short demo from one of our early use cases: an AI-powered conversational interview. Candidates interact with a lifelike avatar that greets them, asks tailored questions, listens in real time, and adapts follow-ups based on their responses, creating an interaction that feels remarkably human.
Other High-Impact Applications
Customer Support
Empower virtual agents with video avatars to deliver emotionally rich, accessible, and engaging customer interactions especially useful in remote or under-served markets.
Healthcare and Therapy
Enable virtual consultations or mental health assistants with empathetic avatars to increase patient comfort and trust (ensuring HIPAA or equivalent compliance).
Education and Training
Deploy on-demand instructor avatars for personalized lessons, interactive role-play, or skill-building simulations.
Conclusion: Takeaways for Builders & Visionaries
- Modularity is leverage – Pipelines like Pipecat let you adapt, swap, and scale at the speed of innovation.
- Latency is UX – Every 100 ms shapes the user’s experience. Tune it like your product depends on it because it does.
- Observability wins – Measure everything, or you’re flying blind.
- Video is the next frontier – Human-like avatars are now practical, scalable, and game-changing.
Whether you are building the next breakthrough or deploying AI to transform your business, now is the time to act.
Hope you find this article useful. Thanks and happy learning!