

Reliability and Production Readiness
We examine your architecture’s failure tolerance, your incident response maturity, and your deployment and disaster-recovery safeguards, then show you exactly where production is fragile and the most direct path to fixing it.
Stop Hoping Your Systems Stay Up. Start Knowing They Will



Most engineering teams discover the true state of their production readiness only when an outage is already underway and customers are feeling it. Our Reliability & Production Readiness Assessment surfaces the fragilities, single points of failure, and operational gaps most likely to cause your next incident, before your users run into the consequences.
Incident response becomes more structured and repeatable, unplanned downtime stops setting the tone of your on-call culture, and the systems you run start to match the availability commitments your business has made. You leave with a detailed, sequenced roadmap your engineers can start on right away.
Client Results and Success
Production-Ready Kubernetes Architecture
The platform was designed to support scalable production deployments with minimal resource consumption, enabling faster environment provisioning and operational stability.
- environments K8s setup
- 3
- environments K8s setup
- 95%
- savings over managed Kubernetes alternatives
- 35%
40% Faster Onboarding Completion
The redesigned system achieved a 40% reduction in onboarding completion time, directly improving platform adoption and reducing operational bottlenecks.
- Improvement in the doctor's efficiency for treatment planning
- 35%
- Reduction in onboarding completion time
- 40%
Production-Grade AI Infrastructure
The system supports scalable AI inference and automated inspection workflows, reducing manual intervention and enabling consistent performance under growing usage.
Read case study3× Faster Feature Iteration
The platform achieved 3x faster AI feature iteration cycles, significantly reducing time-to-release for new recommendation
- Reduction in meal decision time
- 40%
- Increase in daily active usage during pilot
- 2x
50% Fewer Manual Validation Cycles
The system achieved a 50% reduction in manual validation cycles, improving throughput and accelerating delivery timelines.
- Reduction in manual validation cycles
- 50%
- Faster internal testing workflows
- 30%
60% Cloud Cost Reduction
The platform achieved a 60% reduction in monthly cloud costs while maintaining uptime and transaction stability during and after optimization.
- Saved per month
- $4,800
- Annual savings
- $57,000+
Our Reliability Assessment Examines Three Critical Dimensions
Our assessment looks at three areas: architectural resilience, incident response maturity, and operational readiness. We don’t rely on documentation reviews and stakeholder interviews alone. Our engineers go through your real system configurations, alert history, runbooks, deployment procedures, and post-incident reports. The result is a clear picture of where your production environment is solid, where it holds together on institutional knowledge and individual heroics, and where a single unexpected failure could cascade into a customer-facing event.
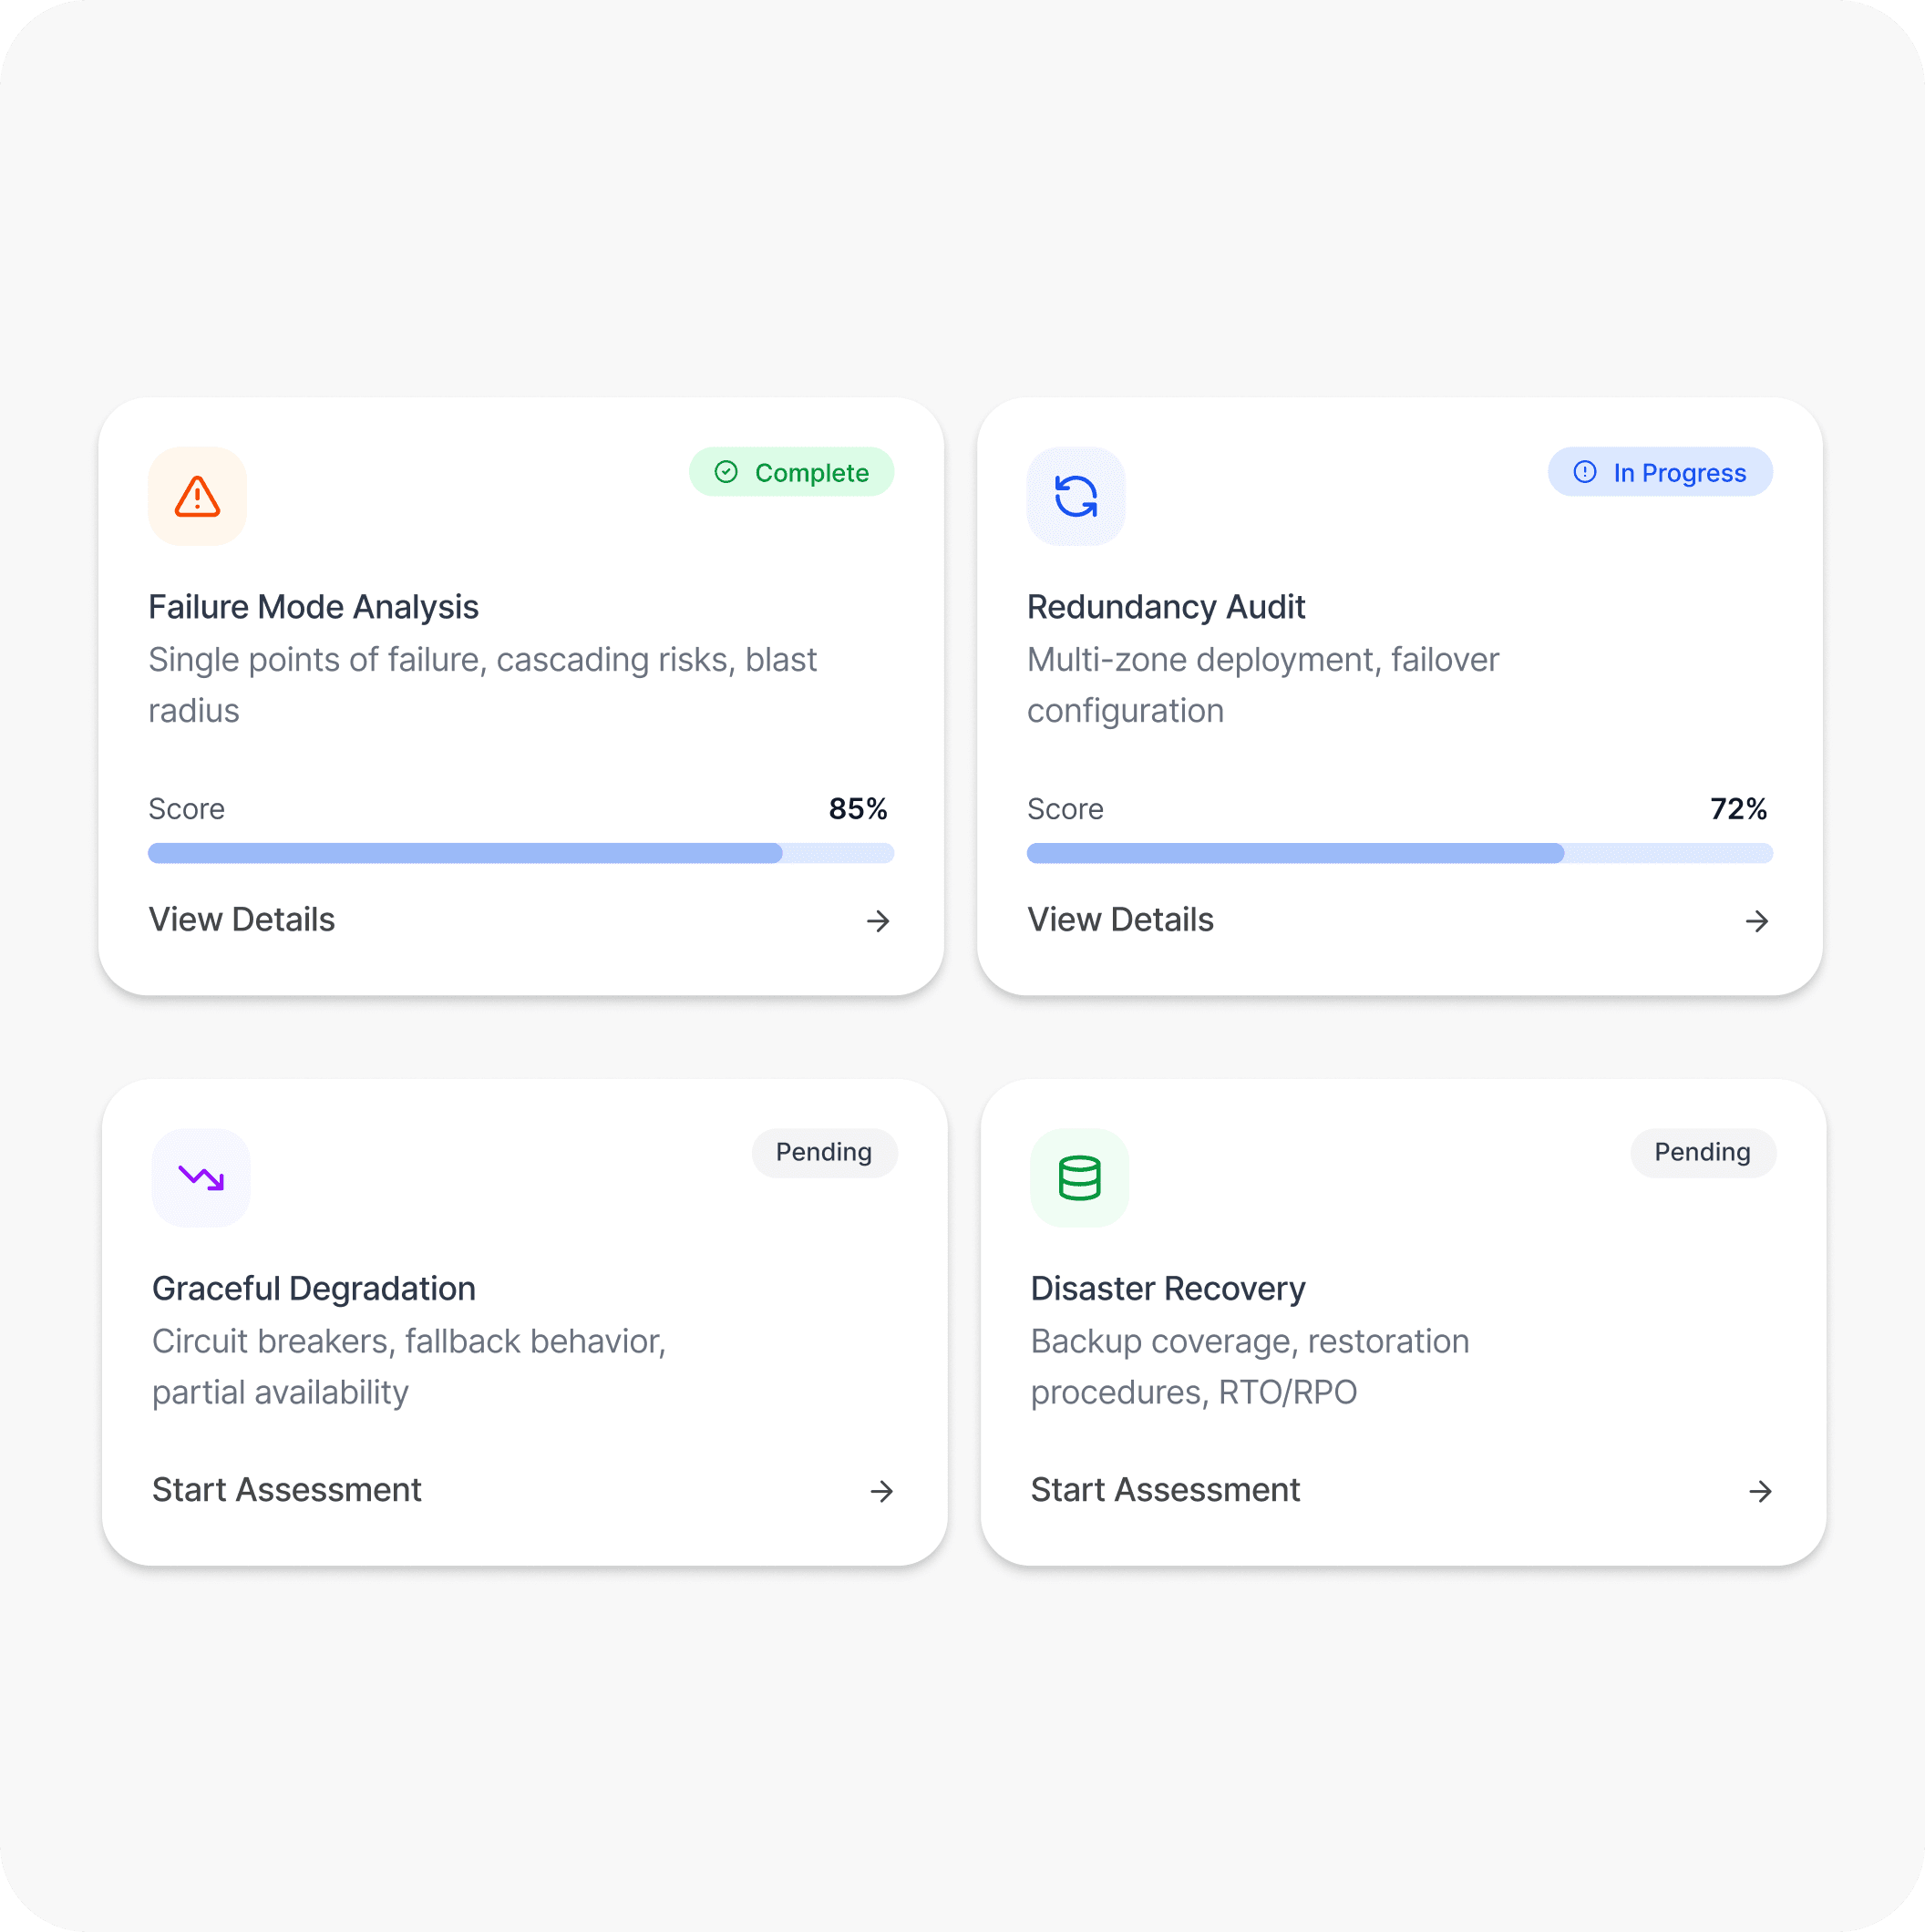
- Failure mode analysis: Single points of failure, cascading dependency risks, and blast radius assessment across all critical services
- Redundancy and fault tolerance audit: Multi-zone deployment coverage, failover configuration, and load distribution under component failure
- Graceful degradation assessment: Circuit breaker implementation, fallback behavior definition, and partial availability capability
- Disaster recovery readiness: Backup coverage verification, restoration procedure validation, and RTO/RPO alignment with business requirements
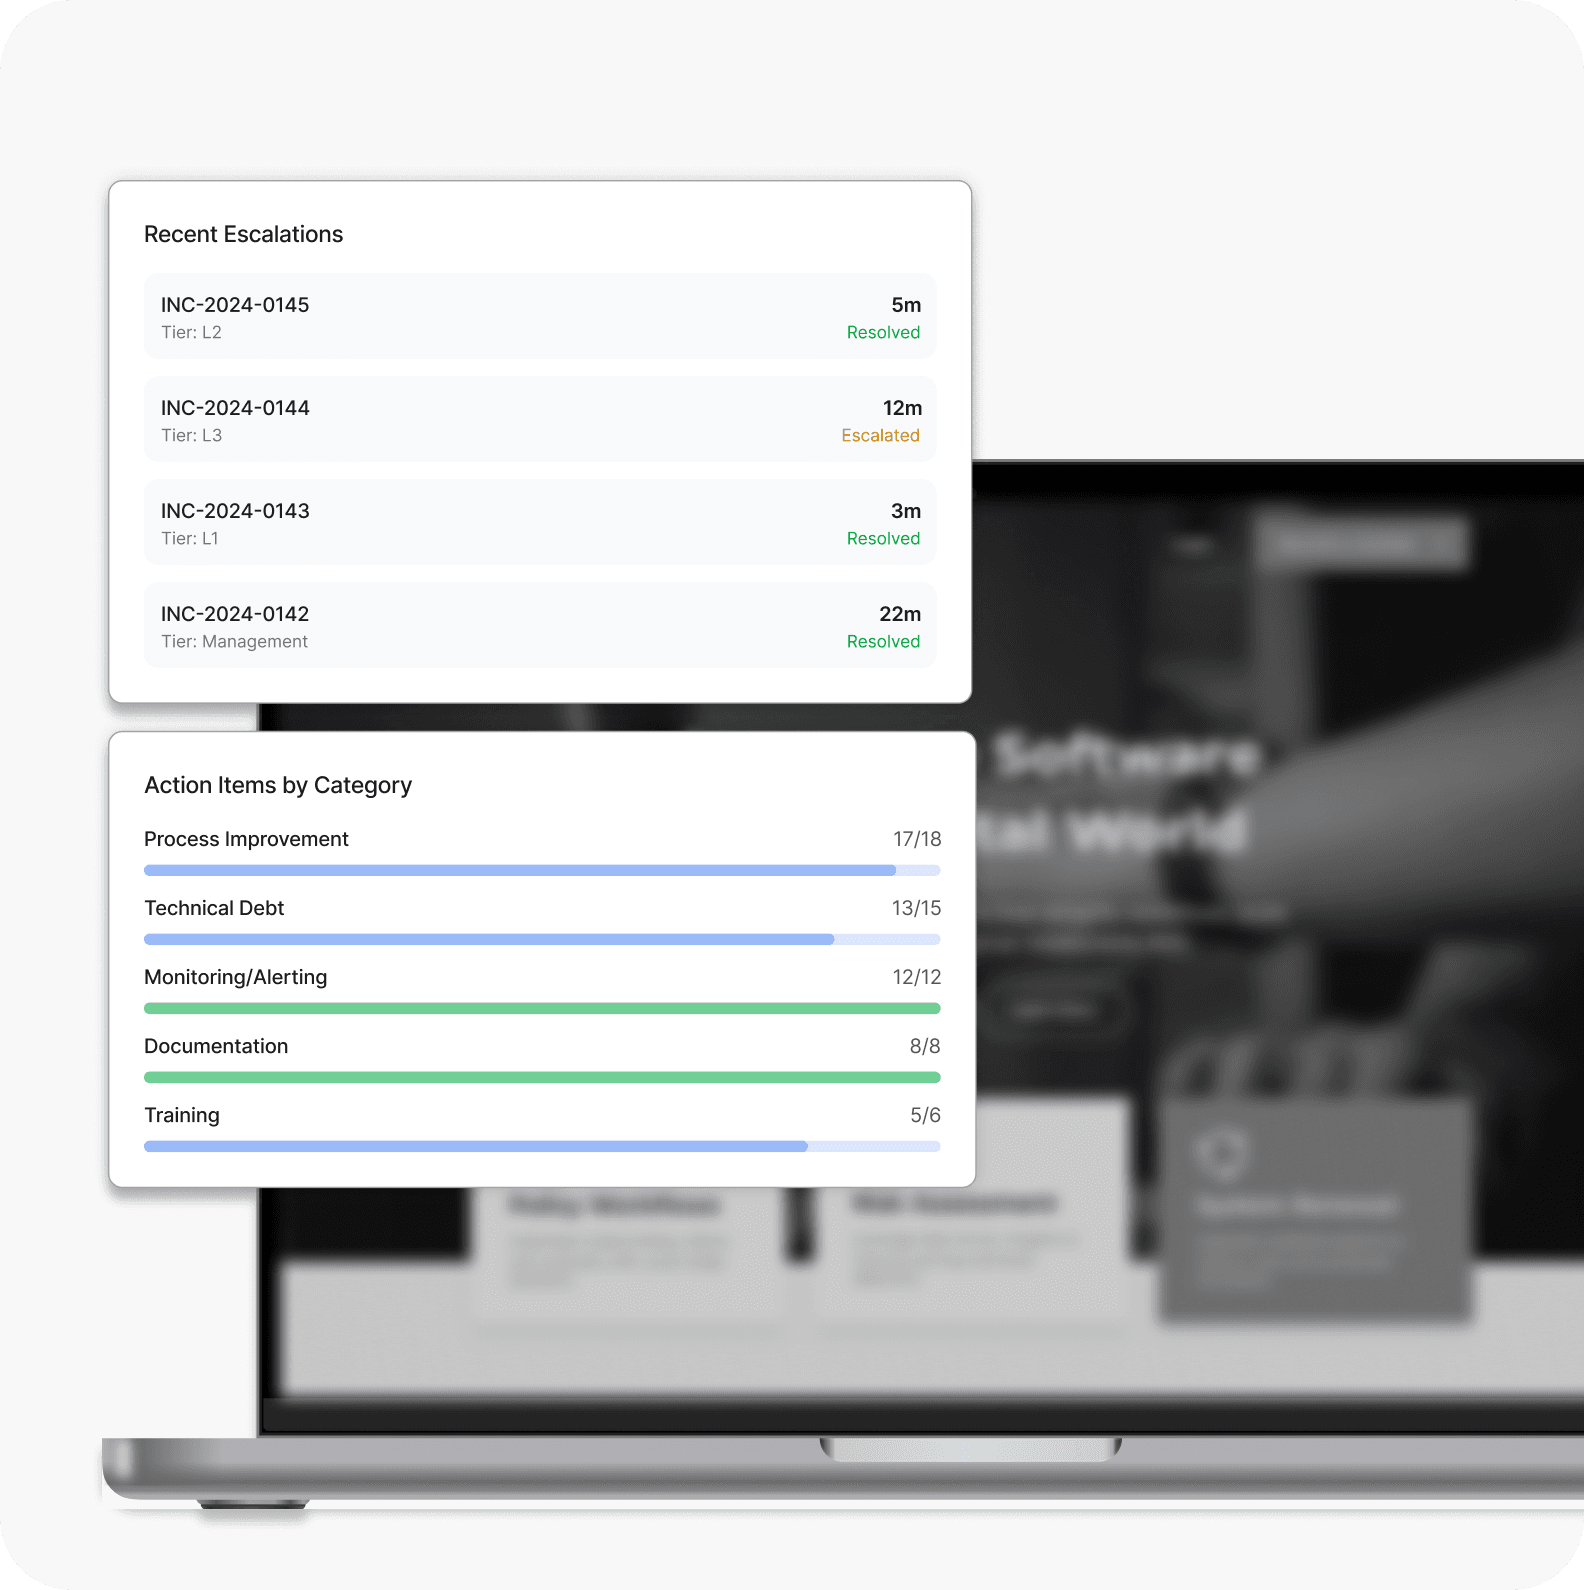
- Alerting coverage and quality audit: Detection gaps, false positive rates, alert routing effectiveness, and on-call notification reliability
- Runbook completeness review: Coverage across known failure modes, procedural clarity, and accessibility under incident pressure
- Escalation path validation: Role clarity, contact currency, and decision authority at each escalation tier
- Post-incident process evaluation: Blameless retrospective practices, action item tracking, and recurrence prevention effectiveness
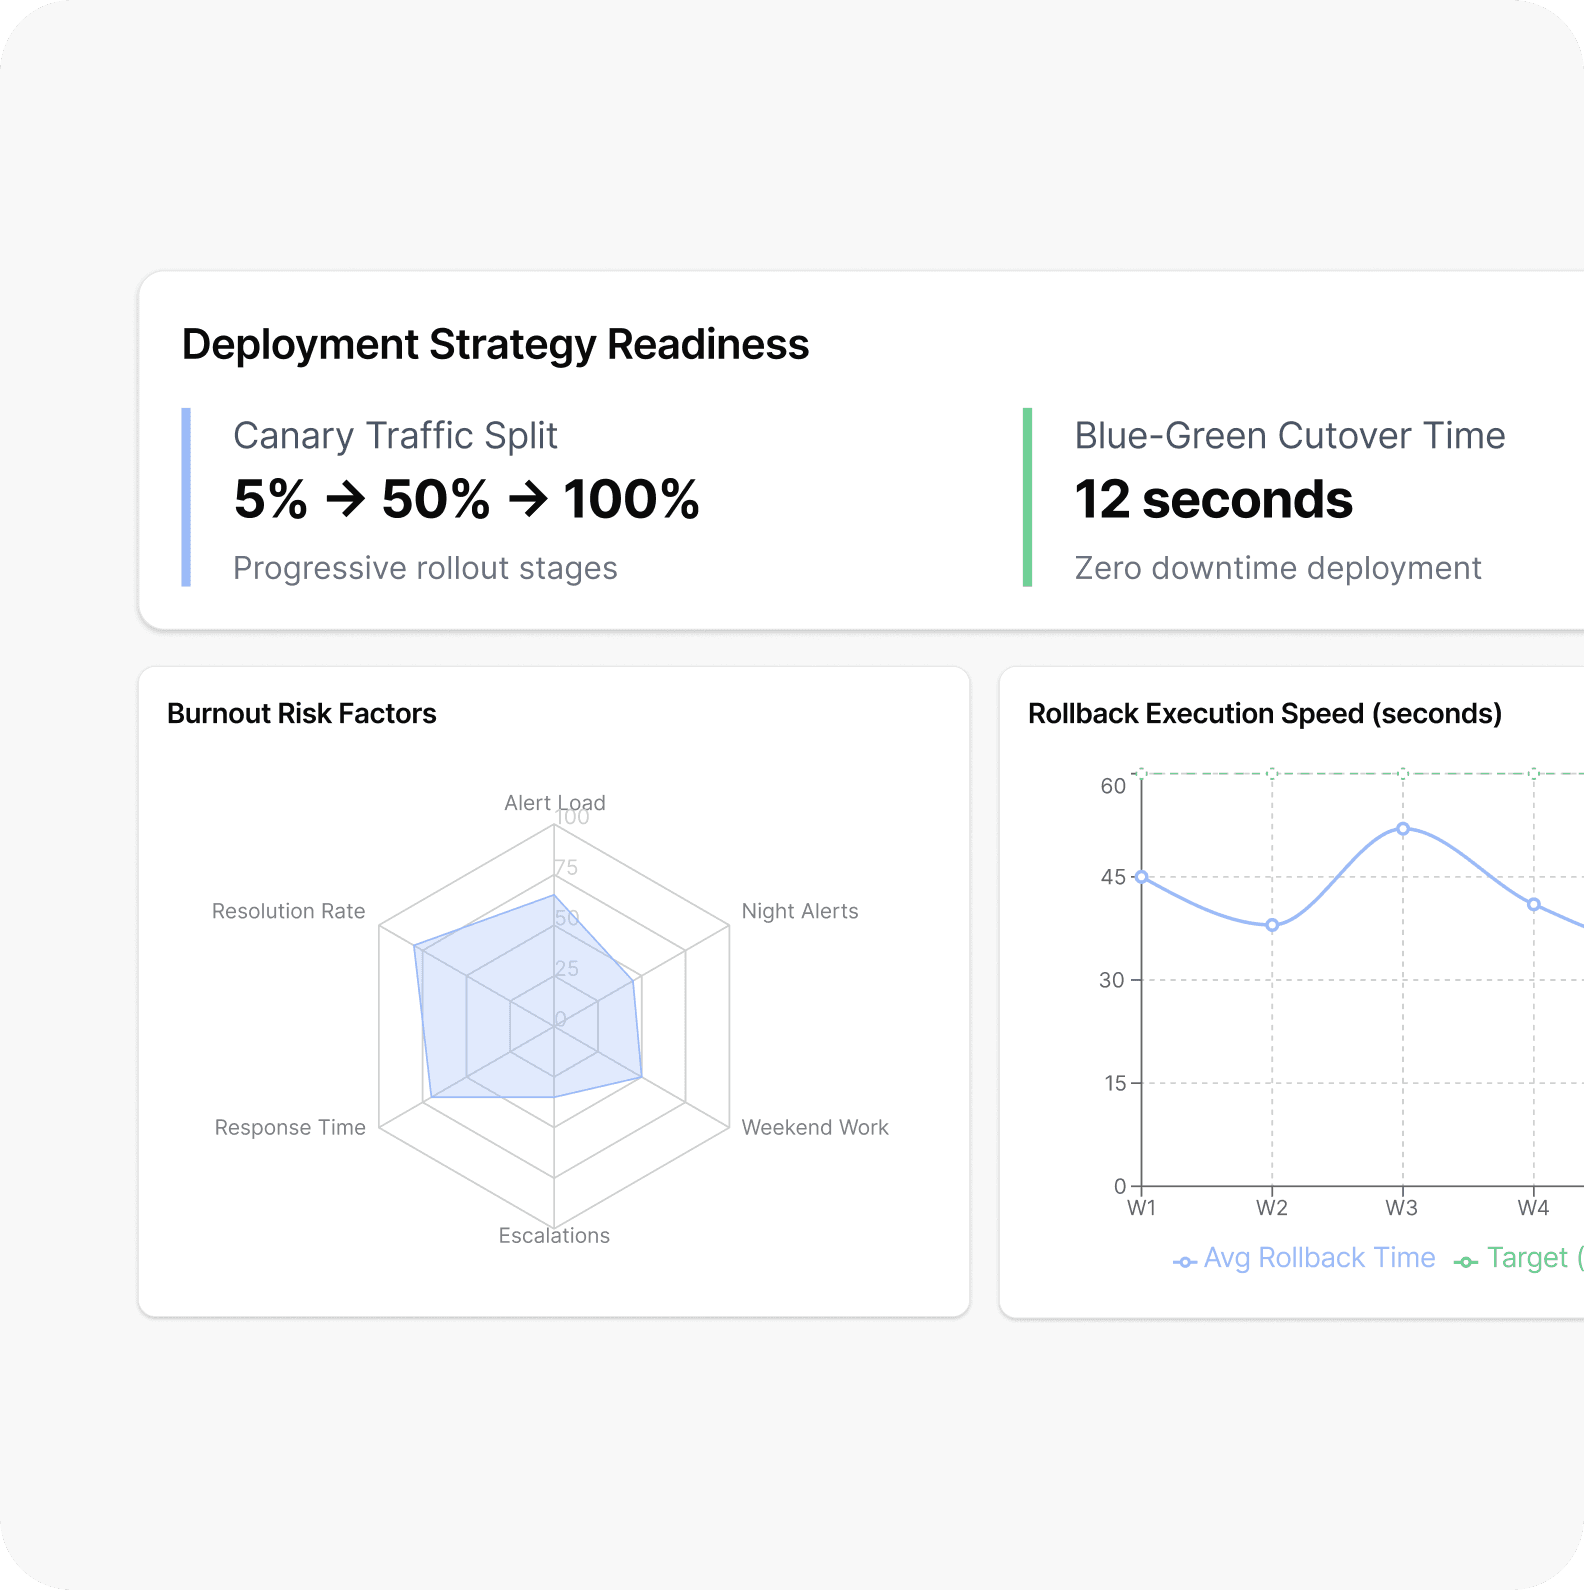
- Deployment safety assessment: Feature flag usage, canary release capability, blue-green deployment availability, and rollback execution speed
- Change management process audit: Approval workflows, production change communication, and freeze period governance
- Capacity and headroom monitoring: Resource utilization trending, saturation threshold alerting, and proactive scaling trigger configuration
- On-call sustainability evaluation: Rotation structure, alert volume per engineer, escalation frequency, and burnout risk indicators
Patterns We See Across Reliability Engagements
Based on findings across our reliability and production readiness assessments.
4-8 hrs
typical mean time to recovery on teams without structured runbooks or validated escalation paths
60-70%
share of production incidents that better alerting coverage could have caught earlier
1 in 3
systems with disaster recovery procedures documented but never tested against a realistic failure
35%
reduction in incident frequency teams can reach through targeted architectural resilience work
Reliability Outcomes We Are Accountable For Delivering
Our assessment methodology exposes every fragility before it becomes an outage that your customers experience. The deliverables we produce give your organisation the operational clarity and architectural confidence to pursue growth without reliability becoming the constraint that holds everything else back.
Know Exactly How Your System Fails Before Your Users Do
Understand every failure mode, every cascading dependency risk, and every recovery gap in your current architecture — so your team is never surprised by an incident that a structured assessment would have anticipated.
Make Every Deployment a Controlled Event, Not a Calculated Gamble
Eliminate the uncertainty that surrounds every release by establishing the safety mechanisms, rollback procedures, and deployment validation practices that turn shipping to production into a routine operation.
Build an On-Call Culture Based on Process, Not Heroics
Replace the institutional knowledge and individual dependency that sustains most incident response with documented, validated procedures that any engineer on your team can execute effectively under pressure.
Achieve the Availability Your Business Has Committed to Delivering
Align your architectural resilience, operational procedures, and monitoring coverage to the actual service level objectives your customers depend on — not the aspirational targets nobody has validated.
Industries Across Which We Deliver Reliability and Production Readiness Impact
We understand the compliance requirements around incident documentation, the commercial consequences of unplanned downtime, and the human factors that determine whether incident response procedures actually work when production is burning. Every industry in our portfolio reflects genuine, hands-on reliability engineering experience.We develop reliability strategies calibrated to the availability expectations, regulatory obligations, and operational consequences of failure that vary meaningfully across every industry we serve. Our approach consistently prioritises sustainable operational resilience over point-in-time fixes that erode under the pressure of ongoing delivery.
Reliability Assessments Backed by 1000+ Delivered Projects
Deep experience across high-stakes production environments has taught us that reliability failures almost never originate from the components engineering teams worry about most. They originate from the dependency everyone assumed was stable, the rollback procedure that had never actually been executed under pressure, the alert that had been silenced because it fired too frequently, and the runbook that described a system three architecture changes out of date.
Our practitioners bring reliability pattern recognition developed through hundreds of production resilience engagements across industries where downtime carries serious commercial, regulatory, and human consequences. Your assessment delivers a genuine operational diagnosis, grounded in your specific failure history, architecture, and team dynamics, rather than a generic checklist of reliability best practices.
Our AI-enabled engineers and reliability specialists have led resilience transformations across availability-critical platforms serving millions of users in regulated and consumer-facing environments.
Every fragility, every recovery gap, and every operational risk is characterised against your actual incident history, your real alert volumes, and your genuine deployment frequency — not against theoretical reliability frameworks.
We recommend the architectural patterns, operational procedures, and monitoring configurations that match your specific availability requirements and team capabilities — never generic SRE practices disconnected from your operational reality.
Every improvement we recommend is scoped, sequenced, and described with sufficient specificity to assign directly to an engineering team and begin without further elaboration or external guidance.
We document every finding, every architectural rationale, and every procedural recommendation so your team owns the reliability programme fully and sustainably from the moment our engagement concludes.
Our Offerings in DevOps Consulting and Services
Our Latest Thinking
FAQs About Reliability and Production Readiness Assessment Services
A Reliability & Production Readiness Assessment is a comprehensive audit of your system's architectural resilience, incident response maturity, and operational sustainability. It identifies every single point of failure in your current architecture, maps the cascading failure scenarios your system is exposed to, evaluates the completeness and accuracy of your runbooks and escalation procedures, and surfaces the gaps between the availability commitments your business has made and the operational infrastructure supporting them. You receive a complete reliability profile of your production environment alongside a prioritised improvement roadmap that sequences interventions by their impact on availability, recovery speed, and on-call sustainability.
Most assessments conclude within 2 to 4 weeks, depending on the complexity of your service architecture, the number of distinct failure domains requiring evaluation, and the volume of existing incident history and operational documentation available for review. Organizations running large microservice estates, multi-region deployments, or platforms with stringent regulatory availability requirements may require additional time to ensure every critical reliability boundary receives thorough examination. We define the engagement scope and timeline explicitly during the initial discovery session, so your team knows exactly what the process involves before work begins
We work within the access boundaries your security and compliance policies define. Read-only access to your infrastructure configuration, monitoring dashboards, alerting rules, deployment pipelines, and historical incident records is generally sufficient to conduct a thorough reliability assessment. Existing post-incident reports, runbooks, and on-call rotation documentation are particularly valuable inputs where available. For organizations operating under strict access controls — including those in regulated healthcare, financial services, or government sectors — we design the assessment methodology around the available access level and are transparent about any coverage implications that result.
We design every engagement to minimize disruption to your team's ongoing delivery and operational commitments. Typically we conduct 3 to 4 structured working sessions with relevant engineers, platform leads, and on-call representatives across the engagement period. Outside of those sessions, your teams continue operating normally. The majority of organizations we work with report contributing fewer than 5 hours of active participation across the full engagement. Where possible, we schedule sessions around your existing sprint and release cycles to avoid adding pressure during already demanding periods.
Service level commitments are a central input to every reliability assessment we conduct. We explicitly map your current architectural resilience, monitoring coverage, and incident response capability against the availability and recovery targets your SLAs define — and we identify precisely where gaps exist between what you have committed to deliver and what your operational infrastructure is currently capable of sustaining. Where SLA breach risk is identified, we prioritize the corresponding remediation recommendations and quantify both the likelihood of breach under current conditions and the architectural investment required to close the gap sustainably.
Monitoring is a necessary component of reliability but represents only one layer of a mature production readiness posture. Reliability engineering encompasses the full spectrum of practices that determine how your system behaves when things go wrong — which includes architectural fault tolerance, graceful degradation design, incident response procedures, deployment safety mechanisms, disaster recovery capability, and on-call sustainability. A system with excellent monitoring but poor architectural resilience will still experience prolonged outages when underlying components fail. Our assessment evaluates all of these dimensions simultaneously and identifies which layer represents your highest reliability risk given your current architecture and operational maturity.
You receive a comprehensive reliability findings report documenting every identified fragility, single point of failure, and operational gap across your production environment. This is accompanied by a failure mode catalogue mapping each risk to its potential customer impact, detection likelihood, and estimated recovery complexity. The improvement roadmap sequences interventions across 30, 60, and 90-day execution windows based on the combination of reliability impact and implementation effort. We also deliver an incident response maturity scorecard benchmarking your current operational practices against production readiness standards appropriate for your architecture and availability requirements. Every engagement concludes with a live readout session walking your engineering and leadership teams through every finding in detail.
Our disaster recovery evaluation combines documentation review, configuration analysis, and targeted validation exercises to assess recovery capability without requiring full disaster simulation. We examine backup coverage and retention policies, validate restoration procedure completeness and accuracy, assess RTO and RPO definitions against both business requirements and technical recovery realities, and identify discrepancies between documented recovery procedures and the actual system state they describe. Where safe and feasible within your environment, we recommend targeted recovery drills for specific components as part of the post-assessment roadmap. We also assess your chaos engineering capability and, where it is absent, provide specific recommendations for building the controlled failure testing infrastructure needed to validate resilience improvements as they are implemented.
Consistently, yes. Teams with established SRE practices represent some of our most valuable assessment engagements precisely because the gap between documented practices and their operational reality is often the most consequential finding. In our experience, organizations following SRE frameworks frequently exhibit strong reliability theory but uneven implementation — runbooks that exist but have never been executed under real incident pressure, SLO targets that are monitored but never used to drive prioritization decisions, or error budget policies that are defined but not enforced. Our assessment evaluates the operational effectiveness of your reliability practices rather than their mere existence, and the findings consistently reveal actionable improvements even within technically sophisticated engineering organizations.
On-call sustainability receives dedicated attention within every reliability engagement because an exhausted, overburdened on-call team is itself a significant reliability risk — one that rarely appears in architectural diagrams but consistently degrades incident response quality over time. We examine alert volume per engineer, the ratio of actionable to non-actionable pages, escalation frequency, rotation structure, and the availability of runbooks that allow less experienced engineers to handle incidents independently. We also assess the cultural and process factors that influence how incidents are reviewed and how recurring issues are prevented. Where on-call burnout indicators are present, we surface them explicitly and sequence the corresponding remediation work as a high-priority item in the improvement roadmap.
Multi-cloud and hybrid environments introduce reliability challenges that single-platform assessments frequently underestimate — particularly around cross-environment dependency visibility, failover path complexity, and the operational overhead of maintaining consistent reliability standards across platforms with fundamentally different service models and failure characteristics. Our assessment explicitly maps the reliability boundaries between your cloud and on-premise components, identifies failure scenarios that span multiple platforms, and evaluates whether your incident response procedures account for the additional coordination complexity that hybrid environments demand. We are experienced across AWS, Google Cloud Platform, and Microsoft Azure individually and in combination, and our recommendations account for the specific resilience capabilities and limitations of each platform your architecture relies upon.
The assessment is designed to stand alone as a fully actionable deliverable that your engineering team can execute against without requiring our continued involvement. Every finding is documented with sufficient technical depth and procedural specificity that implementation can begin immediately and progress independently. For organizations that choose to engage us beyond the assessment, we offer targeted reliability engineering support covering specific architectural hardening initiatives, runbook development programmes, chaos engineering capability building, and production readiness reviews for new services prior to launch. Whether your team executes the roadmap independently or brings us in to support specific workstreams, the assessment documentation serves as the authoritative reference throughout — because we ensure every decision, assumption, and trade-off made during the engagement is captured clearly and completely.
