Observability Assessment Services

We assess your monitoring stack, logging pipelines, and alerting systems to find exactly where visibility breaks down. Our cloud observability services give engineering teams a clear view of coverage gaps, alert noise, and wasted tooling spend, along with a prioritized plan to close each one.
4.9Clutch rating
100+Reviews
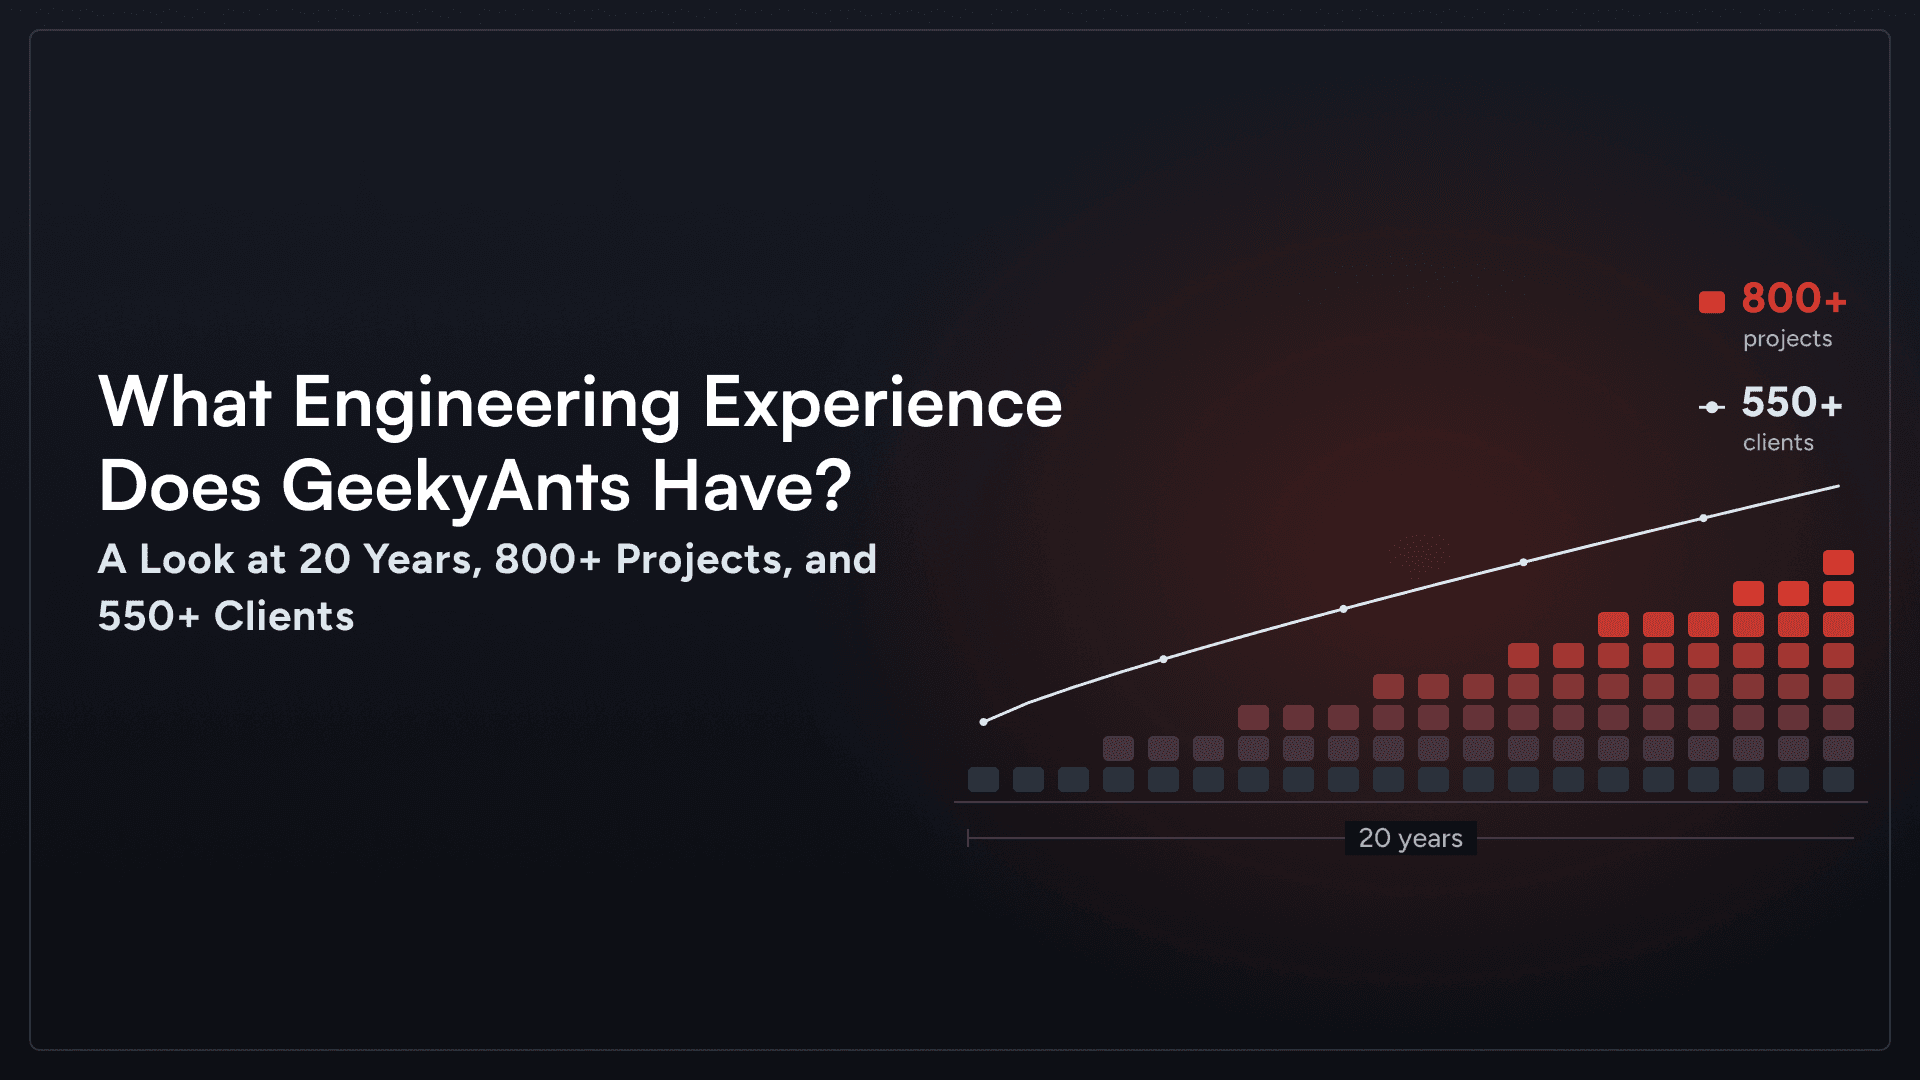
1000+Projects delivered

Free consultation

Make Your Systems Transparent and Traceable

Most engineering teams find the gaps in their observability only after a Tier-1 incident has already escalated. Our Observability Assessment reviews your monitoring, logging, tracing, alerting, and telemetry workflows to catch those weak points before they turn into outages. We replace ad-hoc troubleshooting with structured signal pipelines that cut alert fatigue and Mean Time to Resolution (MTTR). The assessment ends with a prioritized roadmap your team can act on from Day 1.

Work

Client Results and Success

View all
Production-Ready Kubernetes Architecture
Retail Platform for the Nordic Market

Production-Ready Kubernetes Architecture

The platform was designed to support scalable production deployments with minimal resource consumption, enabling faster environment provisioning and operational stability.
environments K8s setup
3
environments K8s setup
95%
savings over managed Kubernetes alternatives
35%
Read case study

WHAT WE DO

Our Observability Assessment Covers Three Core Areas

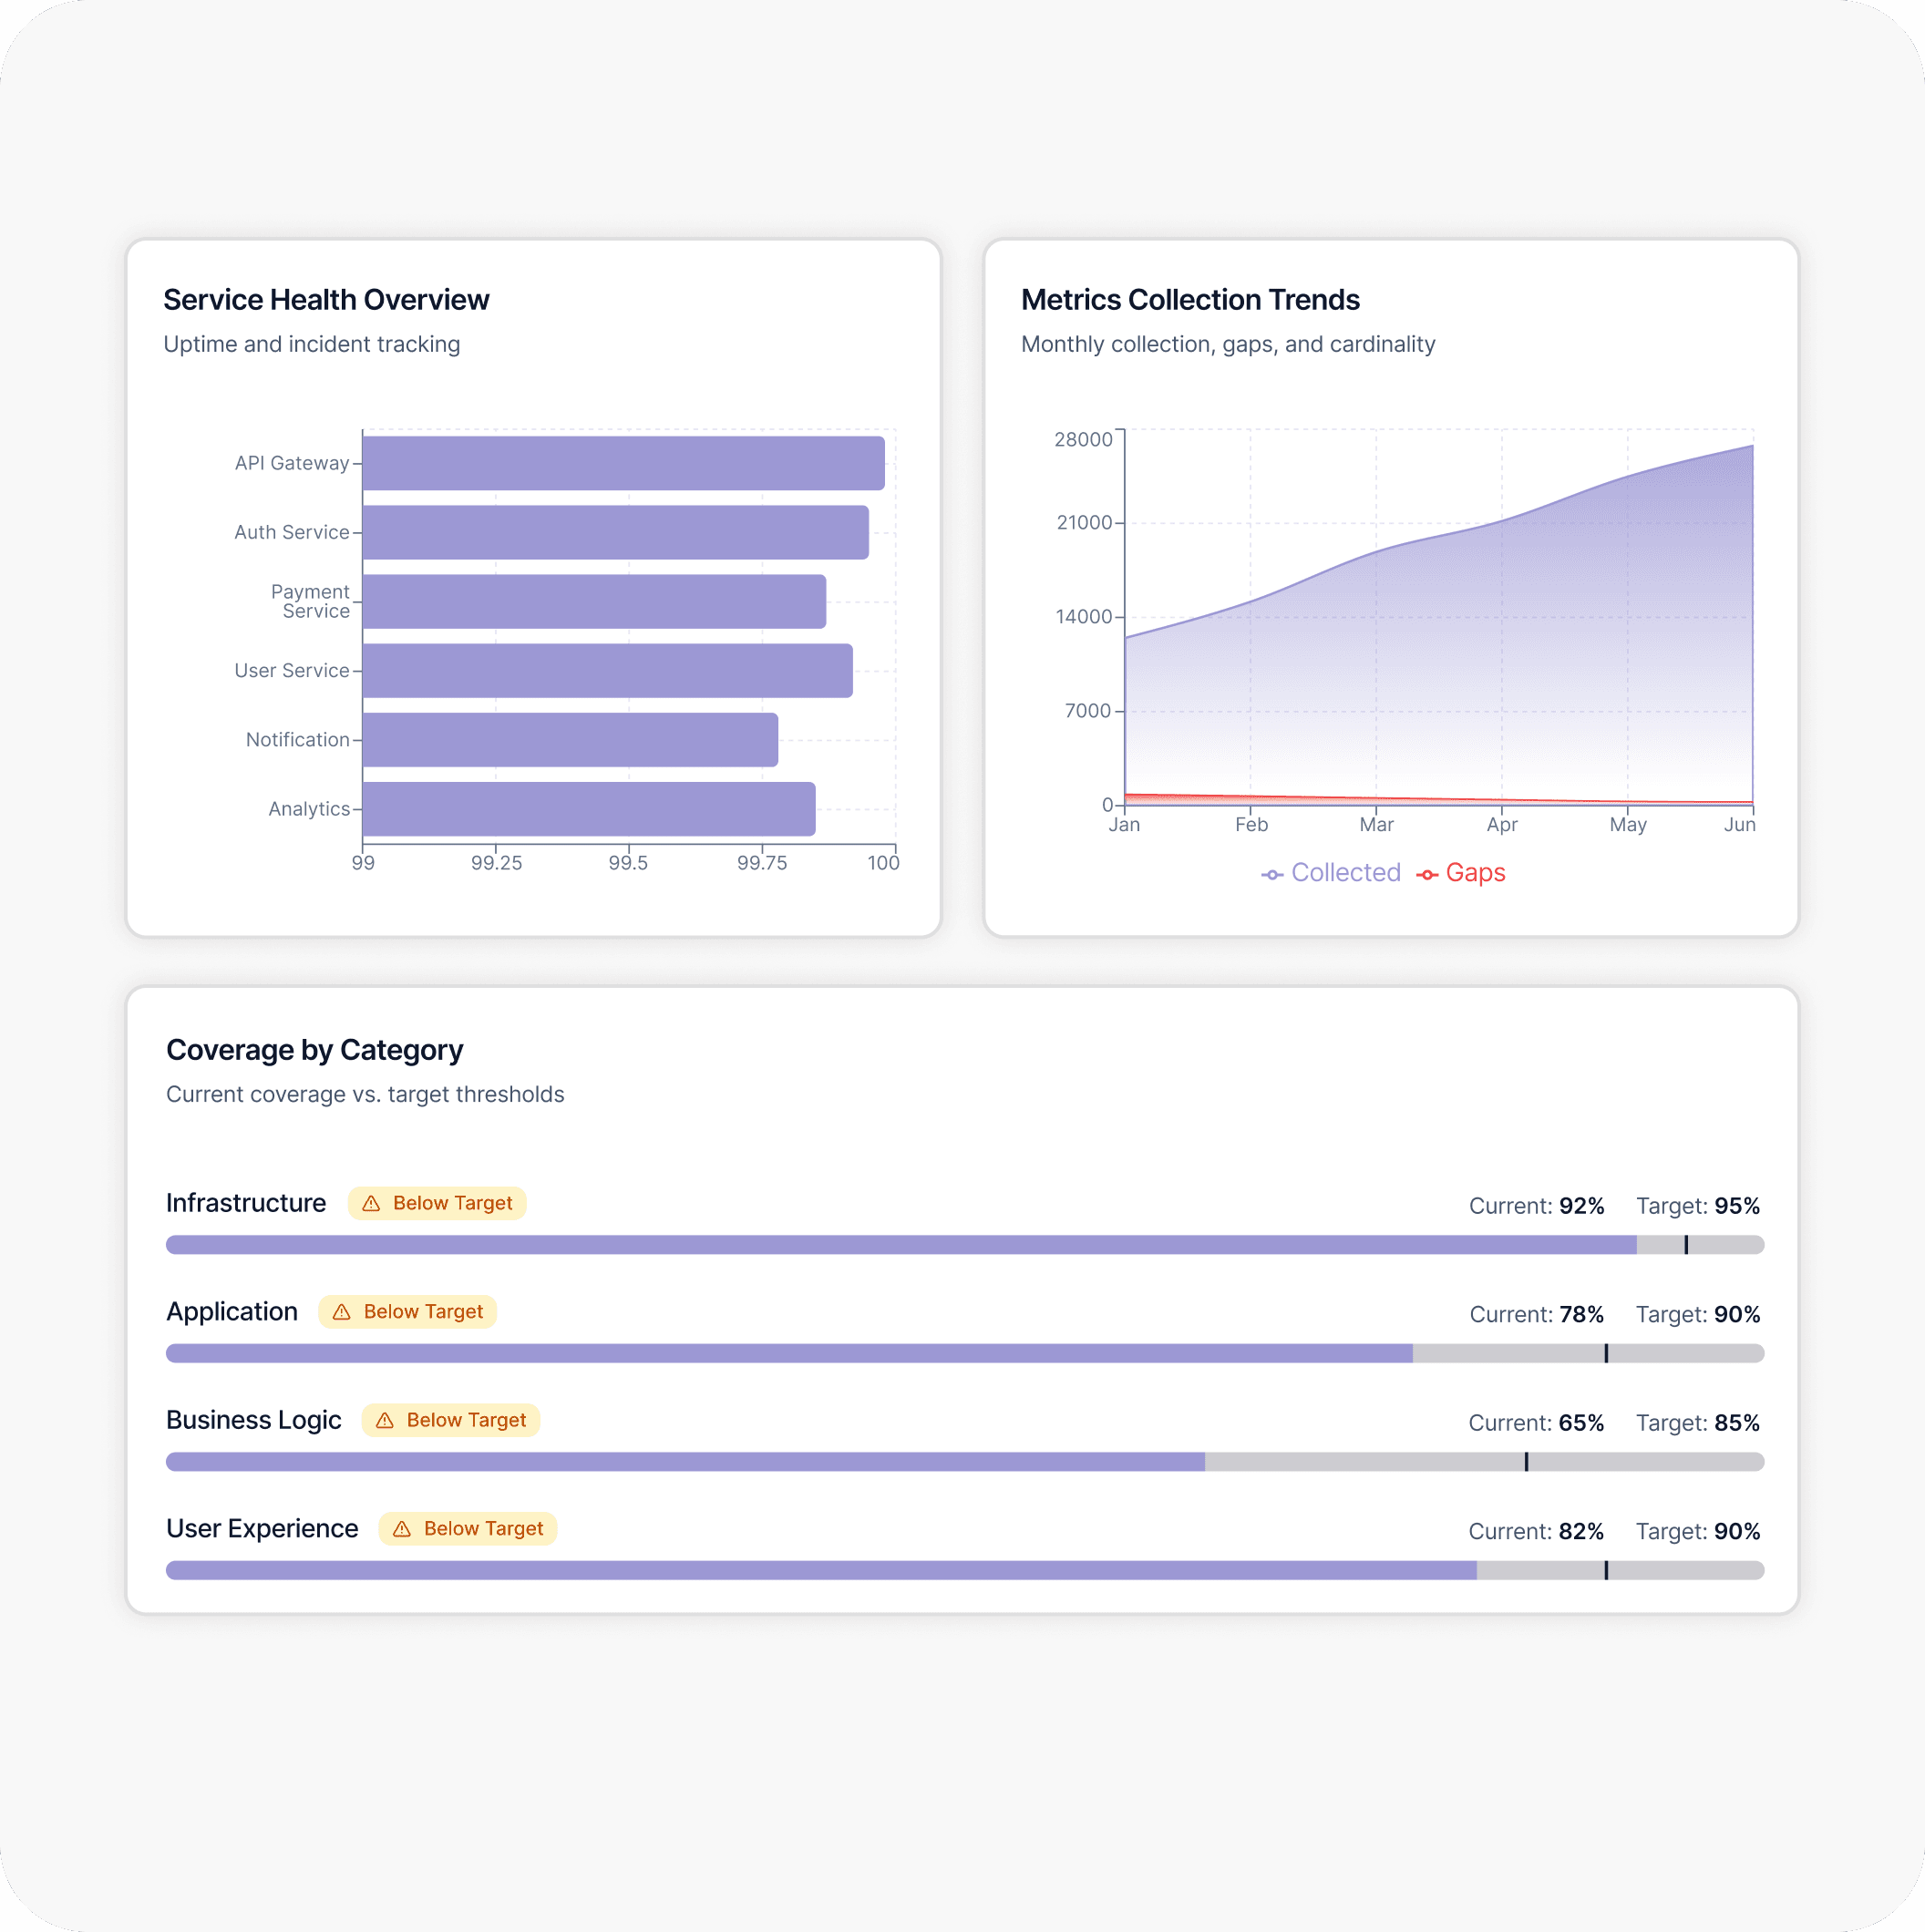
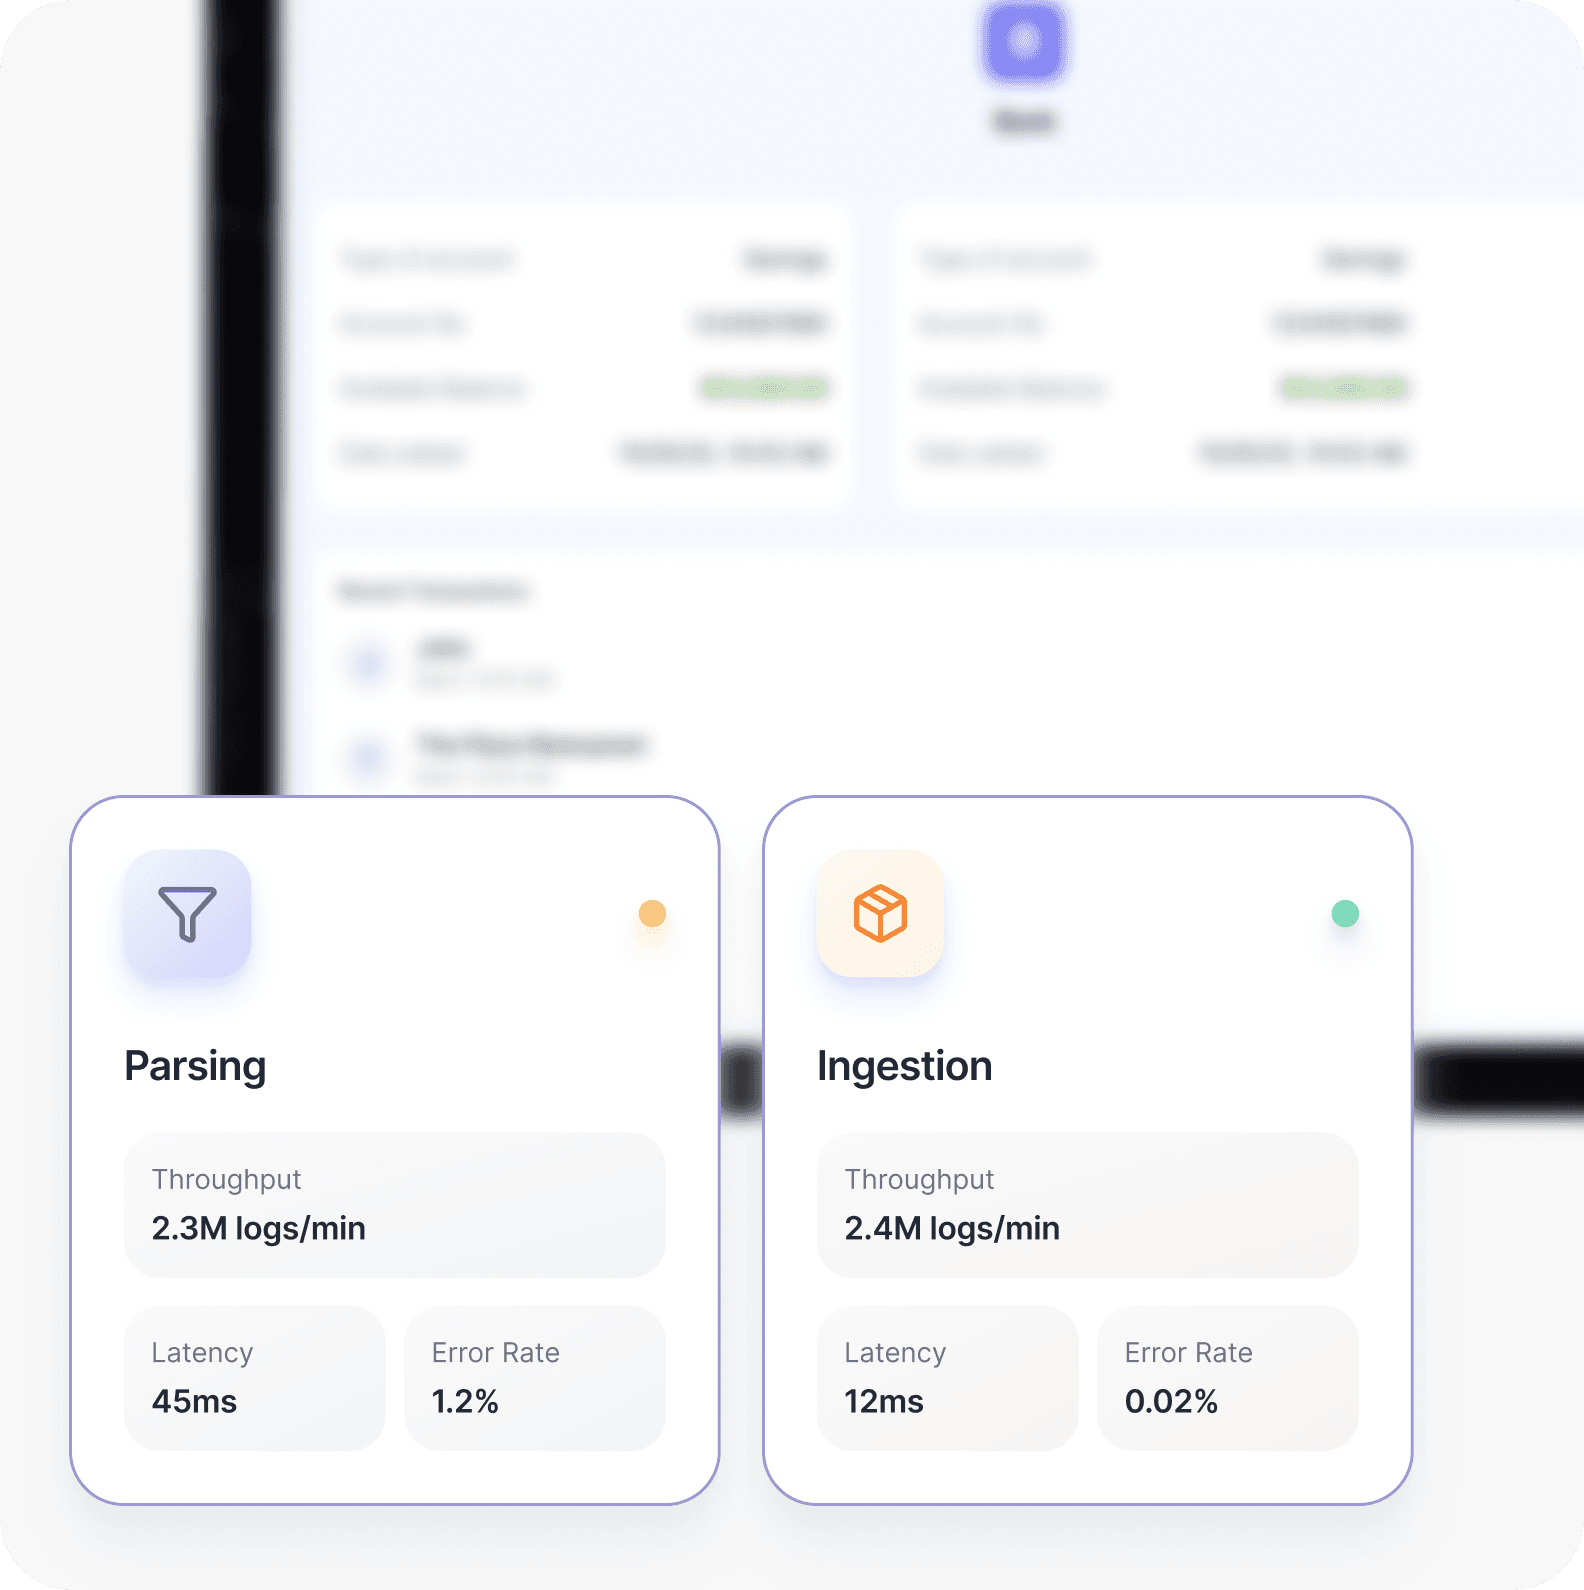
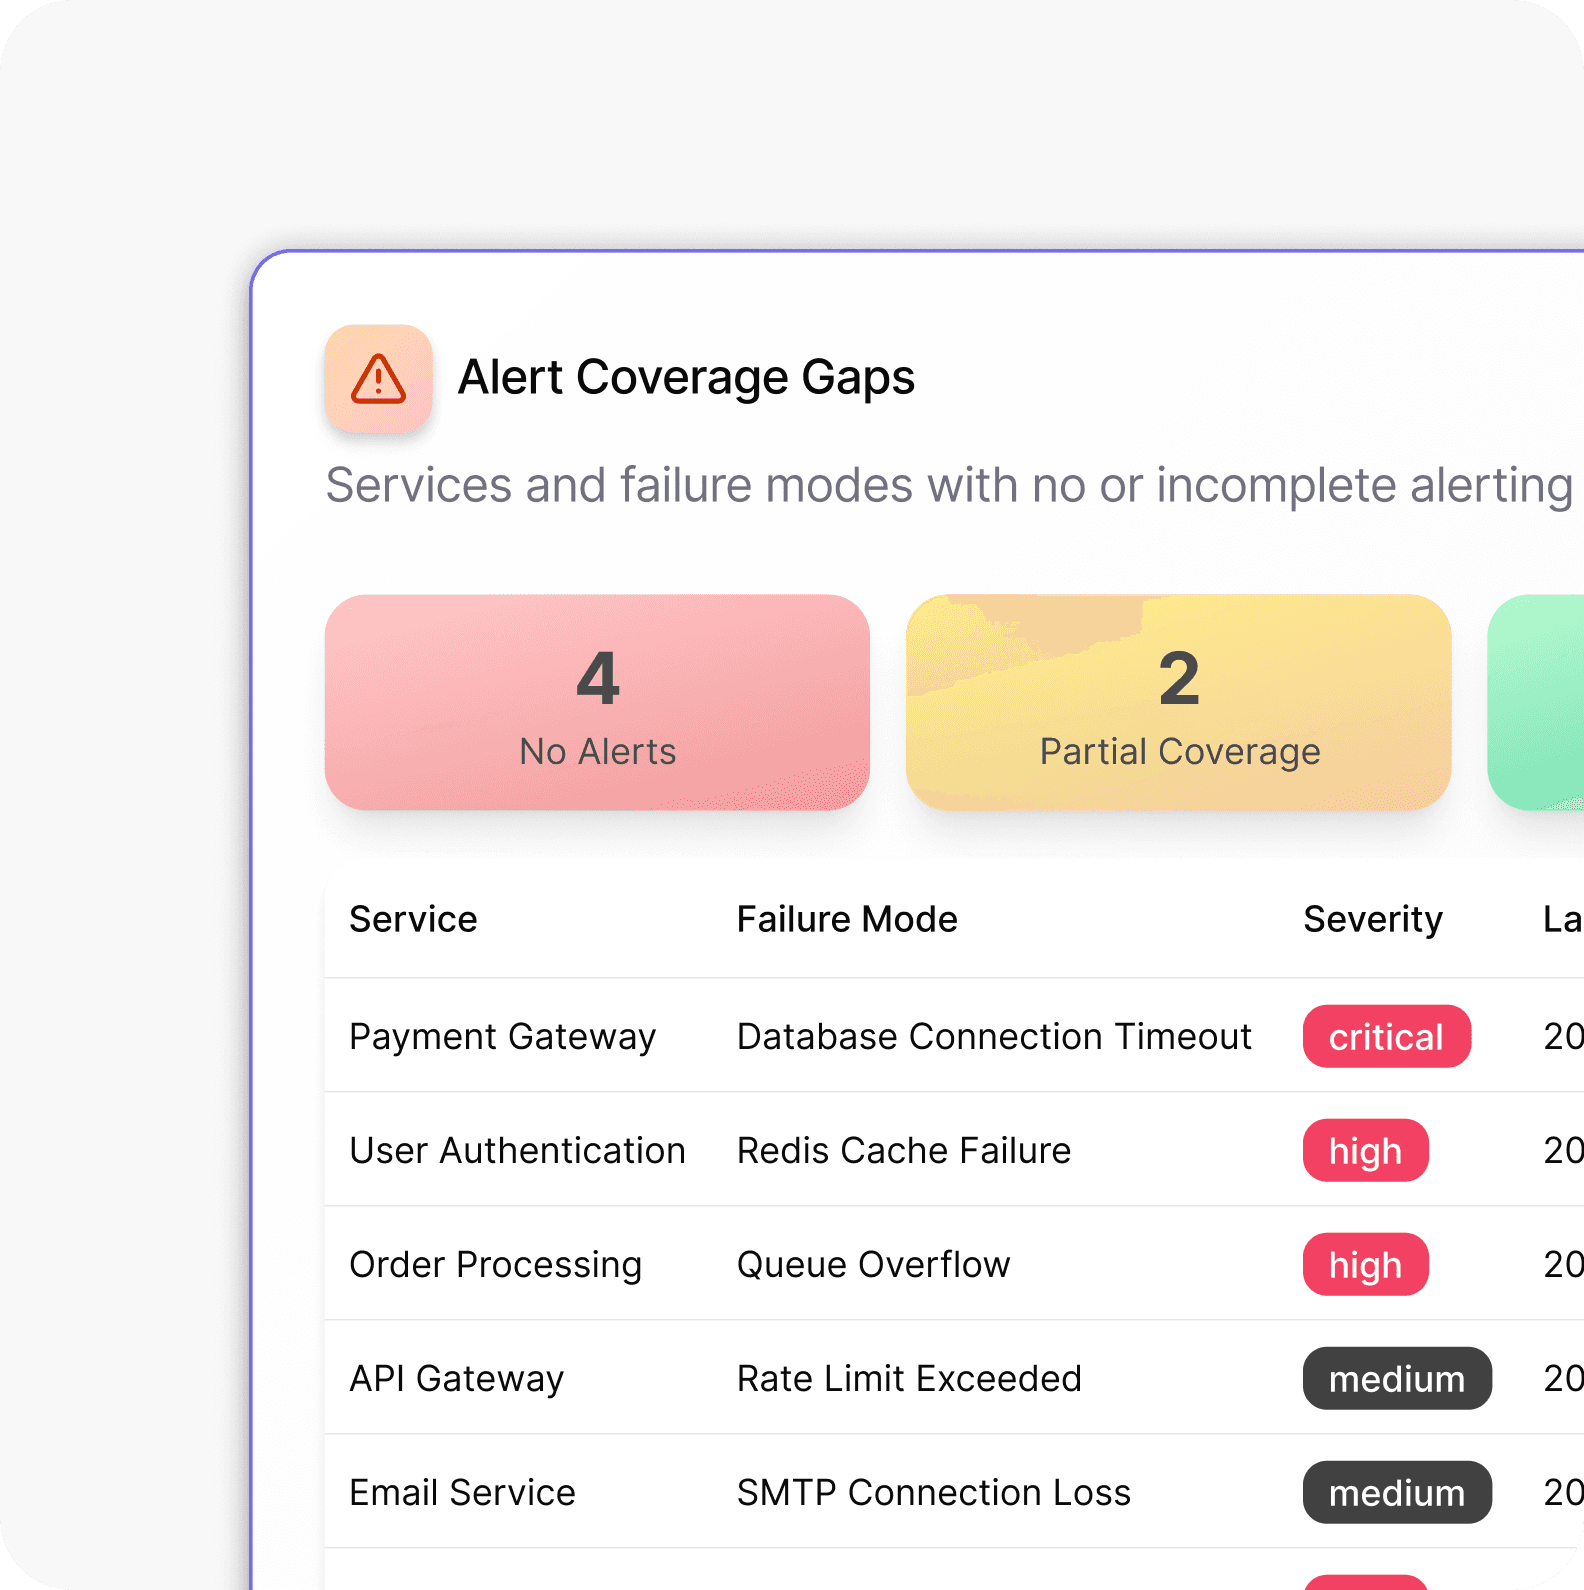
Our engineers run a deep-system review across three pillars: instrumentation coverage, pipeline efficiency, and threshold maturity. We go through your configs, log aggregation logic, and dashboard queries with your team to pin down visibility gaps, redundant telemetry, and operational risk.

Impact

What the Data Shows About Observability Gaps Today

These patterns show up across industry research and in the engagements we run. Here's what the latest data says.

40%

of engineering time spent on reactive incident response instead of product work

60–80%

of alerts require no human action at all

50%

of teams still haven't adopted OpenTelemetry for tracing

87%

of ingested telemetry is never queried

Our Promise

Improvements an Observability Assessment Can Prioritize

Our assessment maps gaps across monitoring, logging, tracing, alerting, and incident workflows, and reviews what your observability tooling is costing you. The findings go into a prioritized roadmap, so your team can see which visibility and operational issues need immediate action and which can be handled incrementally.

Clear Ownership When Things Break

Know exactly which service failed, why it failed, and who responds — so incident recovery follows a process, not instinct.

Improve Release Visibility

Strengthen monitoring, tracing, and post-deployment checks so your team can see how each release behaves in production and investigate unexpected changes faster.

Make Every Environment Fully Visible

Bring logging, metrics, and tracing into alignment across dev, staging, and production so no environment is a black box.

Stop Paying for Observability That Doesn't Observe

Get a line-by-line view of your tooling spend so every dollar is tied to meaningful signal — not noise, duplication, or unused retention.

Industries

Industries We Service

We build observability strategies around the operational realities of each industry. That means accounting for compliance demands, incident sensitivity, and the technical details specific to each sector. Our team stays involved end to end, from assessment through implementation, across every industry we list.

DevOps Assessments by Engineering Teams that Have Built 1000+ Global Projects

Our experience from working on complex engineering projects has taught us that no two infrastructures are alike. However, the problems almost always are: misconfigured pipelines, invisible cost drains, environments that drift apart, and incident processes held together by institutional memory rather than documentation. Our assessors bring pattern recognition that only comes from having seen it all. So your assessment isn't a generic checklist; it's a diagnosis built on real engineering experience.
Our AI-enabled engineers and assessors have led observability transformations at scale.
Every gap is tied to MTTR, reliability impact, or hidden cost. Engineering solutions are always mapped to business outcomes.
We recommend what's right for your context — not what we sell. If a tool you already have can do the job, we'll tell you.
The roadmap you receive is specific enough to hand directly to an engineer and start executing the same week.
We document every finding so your team fully owns the outcome — with complete clarity and no dependency on us after delivery.

Engagement

Our Offerings in DevOps Consulting and Services

DevOps Assessment

Infra, CI/CD & operations health checkRisk, cost & bottleneck identificationClear, prioritized improvement roadmap
Know More

CI/CD and Release Management

Fast, reliable deployment pipelinesSafer releases with easy rollbacksImproved developer delivery velocity
Know More

Cloud Infrastructure Management and Deployment

Day-to-day infrastructure operations & supportStable, secure cloud environmentsReduced operational overhead for teams
Know More

Deployment and Infrastructure Automation

Automated provisioning of infrastructure & deploymentsReduced manual errors and toilConsistent environments across stages
Know More

Infrastructure as Code

Version-controlled cloud infrastructureReproducible and auditable environmentsStandardized app and system configuration
Know More

Containerization and Kubernetes

Application containerizationPragmatic Kubernetes adoptionScalable and portable runtime platform
Know More

Observability- Monitoring, Logging & Alerts

Full system visibility and metricsFaster issue detection and debuggingReduced the production of firefighting
Know More

Cost Optimization and FinOps

Cloud cost visibility and trackingWaste elimination without slowing teamsPredictable and efficient cloud spend
Know More

Cloud Migration and Modernization

Low-risk cloud migrationsLegacy workload modernizationSimplified and future-ready infrastructure
Know More

Scalability and Performance Planning

Traffic and load readiness analysisBottleneck and capacity planningScale-ready architecture guidance
Know More

Reliability and Production Readiness

Production resilience and ownershipReduced outages and deployment failuresSustainable on-call operations
Know More

Security and Compliance Basics

Identity, access, and permission controlsNetwork isolation, traffic restrictions, and encryptionAudit logging and baseline compliance readiness
Know More

Insights

Our Latest Thinking

The Hidden Complexity Behind GitOps’ “Push to Deploy”
Nov 6, 2026

Insight

The Hidden Complexity Behind GitOps’ “Push to Deploy”

A GitOps platform that provisioned isolated customer environments straight from Git, and the four problems that surfaced once it was running: dependencies that weren’t ready when resources existed, configuration changes that broke existing tenants, successful deploys that hid broken integrations, and resource limits that blocked work the cluster could handle. The piece documents each fix, the ~110-second provisioning run, and is careful about which numbers are measured observations and which are calculations.

FAQ

FAQs About DevOps Assessment and Observability (Monitoring, Logging & Alerts) Services

Start a project

The Right Conversation Can Save You Six Months.