

Containerization and Kubernetes
Your infrastructure shouldn't require a specialist on call every time something needs to scale, recover, or ship.
We design and operate container infrastructure that runs predictably under pressure — so your engineering team spends less time managing environments and more time building the product.
Move From Fragile Infrastructure to Container-Native Architecture








Most container infrastructure problems don't start with Kubernetes. They start with decisions made before Kubernetes was in the picture — services that weren't designed to run in containers, clusters that were stood up without a day-two operations plan, and workloads that scaled fine in staging but fell apart under real traffic.
By the time those problems surface, they're expensive to fix and hard to explain to leadership. Our Containerization and Kubernetes service is built around preventing that outcome. We assess where your container strategy is creating risk or holding back delivery, then build the infrastructure layer your platform needs to scale — without the operational weight that normally comes with it.
Client Results and Success
Production-Ready Kubernetes Architecture
The platform was designed to support scalable production deployments with minimal resource consumption, enabling faster environment provisioning and operational stability.
- environments K8s setup
- 3
- environments K8s setup
- 95%
- savings over managed Kubernetes alternatives
- 35%
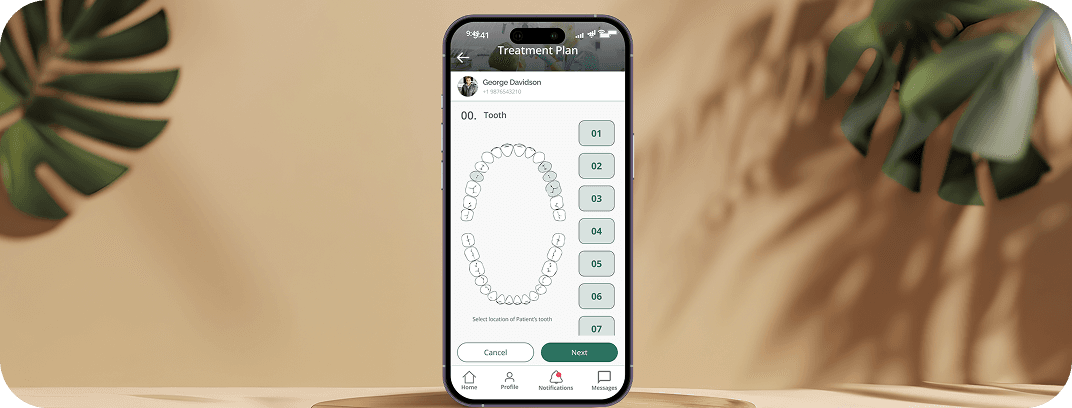
40% Faster Onboarding Completion
The redesigned system achieved a 40% reduction in onboarding completion time, directly improving platform adoption and reducing operational bottlenecks.
- Improvement in the doctor's efficiency for treatment planning
- 35%
- Reduction in onboarding completion time
- 40%
Production-Grade AI Infrastructure
The system supports scalable AI inference and automated inspection workflows, reducing manual intervention and enabling consistent performance under growing usage.
Read case study3× Faster Feature Iteration
The platform achieved 3x faster AI feature iteration cycles, significantly reducing time-to-release for new recommendation
- Reduction in meal decision time
- 40%
- Increase in daily active usage during pilot
- 2x
50% Fewer Manual Validation Cycles
The system achieved a 50% reduction in manual validation cycles, improving throughput and accelerating delivery timelines.
- Reduction in manual validation cycles
- 50%
- Faster internal testing workflows
- 30%
60% Cloud Cost Reduction
The platform achieved a 60% reduction in monthly cloud costs while maintaining uptime and transaction stability during and after optimization.
- Saved per month
- $4,800
- Annual savings
- $57,000+
Our Containerization and Kubernetes Services
Running containers in production is a different discipline from getting them working in a demo. The failure modes are different, the operational requirements are different, and the cost of getting it wrong shows up in ways that are hard to trace back to their origin. Our services are built for teams that need container infrastructure to actually hold up — at scale, under load, and without requiring constant expert attention.
- Workload assessment and container migration planning, from legacy services to greenfield architecture.
- Dockerfile optimisation, image hardening, and registry management for secure, lean container builds.
- Service decomposition guidance for teams transitioning toward a container-native architecture.
- Local development environment alignment, so that what runs on a developer's machine behaves the same way in production.
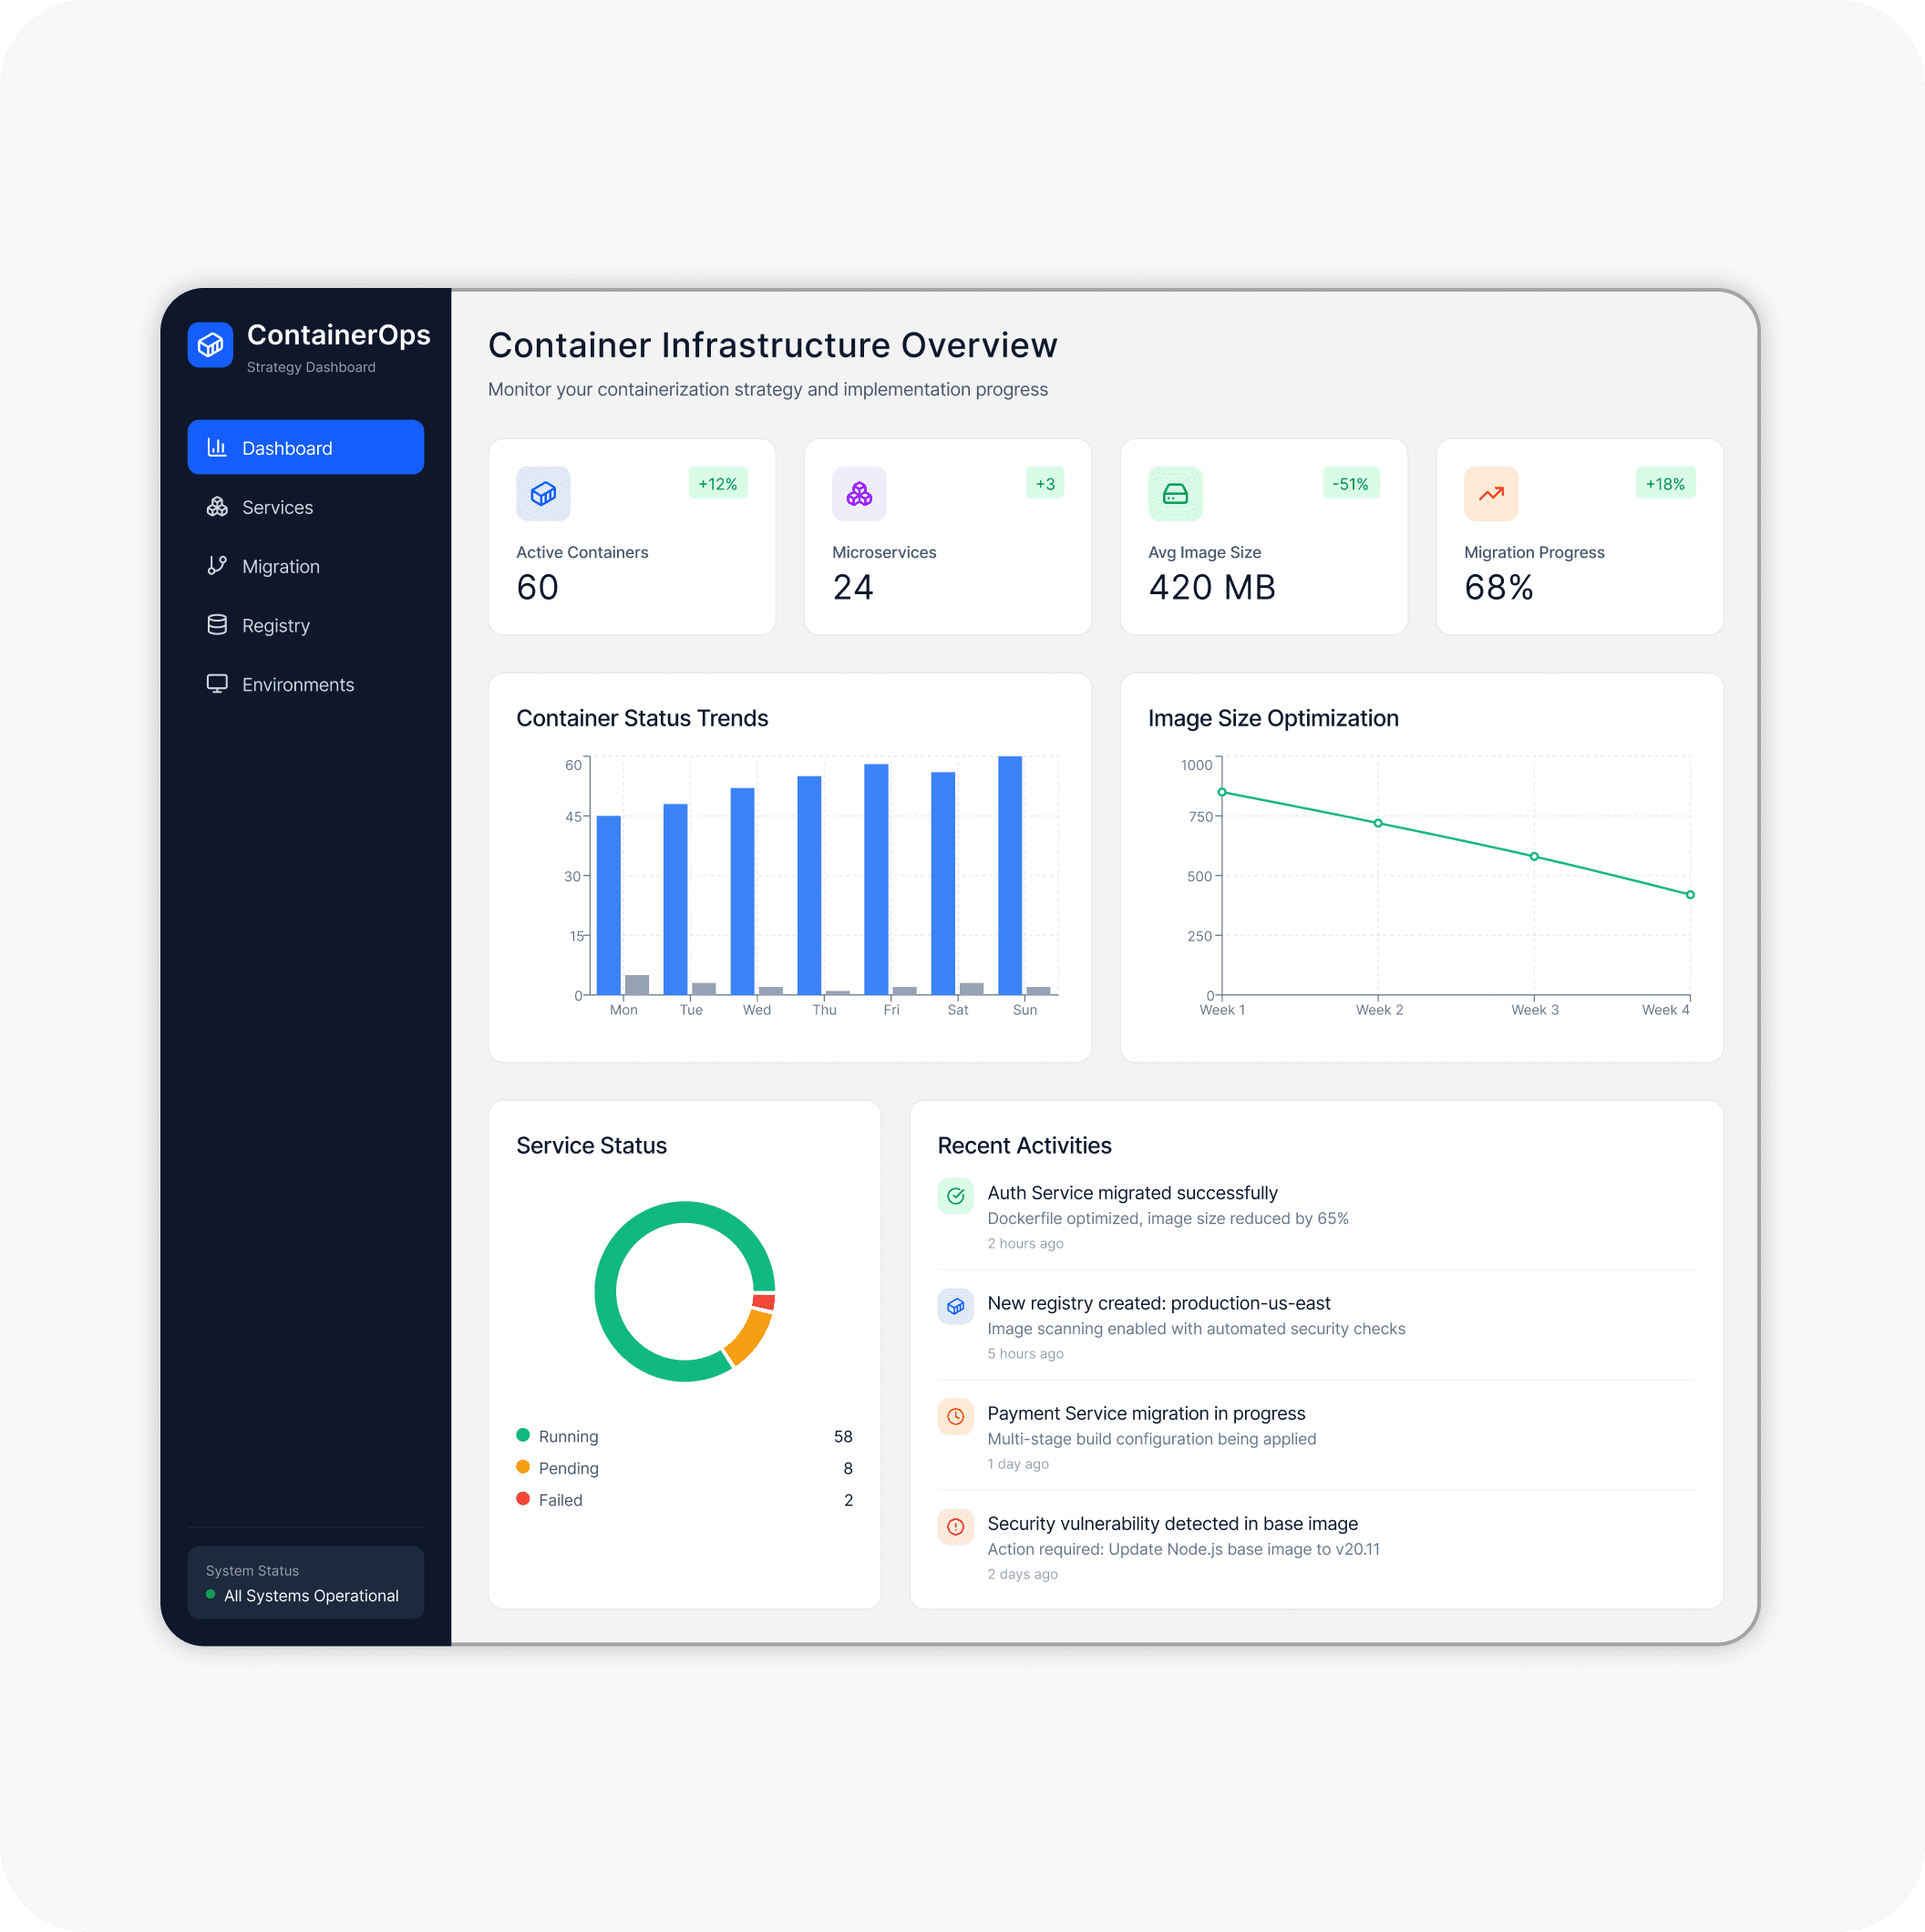
- Cluster architecture for production-grade workloads across AWS EKS, Google GKE, Azure AKS, and self-managed environments.
- Namespace strategy, RBAC configuration, and multi-tenancy design for teams and services sharing cluster resources.
- Helm chart development and management for standardised, version-controlled release packaging.
- Ingress configuration, internal service routing, and traffic management built for reliability at scale.
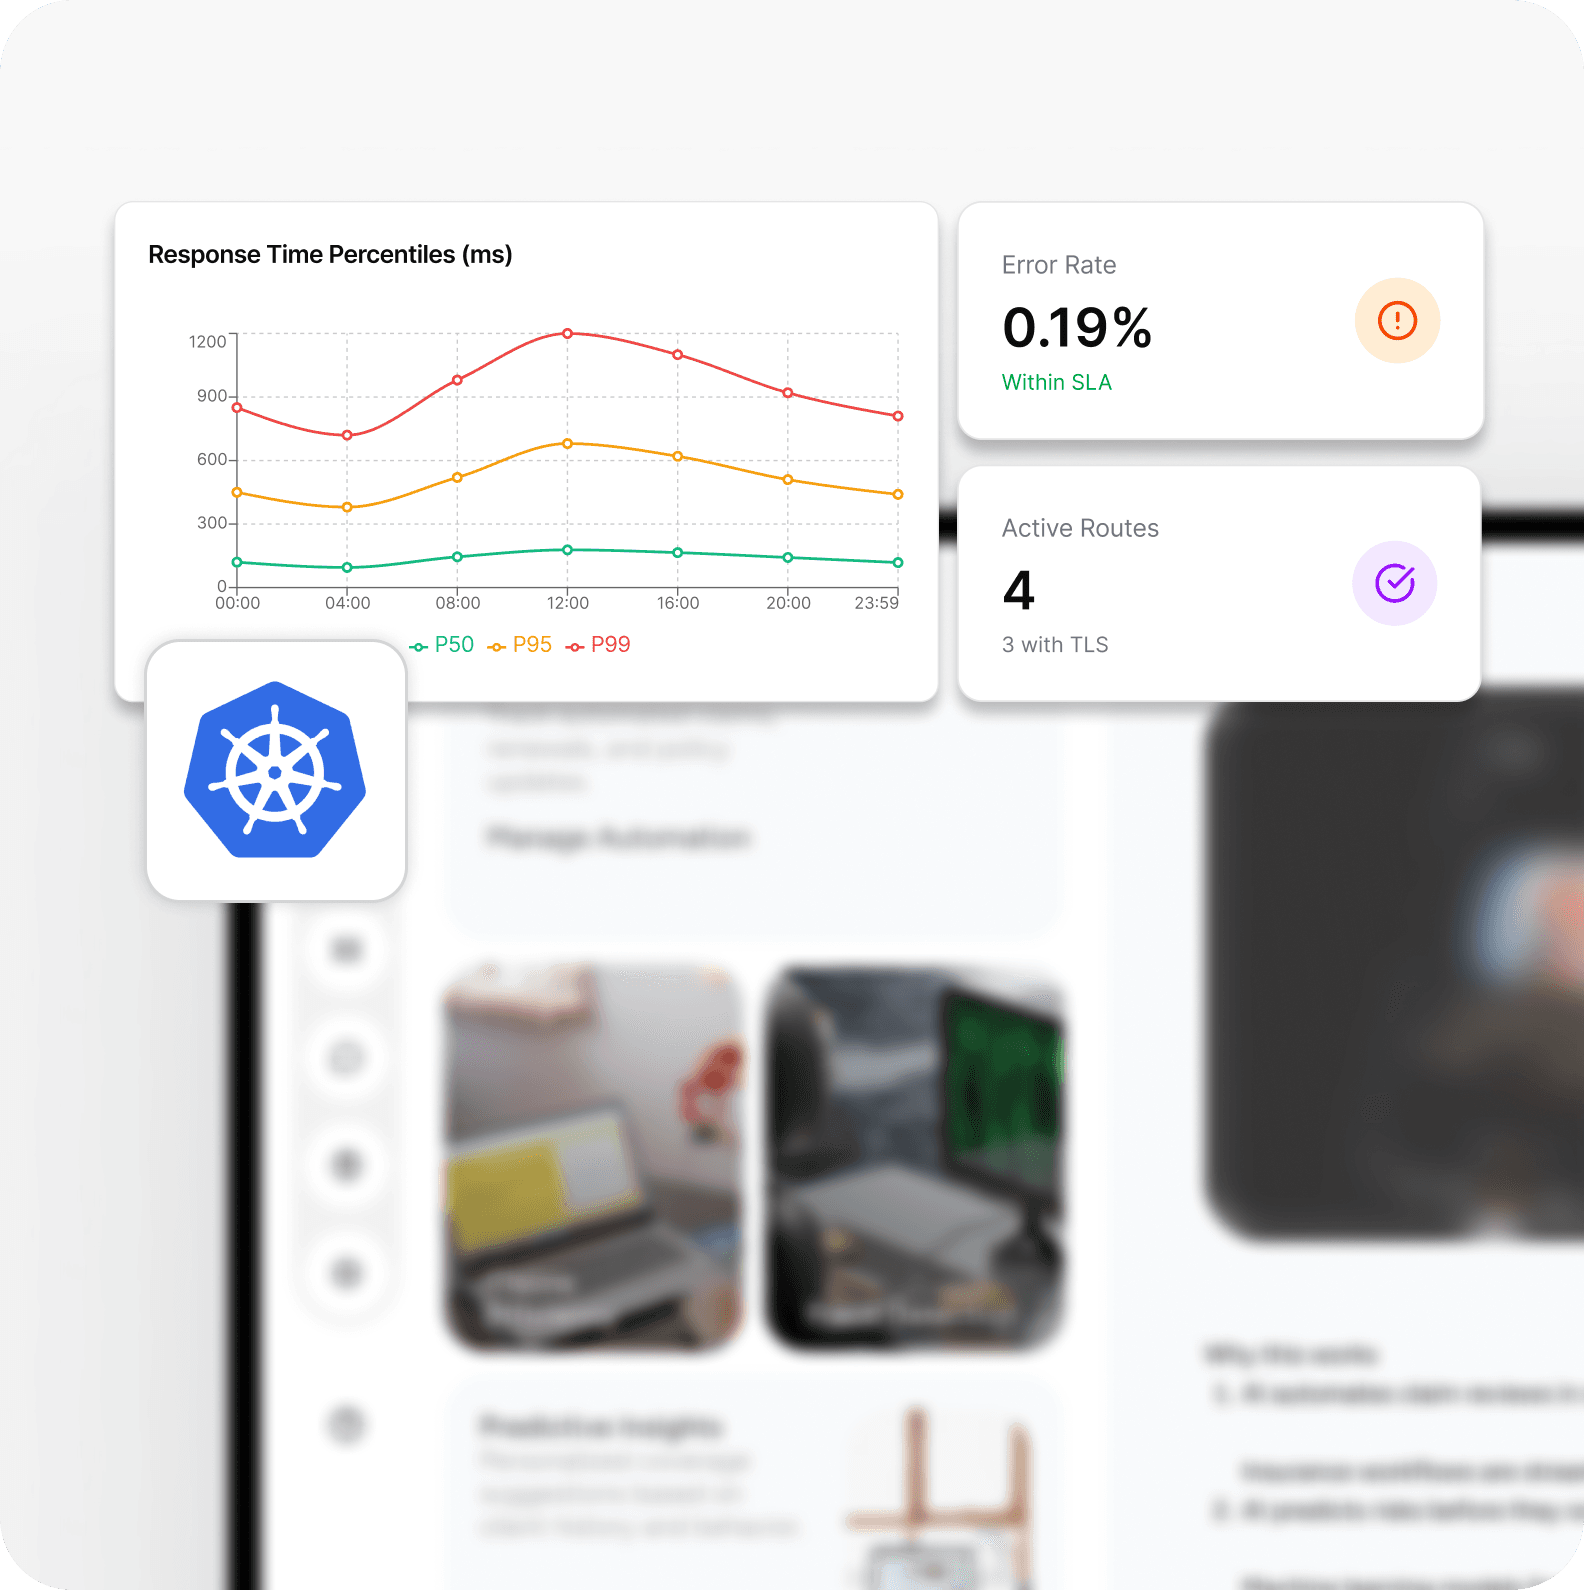
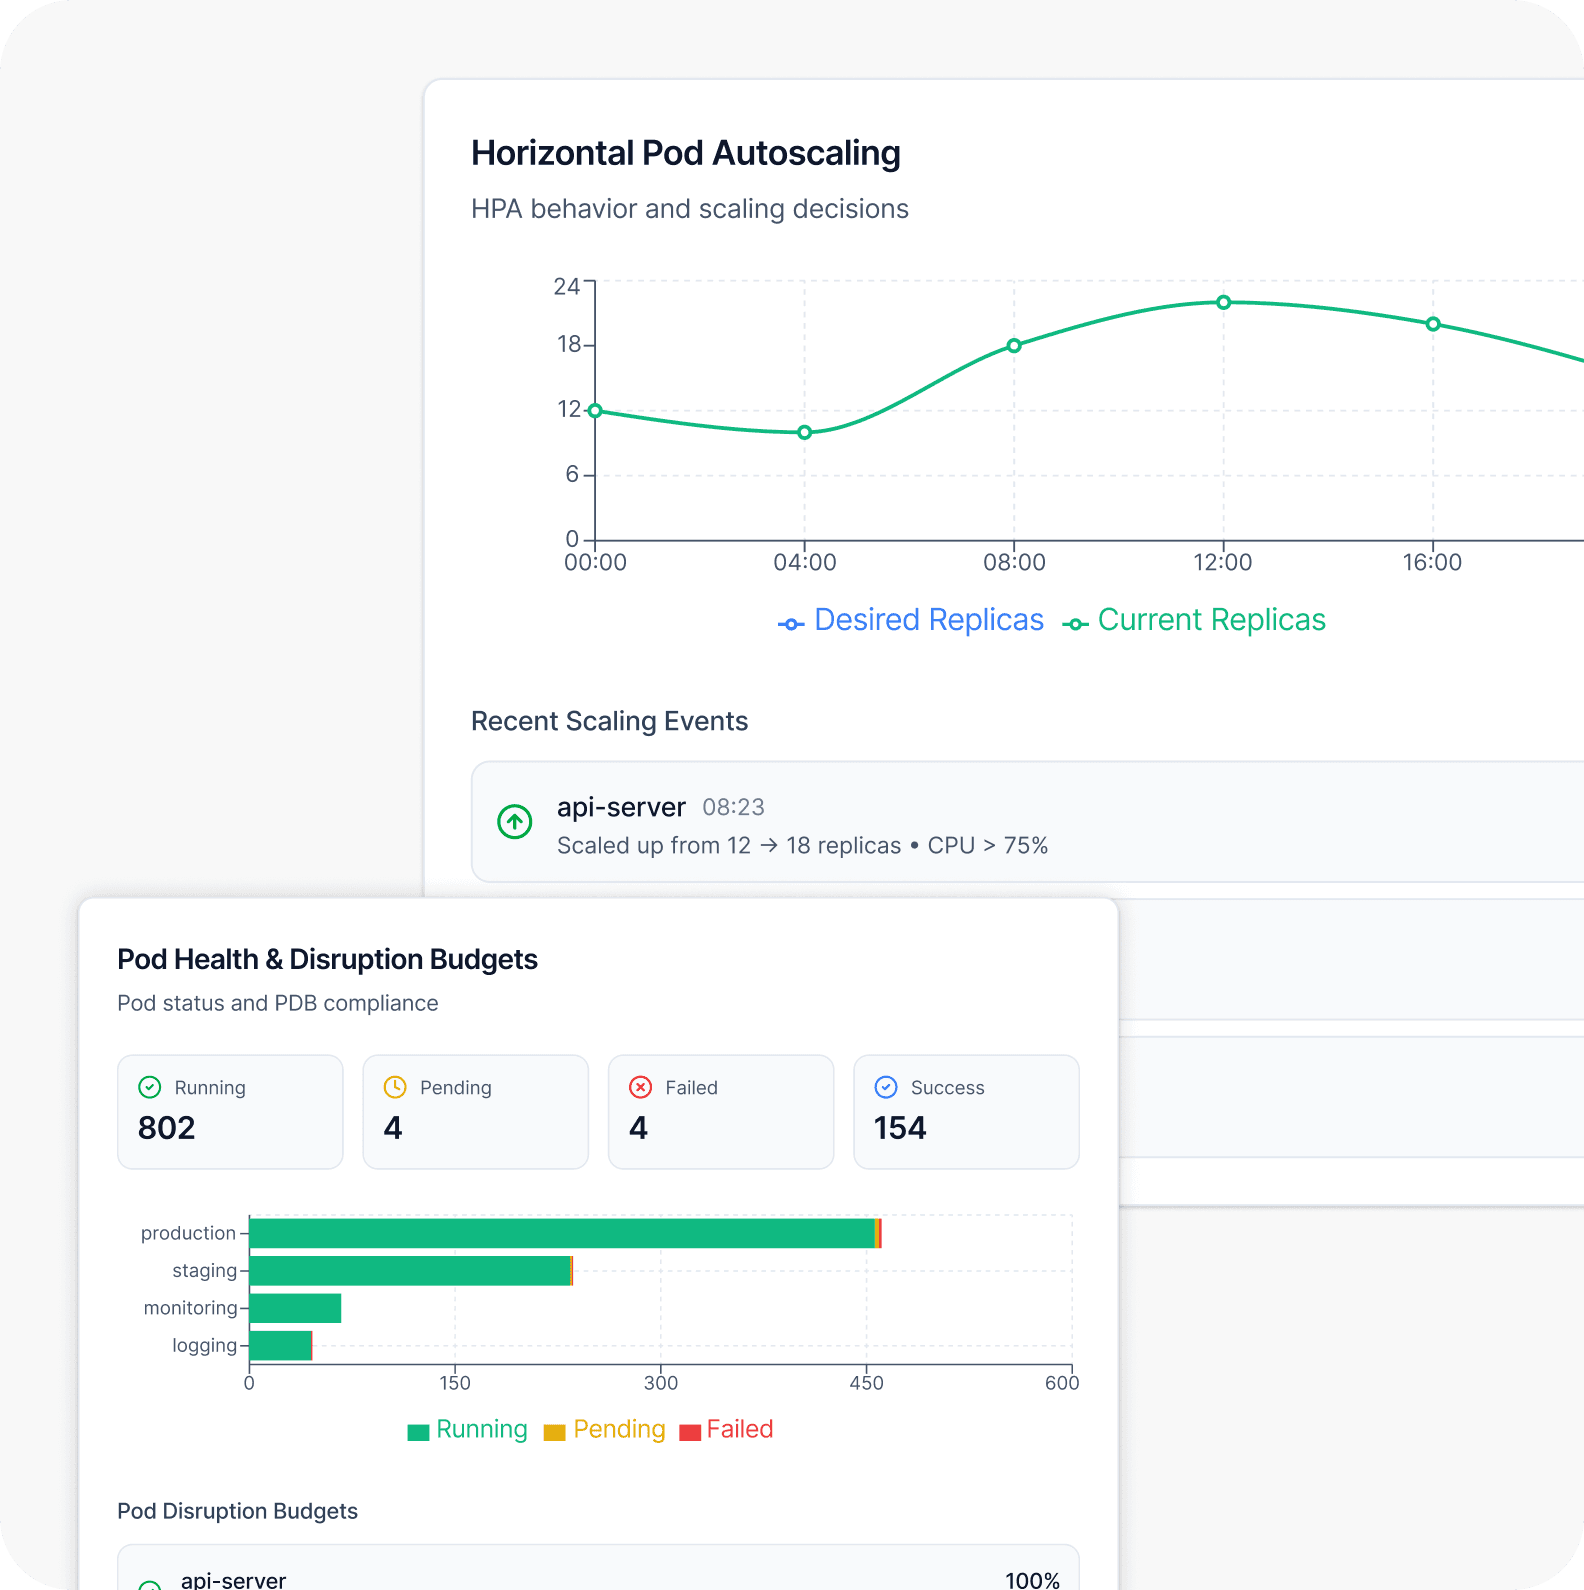
- Horizontal and vertical autoscaling configured to workload behaviour — not arbitrary thresholds.
- Pod disruption budgets, resource limits, and liveness and readiness probes that keep services stable under pressure.
- Node pool management, cluster autoscaling, and cost optimisation aligned to real usage patterns.
- Documented runbooks, on-call escalation paths, and operational procedures your team can own without us.
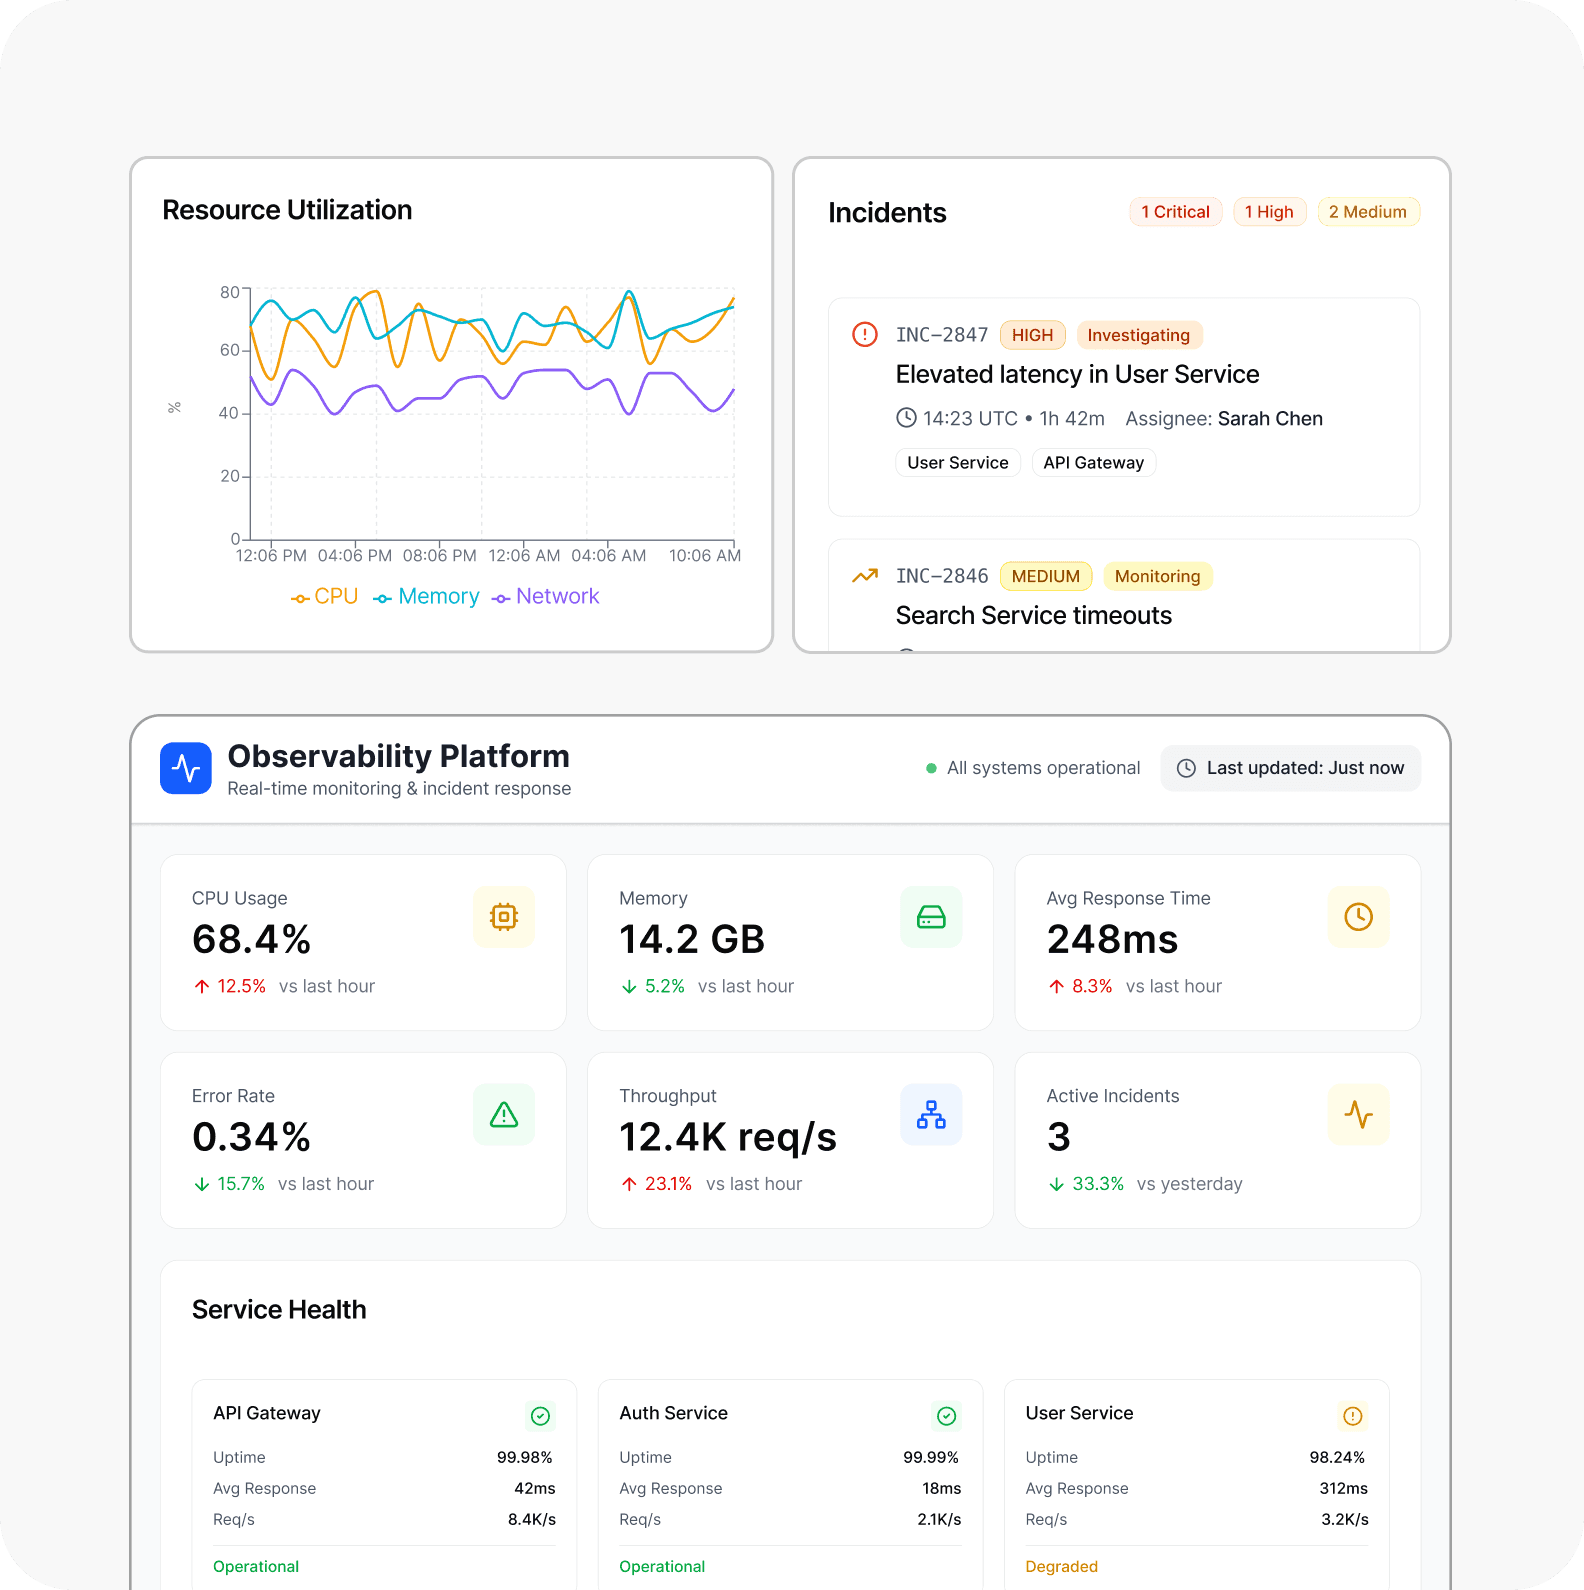
- End-to-end observability across your container layer — metrics, logs, and distributed traces surfaced where they matter.
- Alerting is configured to signal meaningful events, not noise, with escalation routing built into the workflow.
- Automatic rollback on failed deployments, with post-incident review tooling to prevent recurrence.
- Prometheus, Grafana, Datadog, and other tooling are integrated into your existing operational stack.
Containerization And Kubernetes Across Every Industry
CTOs and engineering leaders don't invest in Kubernetes because it's technically interesting. They invest because unreliable infrastructure is expensive — in engineering time, in incident response, in delayed releases, and in cloud spend that doesn't map to value delivered. This is what changes.
Infrastructure That Holds Up When Traffic Doesn't Behave
Properly configured autoscaling and pod-level resilience mean your platform responds to demand spikes without manual intervention and recovers from failures without your team being paged at 2 am.
Release Confidence Across Every Environment
Container-native delivery means the same image that passed testing is what reaches production. Environment-specific failures stop being a regular occurrence.
Infrastructure Costs Proportional to Real Demand
Right-sized containers and intelligent autoscaling mean you pay for what your workloads need when they need it — not for headroom that exists to compensate for infrastructure you don't fully understand.
Engineering Time Back Where It Belongs
When your container infrastructure is designed properly and documented thoroughly, it stops consuming engineering attention. Your senior engineers work on problems that move the product forward, not on keeping the cluster stable.
Kubernetes and Containerization Across Every Industry
Container infrastructure requirements vary significantly depending on the industry. A fintech platform running under PCI-DSS has fundamentally different cluster security requirements than a consumer app optimising for release velocity. A healthcare system operating under HIPAA needs audit trails and access controls baked into the container layer. A high-traffic e-commerce platform needs autoscaling that responds in seconds, not minutes.We design container infrastructure around the operational and compliance reality of the industry you operate in — not a generalised Kubernetes template adapted after the fact.
Kubernetes Engineering from a Team That Has Operated It in Production Across 1000+ Projects
There's a significant gap between teams that have deployed Kubernetes and teams that have operated it — through scaling incidents, misconfigured RBAC, node pool exhaustion, and workloads that behaved perfectly in staging and failed in ways nobody anticipated in production.We sit firmly in the second category. The experience we bring to your engagement isn't theoretical. It comes from years of operating container infrastructure across industries, platform types, and scale ranges where the cost of getting it wrong was real.
The engineers assessing your container infrastructure are the same engineers designing and implementing the solution. There's no account management layer between the conversation and the keyboard.
Cluster design, namespace strategy, scaling configuration, and day-two operations planning are built around your team's size, your release cadence, and your platform's actual traffic behaviour — not a generic configuration that approximately fits.
We work across EKS, GKE, AKS, and self-managed Kubernetes, with hands-on depth in Helm, ArgoCD, Istio, Prometheus, Grafana, Datadog, Terraform, Pulumi, and more. Recommendations are driven by what your environment needs — not tooling preferences.
Every cluster, Helm chart, runbook, and configuration file we deliver is production-ready and documented for long-term operation by your team. The handover is complete — not a starting point that still requires our involvement.
Structured knowledge transfer, operational documentation, and architecture decision records give the engineers inheriting the system the context to operate it confidently and make good decisions about where it goes next.
Our Offerings in DevOps Consulting and Services
Our Latest Thinking
FAQs About Containerization And Kubernetes
Not necessarily — but it depends on where you're headed. Containers without orchestration work well up to a point. When services multiply, traffic patterns become unpredictable, or release cadence increases, the absence of orchestration tends to show up as operational overhead and scaling constraints. We help teams assess whether Kubernetes is the right next step and, if it is, how to make the transition without disruption.
Having a cluster running and having a cluster running well are meaningfully different things. Most Kubernetes environments that grew organically carry misconfigured autoscaling, inadequate observability, and RBAC that reflects decisions made under time pressure rather than security principles. Those gaps are often invisible until a scaling event or incident makes them visible.
We design engagements to minimise disruption to ongoing releases. Containerization typically happens service by service, with existing workloads remaining operational throughout. Where cutover risk is a concern, we build migration paths that keep both environments running in parallel until the transition is confirmed stable.
Getting a cluster running is the straightforward part. Day-two operations cover everything that follows: scaling behaviour under real load, certificate rotation, node pool upgrades, cost optimisation, incident response, and keeping the cluster aligned with your platform as it evolves. We design for day-two from the start, not as an afterthought.
We build compliance controls directly into the container layer — network policies, pod security standards, secrets management, image scanning, and audit logging designed for SOC2, ISO 27001, HIPAA, or PCI-DSS requirements. Compliance is an architecture decision, not a checkbox applied at the end.
We work across Amazon EKS, Google GKE, Azure AKS, and self-managed Kubernetes on bare metal or private cloud. Tool selection — Helm, ArgoCD, Istio, service mesh, observability stack — is driven by your requirements, not a standard configuration we apply to every engagement.
Production-ready cluster architecture, containerised workloads, Helm charts for all services, autoscaling configuration, observability and alerting setup, RBAC and security policy implementation, operational runbooks, and a structured handover session with your engineering team.
Most engagements run between four and eight weeks, depending on the number of services being containerised, the complexity of the cluster architecture required, and whether compliance or multi-region requirements are in scope.
That's the standard we hold every engagement to. Documentation, runbooks, and knowledge transfer sessions are built into every delivery — not offered as optional extras. The goal is a team that can operate, extend, and make confident decisions about their container infrastructure without relying on us.
A specialist hire takes months to get to the point where they're making meaningful changes to production infrastructure. We arrive with that context already established, deliver a fully operational and documented system in weeks, and transfer ownership completely at the end. Without the recruiting overhead, notice period delays, or gradual ramp-up curve.
