

Redis for Product Scaling
We implement Redis caching, messaging, and session architecture that removes the read pressure from primary databases — cutting average latency to 1ms, reducing database load by 90%, and keeping user sessions consistent across distributed server fleets.
Overcome Database Bottlenecks and Latency








Most application performance problems trace back to one source: the primary database handling traffic it was never designed for. Read queries that run on every page load. Session lookups that hit the database on every authenticated request. Inventory checks during a flash sale that produce race conditions because nothing is serialising concurrent writes.
We solve each of these at the right layer via Redis. Write-through and look-aside caching patterns offload read traffic from the primary database — frequently accessed data is served from memory without a database round trip. Pub/Sub and Redis Streams handle real-time messaging between services without the overhead of a full message broker. Sorted Sets update leaderboard rankings in real time for millions of users with a single atomic operation. Atomic counters prevent inventory overselling during flash sales by serialising concurrent decrements at the data structure level — no application-layer locking required.
Client Results and Success
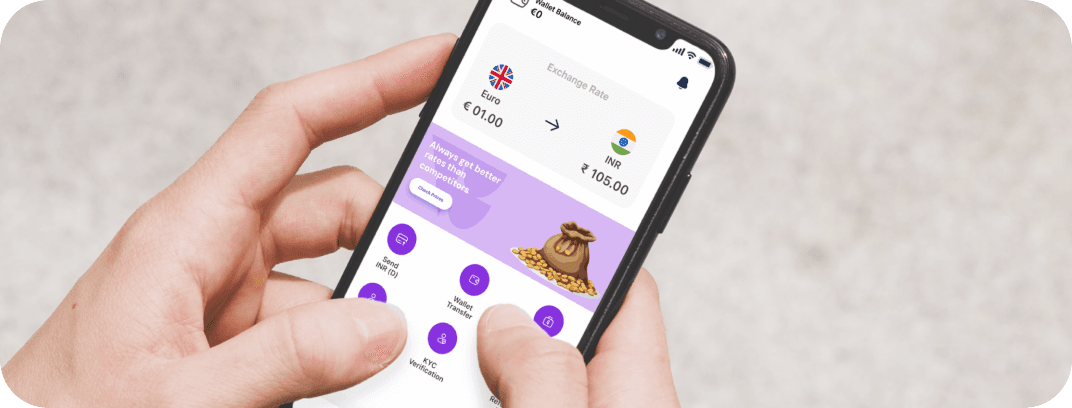
400M+ global payments processed annually
The system provides the scalability required to handle millions of transactions while maintaining data integrity and administrative control.
- Active Users in the UK, Canada, Europe, and Australia
- 120k+
- Global Payments Processed Annually
- 400M+
- Downloads Across iOS and Android
- 350k+
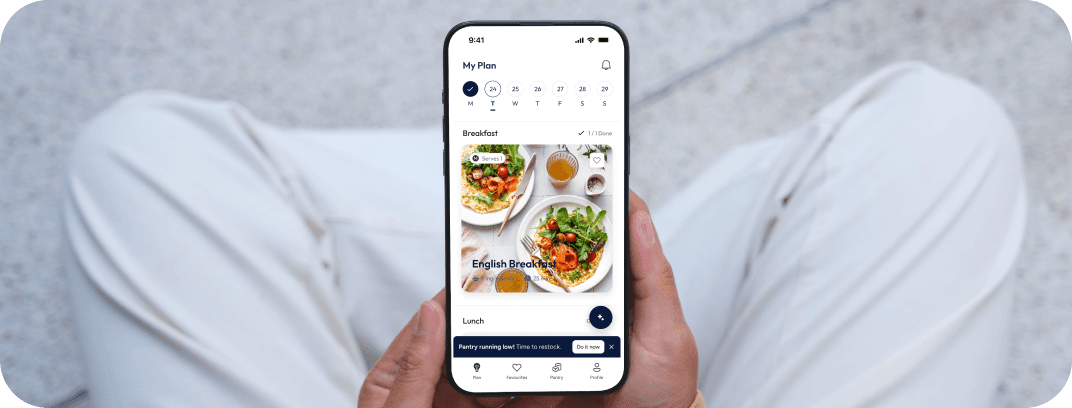
3x faster AI feature iteration
The modular backend architecture allowed the team to deploy new AI capabilities and personalized features significantly faster than industry benchmarks.
- Reduction in meal decision time
- 40%
- Increase in daily active usage during pilot
- 2x
- Faster iteration on new AI-driven features
- 3x
$57,000+ Annual Savings
The project achieved a 60% reduction in monthly cloud costs (from $8,100 to $3,300) without any loss in transaction speed or system security.
- Reduction in monthly cloud costs
- 60%
- Saved per month
- $4800
- Annual savings
- $57,000+
50% reduction in manual validation cycles
The integration of automated benchmarking frameworks and AI-driven process automation also resulted in 30% faster internal testing workflows.
- faster internal testing
- 30%
- reduction in manual validation
- 50%
Our Redis Services for Product Scaling
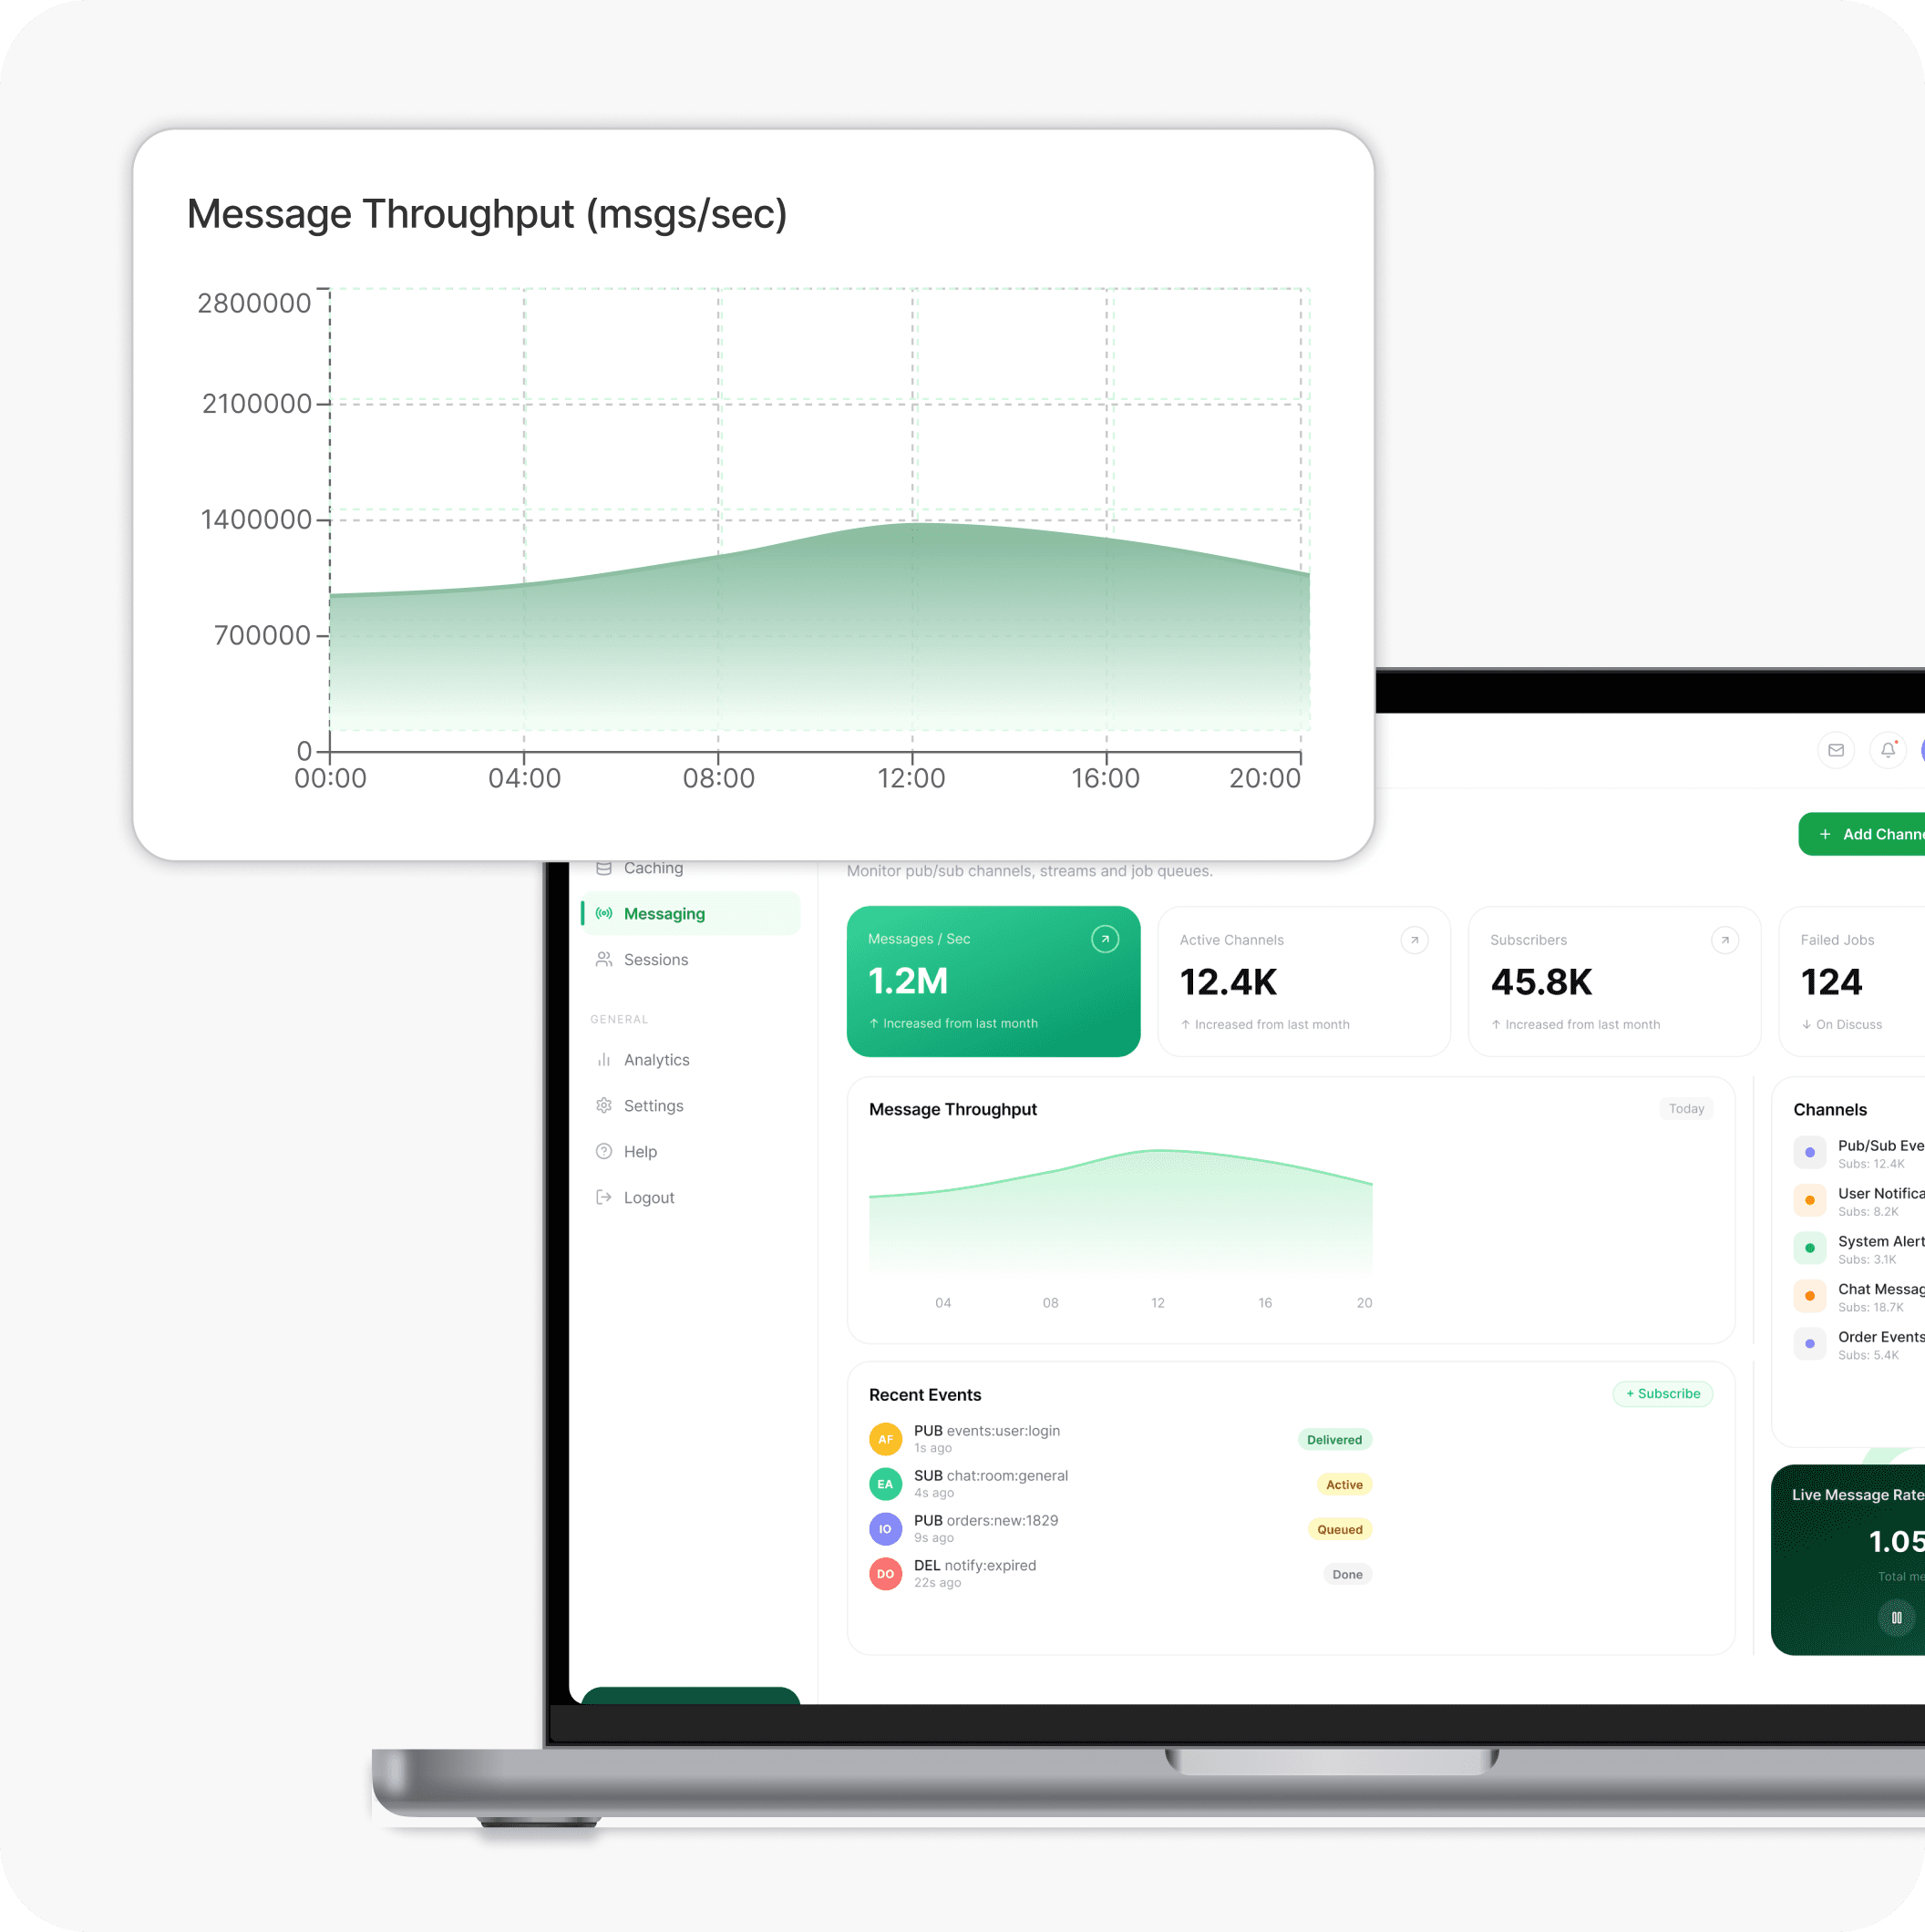
We use write-through and look-aside caching to speed up reads and keep data updated. TTL policies ensure stale data expires based on how frequently the source data changes.
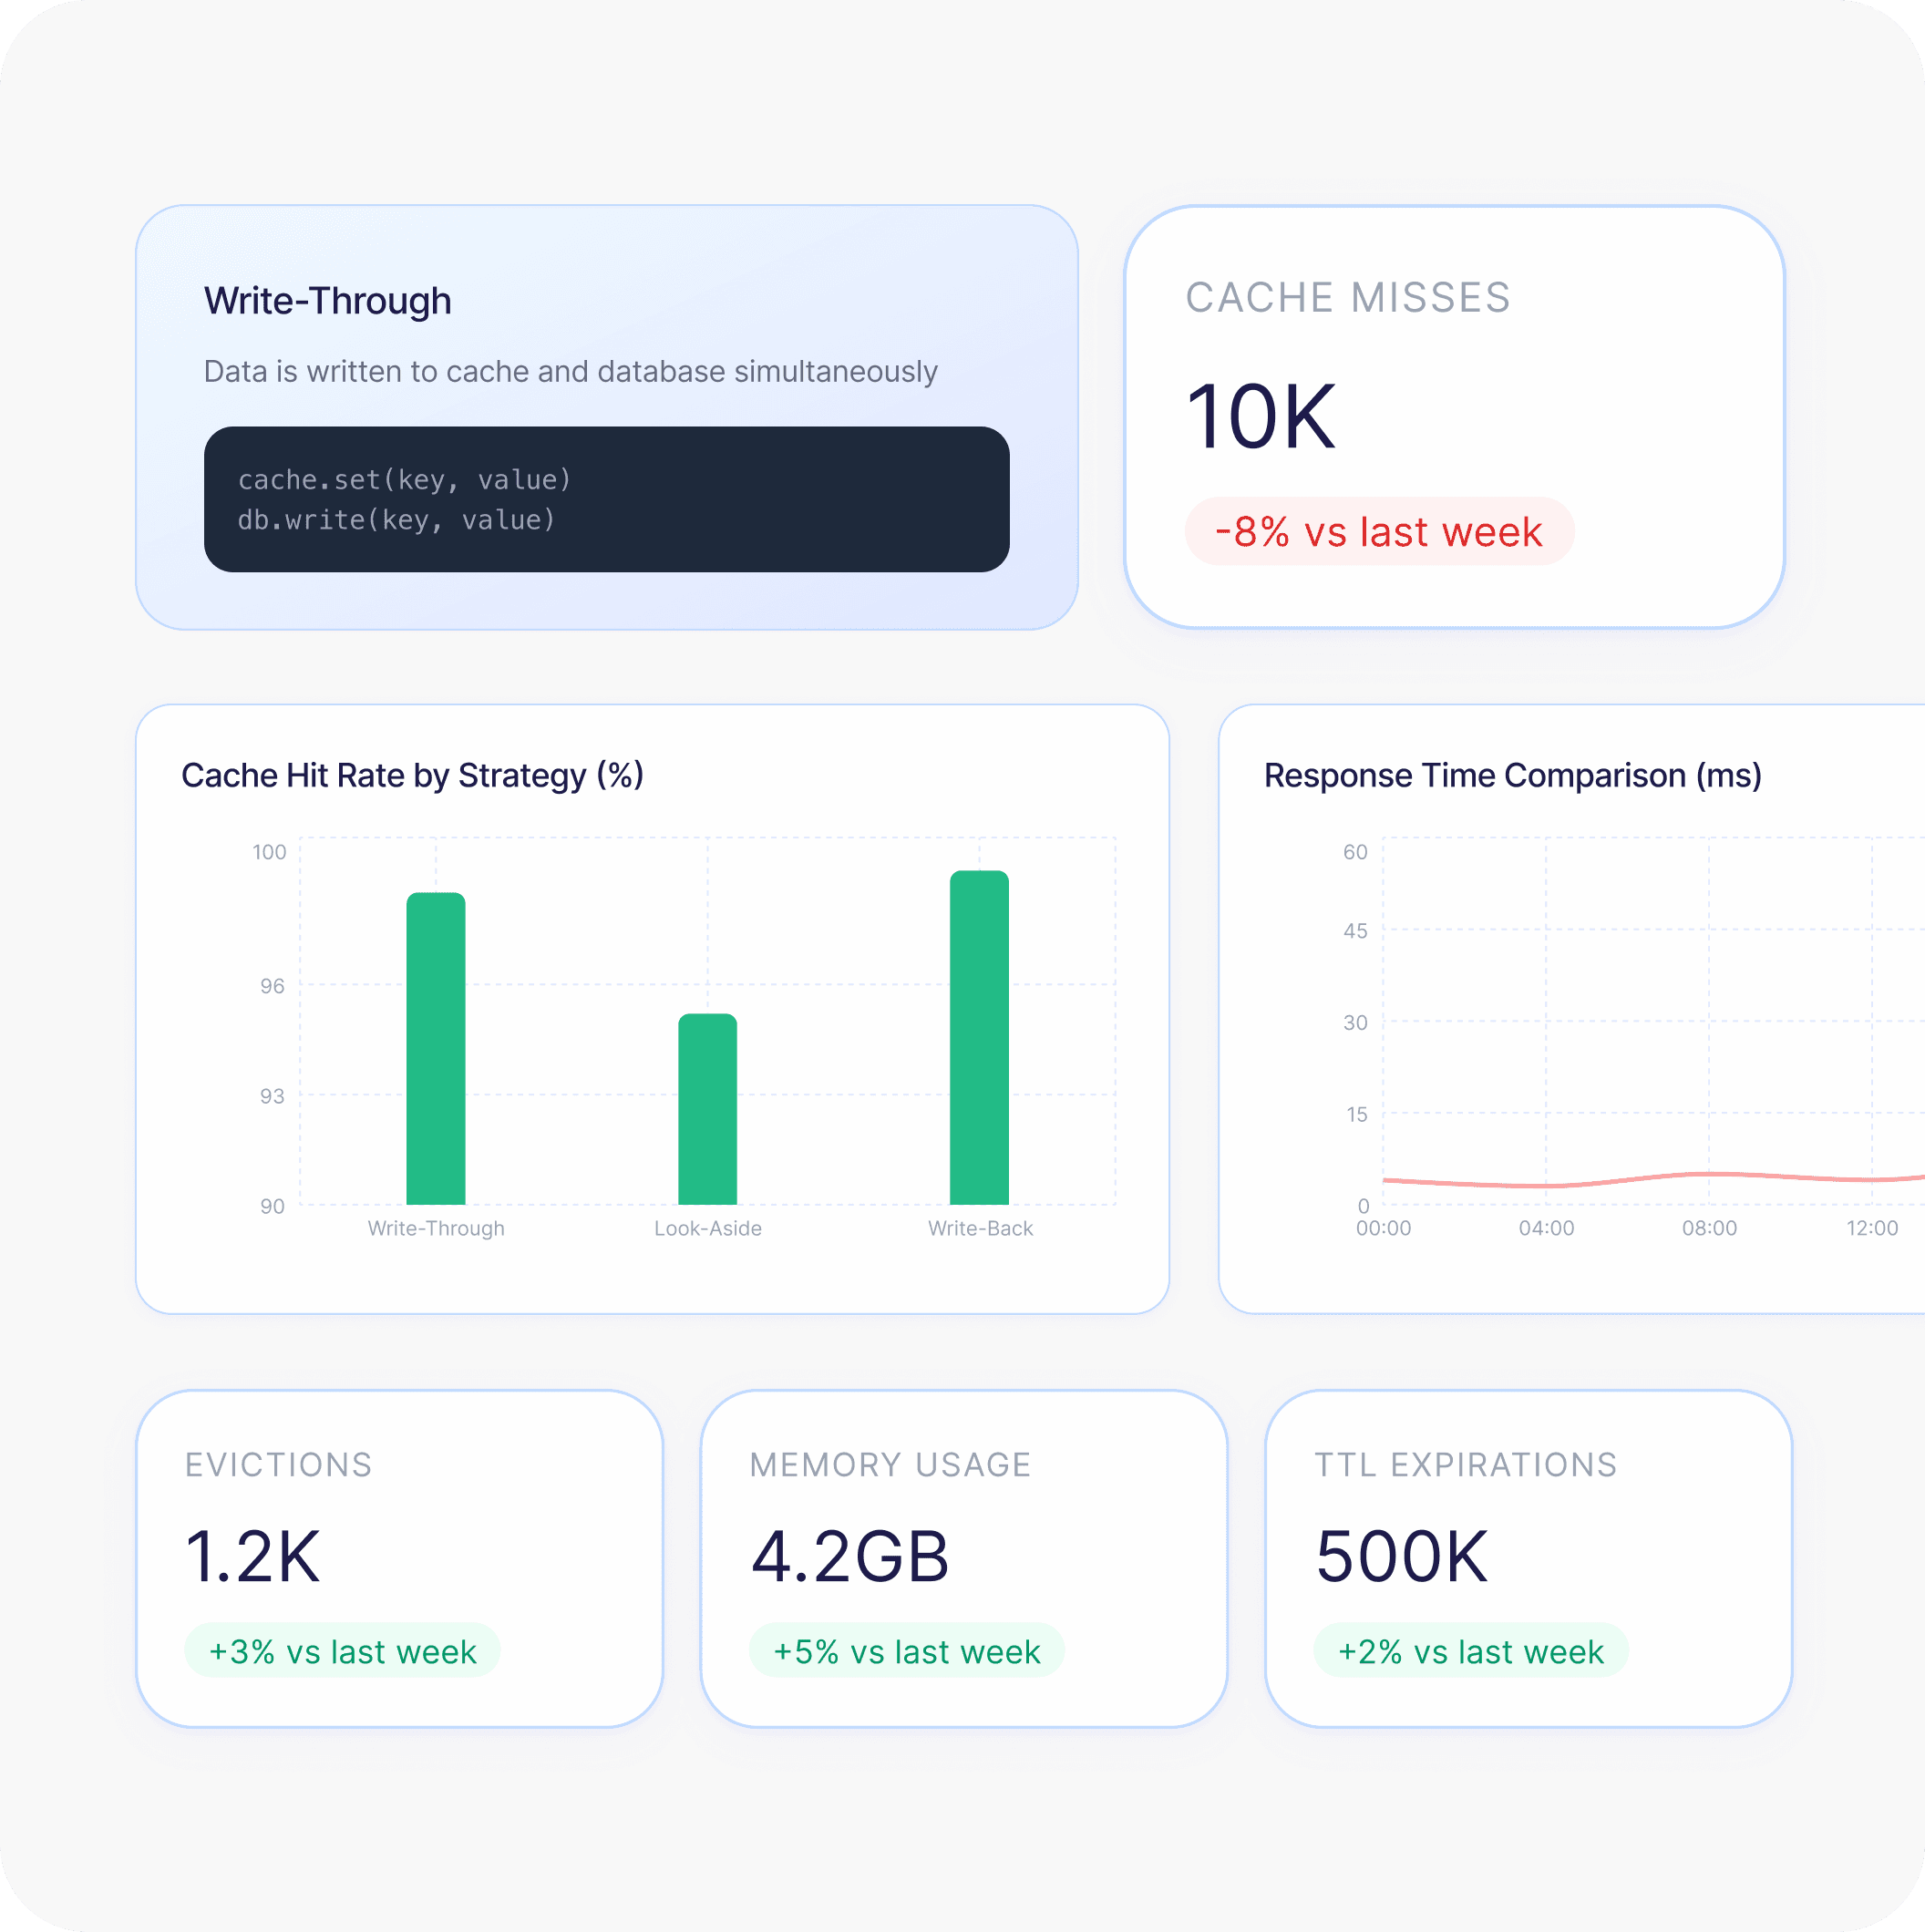
Redis Pub/Sub enables lightweight event broadcasting, while Redis Streams supports event-driven systems that require replay and independent message processing. Job queues handle background tasks efficiently.
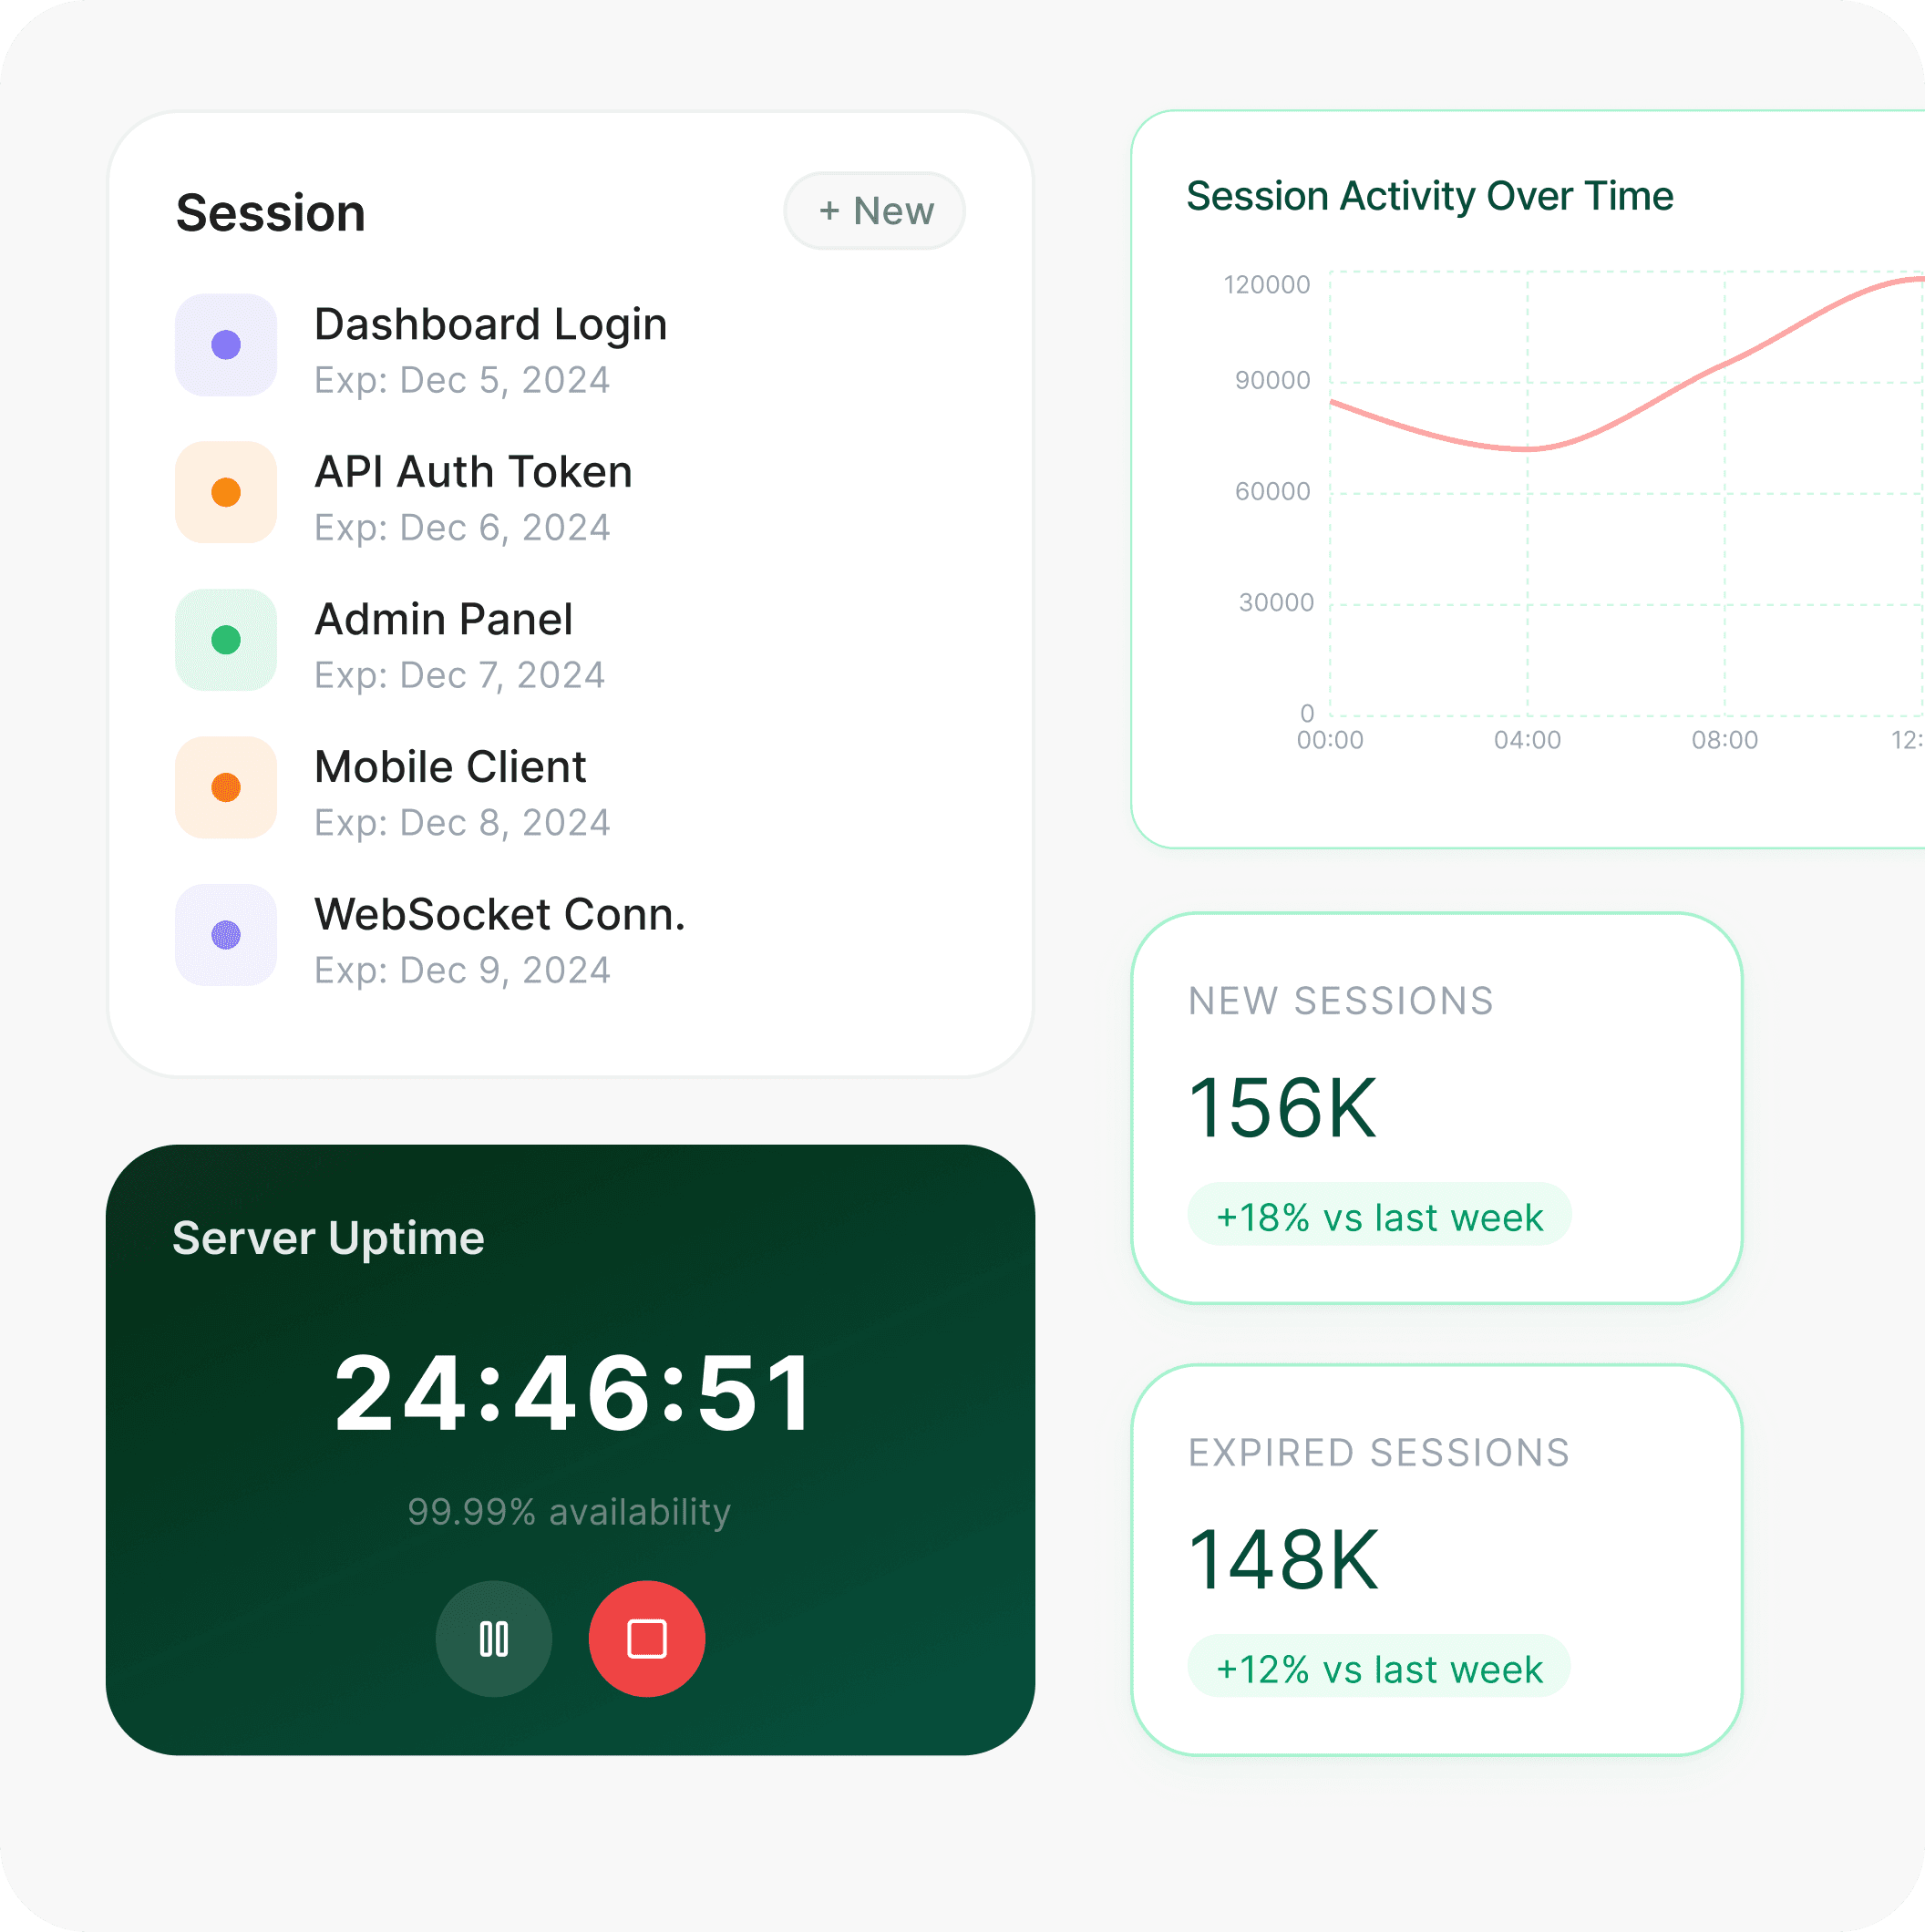
Redis provides centralized session storage with fast access and consistent sessions across distributed servers, preventing session loss during restarts or scaling.
Complete Backend Engineering Services for Enterprises and Companies
Industries-Based Redis Services
Redis solves different problems depending on the product. So, we implement Redis patterns around the specific performance and consistency problem the client has.
Redis for Product Scaling by Engineers Who Have Delivered 1000+ Projects
Fast code is easy to write, but maintainable code is an art. We have fixed systems where the entire app was one giant, confusing file. We know how to untangle these messes and build systems that stay organized for years.
The senior engineers who plan your architecture are the same ones who write the code.
We work with NestJS, Express, GraphQL, and more. We choose the technology that fits your team, not just what is trendy.
We provide clear documentation and Architecture Decision Records. When we finish, your team will have everything they need to run and grow the system without us.
Our Latest Thinking
FAQs About Redis for Services
Write-through updates the cache on every write — the cache and the database stay in sync, and every read hits the cache. Look-aside checks the cache first and populates it on a miss — the cache only holds data that has been read at least once. Write-through suits workloads where stale reads are not acceptable. Look-aside suits read-heavy workloads where not all data needs to be cached — only the data the application actually requests ends up in memory.
Pub/Sub delivers messages to active subscribers only — if a consumer is offline when a message is published, the message is lost. Streams persist messages and allow consumers to read from any point in the stream, including replaying past messages. Pub/Sub works for real-time broadcasts where message loss is acceptable. Streams work for event-driven architectures where every consumer needs to process every message, regardless of when they come online.
A standard inventory check reads the current stock, confirms it is above zero, and decrements it — three operations that are not atomic. Under concurrent load, two requests can both read the same stock value, both confirm it is above zero, and both decrement — producing an oversell. Redis DECR is a single atomic operation — the read and decrement happen in one step with no gap for a concurrent request to intervene. Every decrement either succeeds or fails based on the current value, with no race condition possible.
A database session lookup requires a query on every authenticated request — adding database round-trip latency to every page load. Redis session retrieval is an in-memory key lookup that completes in under a millisecond. For applications with high authenticated traffic, the difference in database load is significant — every session lookup that hits Redis instead of the database is one fewer query the database needs to handle.
AOF persistence with a sync policy matched to the session loss tolerance of the application. For most session workloads, everysec sync — writing to disk once per second — balances write performance with a maximum one-second data loss window on a crash. For workloads where session loss is not acceptable under any failure, synchronous AOF with a replica adds a second layer of durability. The right configuration depends on what losing all active sessions would cost the product.
For workloads that are read-heavy, latency-sensitive, and where the dataset fits in memory — leaderboards, session state, rate limiting counters, feature flags — Redis can serve as the primary data store rather than a cache in front of a database. For workloads that require durability guarantees, complex querying, or datasets that exceed available memory, Redis works best as a performance layer in front of a primary database rather than a replacement for it.
A caching layer implementation — strategy selection, TTL configuration, and cache warming — typically completes within one to two weeks. Adding Pub/Sub or Streams for messaging, Sorted Sets for leaderboards, or atomic counters for inventory management adds one to two weeks per pattern depending on integration complexity. Full session management migration from database to Redis typically completes within two to three weeks.
The implementation is handed over with caching strategy documented, TTL rationale recorded, and operational runbooks covering cache invalidation, memory monitoring, and failover procedures. Your team manages cache configuration changes independently. We do not build on proprietary tooling that requires ongoing GeekyAnts involvement. If a formal support arrangement makes sense post-launch, that is a separate conversation.
