

Scalability and Performance Planning Services
We evaluate your current architecture, traffic patterns, and system behavior under load to show you exactly where bottlenecks are forming, which capacity limits are holding back your growth, and the most effective path to infrastructure that scales with you.
Build Systems That Grow With Your Ambitions, Not Against Them








Most product teams never find their scalability ceiling until a traffic spike, a launch, or a viral moment exposes it in front of their most important users. A Scalability & Performance Assessment examines your architecture, traffic behavior, load characteristics, database performance, and autoscaling to find the constraints that matter before growth makes them harder to fix. It maps your current bottlenecks, capacity limits, and scaling risks, then turns them into a prioritized performance and capacity roadmap your engineers can act on.
Client Results and Success
Production-Ready Kubernetes Architecture
The platform was designed to support scalable production deployments with minimal resource consumption, enabling faster environment provisioning and operational stability.
- environments K8s setup
- 3
- environments K8s setup
- 95%
- savings over managed Kubernetes alternatives
- 35%
40% Faster Onboarding Completion
The redesigned system achieved a 40% reduction in onboarding completion time, directly improving platform adoption and reducing operational bottlenecks.
- Improvement in the doctor's efficiency for treatment planning
- 35%
- Reduction in onboarding completion time
- 40%
Production-Grade AI Infrastructure
The system supports scalable AI inference and automated inspection workflows, reducing manual intervention and enabling consistent performance under growing usage.
Read case study3× Faster Feature Iteration
The platform achieved 3x faster AI feature iteration cycles, significantly reducing time-to-release for new recommendation
- Reduction in meal decision time
- 40%
- Increase in daily active usage during pilot
- 2x
50% Fewer Manual Validation Cycles
The system achieved a 50% reduction in manual validation cycles, improving throughput and accelerating delivery timelines.
- Reduction in manual validation cycles
- 50%
- Faster internal testing workflows
- 50%
60% Cloud Cost Reduction
The platform achieved a 60% reduction in monthly cloud costs while maintaining uptime and transaction stability during and after optimization.
- Saved per month
- $4,800
- Annual savings
- $57,000+
Our Scalability Assessment Examines Three Foundational Dimensions
Our assessment covers three areas: architectural scalability, application performance, and operational readiness for growth. We don’t base recommendations on architecture reviews done in isolation from real behavior. Our engineers go through your actual traffic patterns, load-test results, database query profiles, and production incident history, so the strategy reflects how your system behaves in production rather than how it was meant to on paper.
- Scaling model assessment: Horizontal versus vertical scaling patterns, stateless service design, and shared state bottleneck identification
- Traffic distribution analysis: Load balancer configuration, geographic distribution, and request routing efficiency
- Database scalability evaluation: Read replica utilisation, sharding strategies, connection pool sizing, and query plan analysis
- Dependency scaling constraints: Third-party API rate limits, internal service coupling, and downstream bottleneck identification
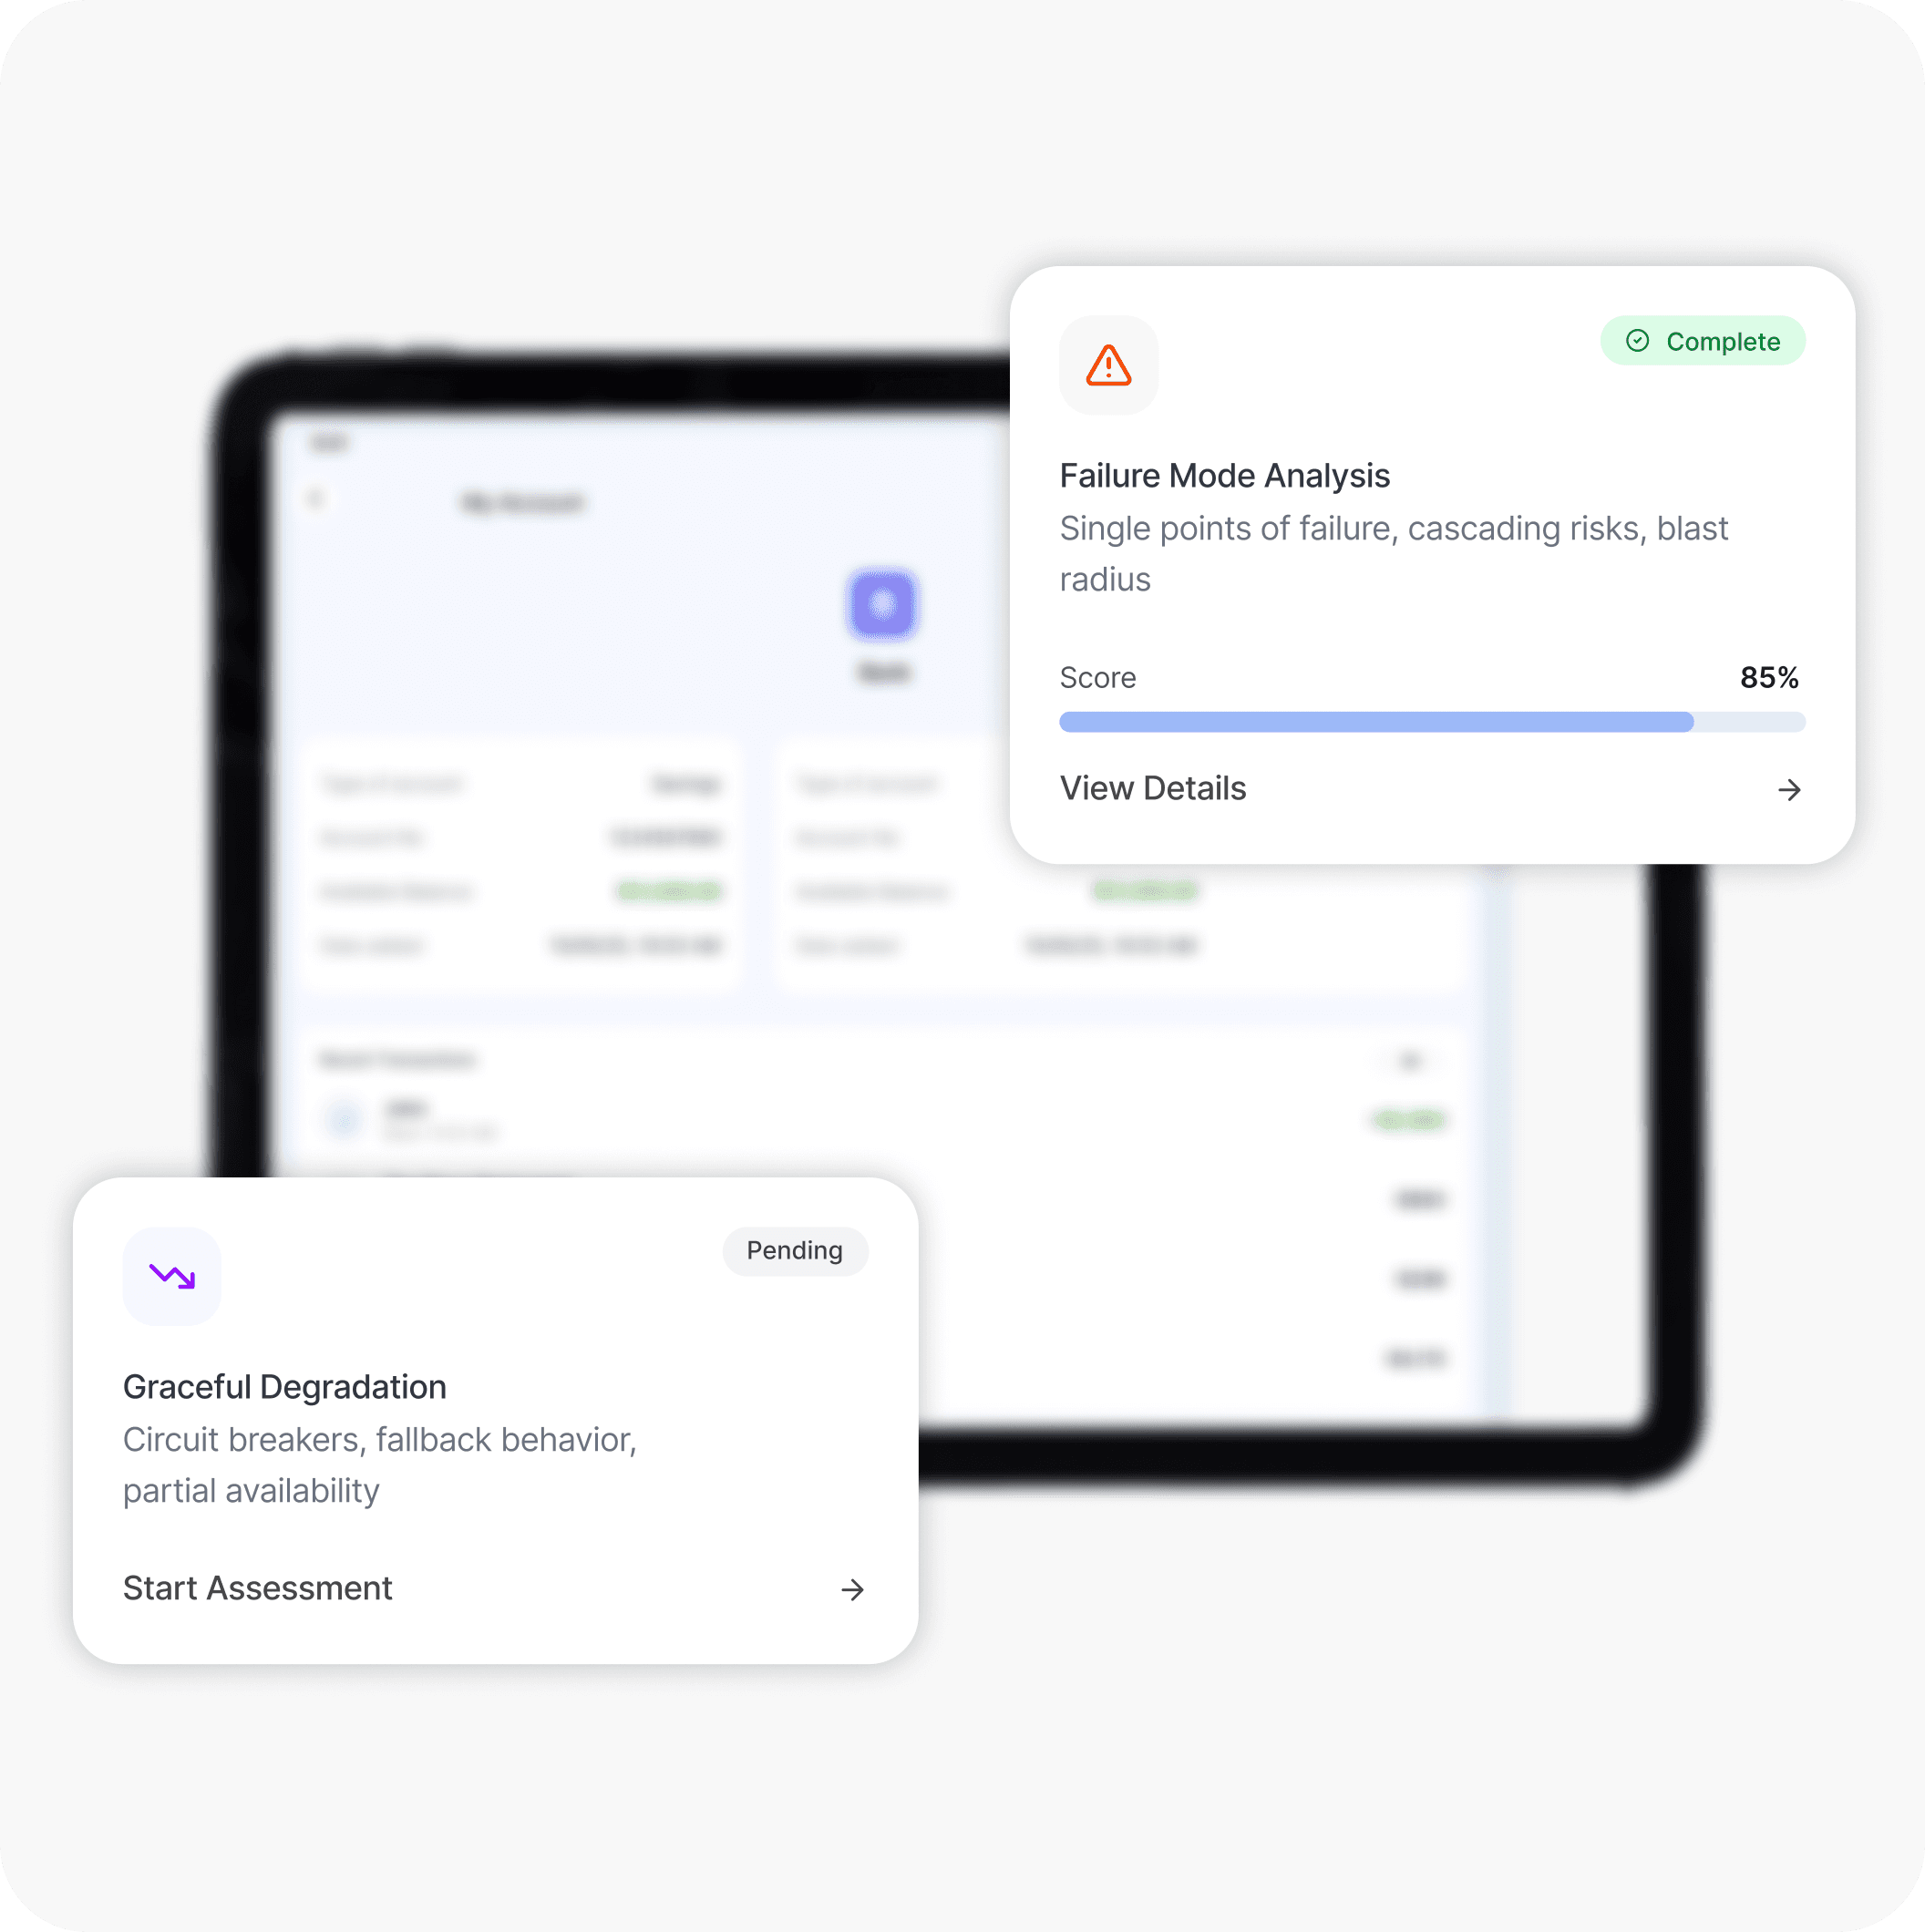
- Latency profiling: Request lifecycle tracing, slow endpoint identification, and percentile-level response time characterization
- Throughput capacity modelling: Current sustainable request rates, degradation onset thresholds, and headroom quantification
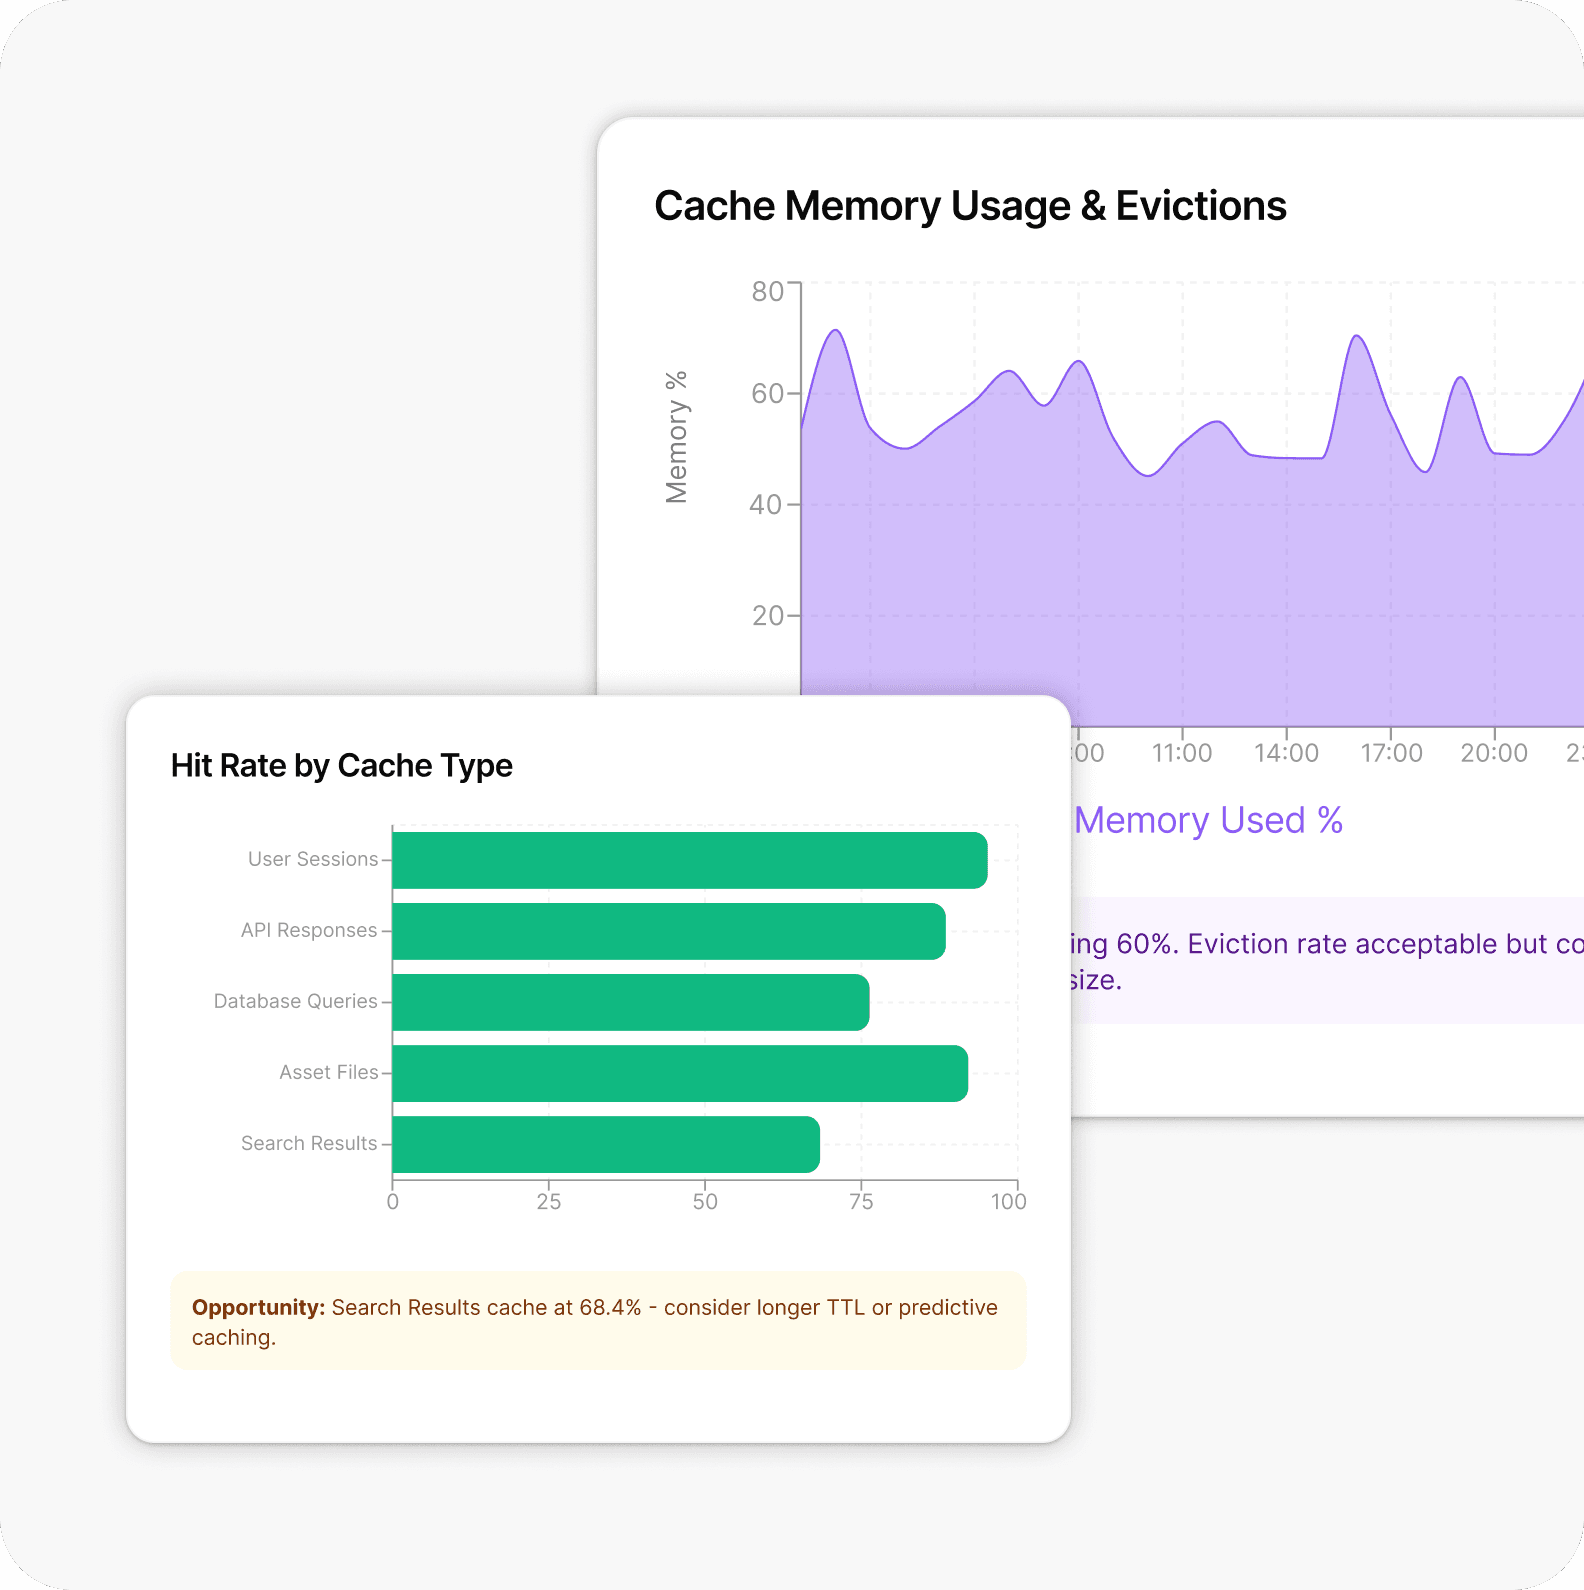
- Caching strategy review: Cache hit rates, cache invalidation patterns, and opportunities to reduce upstream database pressure
- Memory and CPU utilization patterns: Resource consumption trends, garbage collection behaviour, and compute efficiency under varying load profiles
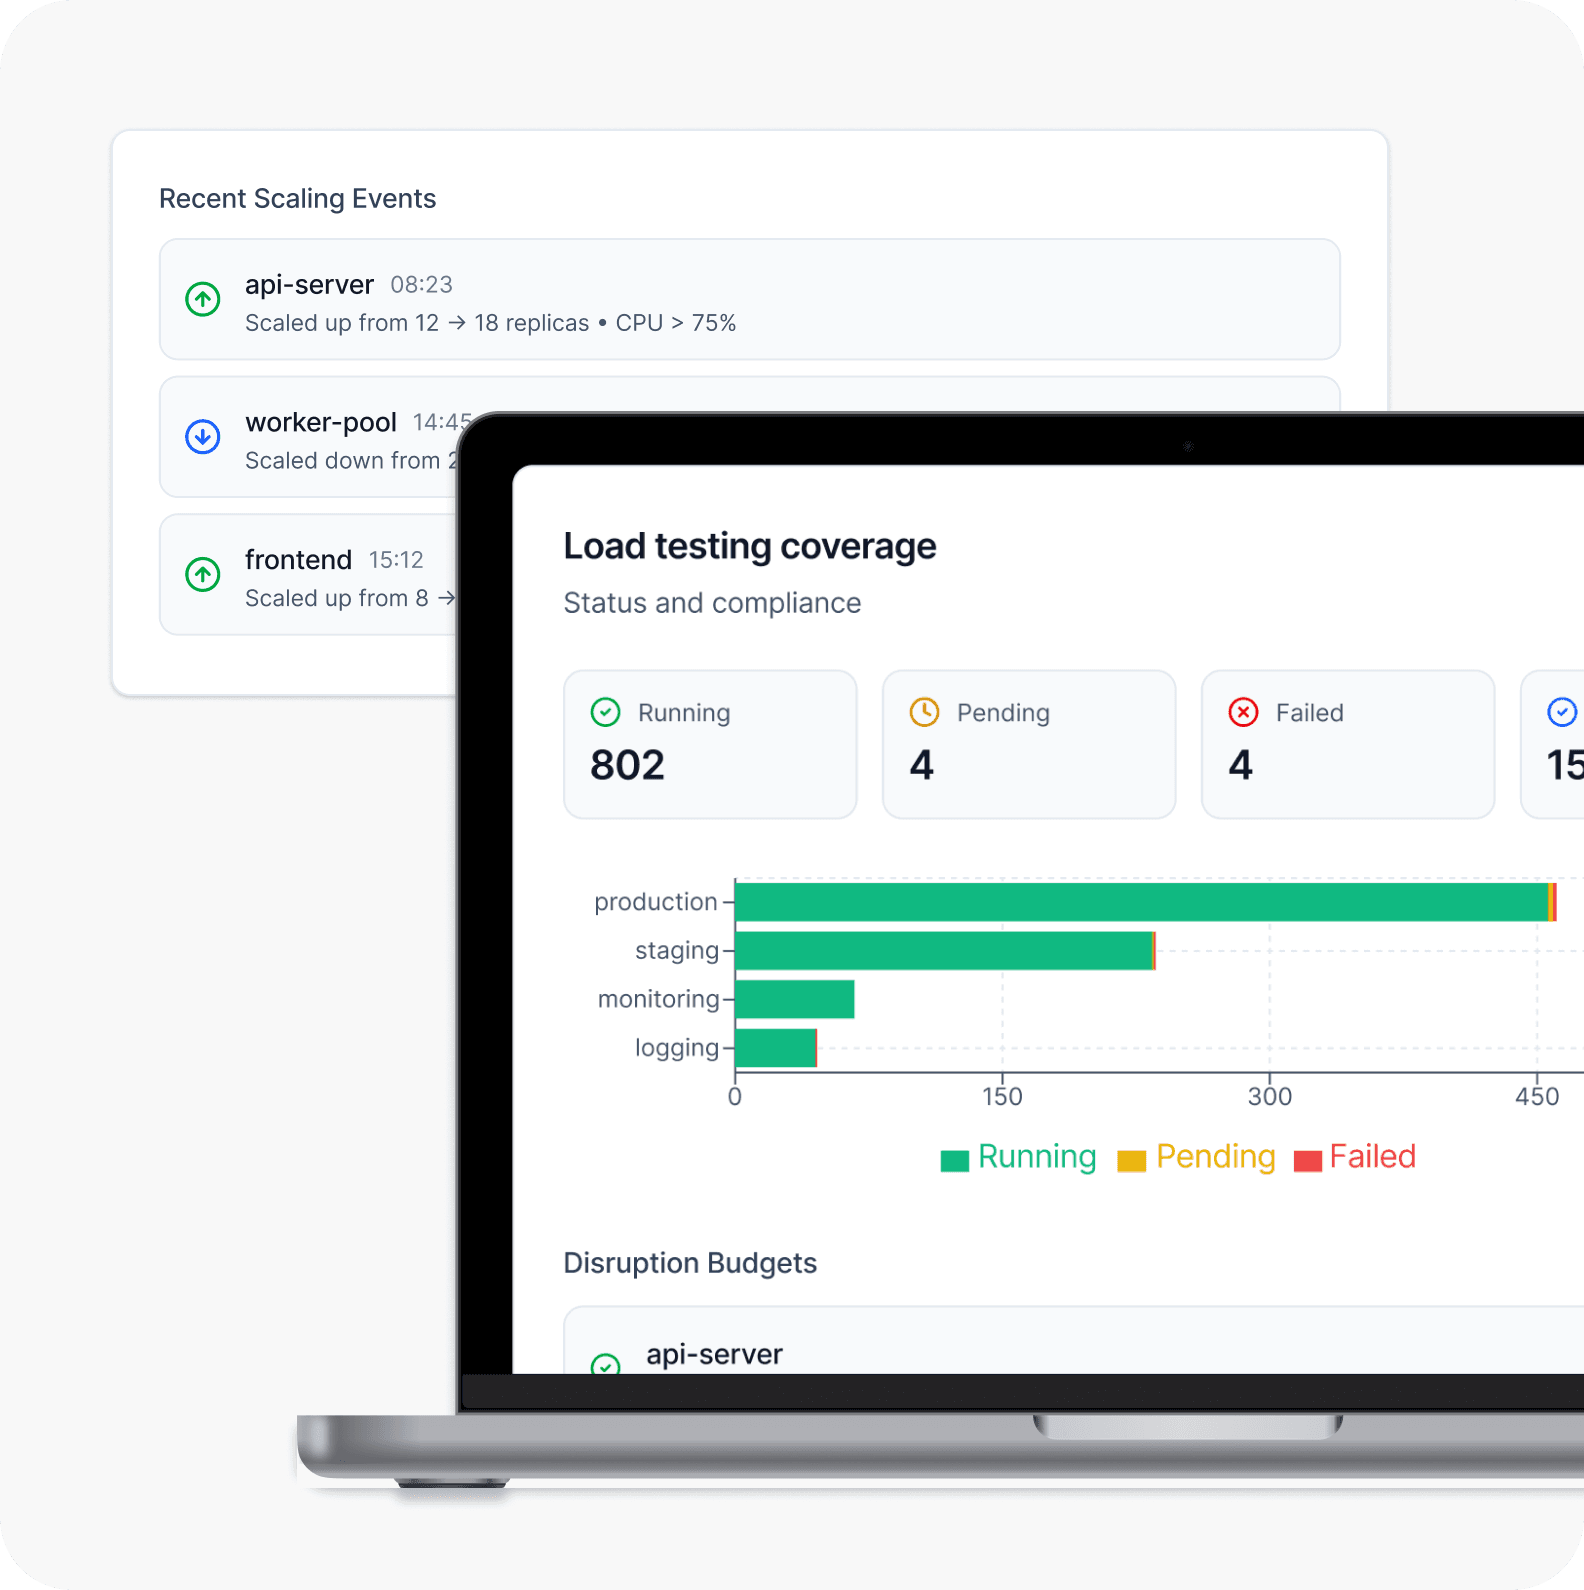
- Autoscaling configuration audit: Scaling trigger thresholds, cooldown periods, and scale-in behavior under declining load
- Load testing coverage assessment: Existing test scenario completeness, realistic traffic simulation, and performance regression detection capability
- Capacity planning process maturity: Forecasting methodology, growth modeling, and infrastructure procurement lead time alignment
- Incident response for performance events: Runbook availability, escalation paths, and mean time to recovery for degradation scenarios
Recurring Patterns We See Across Scalability Engagements
Based on findings across our scalability and performance assessments.
3-5x
localized bottlenecks found at the database layer (locks, connection pools)
70%
of performance incidents trace to P99 latency spikes, not average load
1 in 4
autoscaling policies we test fail to trigger correctly under real load
40%
of provisioned capacity sitting idle outside peak, raising cost without adding headroom
Outcomes Performance Planning Can Support
Our performance planning services pin down scalability constraints, capacity limits, latency risks, and operational gaps, then organize them into a prioritized roadmap. The findings help your team decide where to invest, whether that’s architecture, caching, database performance, autoscaling, load testing, or infrastructure capacity, as usage grows.
Eliminate the Fear That Comes With Every Traffic Spike
Understand precisely where your system begins to degrade under load and what specific changes eliminate those boundaries — so your team watches growth metrics with anticipation rather than anxiety.
Scale Your Product Without Scaling Your Operational Complexity
Remove the architectural constraints that force manual intervention every time usage increases, so your infrastructure grows alongside your user base without demanding proportional engineering attention.
Deliver Consistent Performance Regardless of Concurrent Demand
Arrive at an architecture where response times, throughput, and reliability metrics remain predictable whether you are serving your average daily load or your highest traffic peak on record.
Invest in Capacity Where It Generates Return, Not Where It Feels Safe
Receive a precise breakdown of where infrastructure investment delivers measurable performance improvement and where additional spend yields diminishing returns, so every capacity decision is evidence-based.
Industries Across Which We Deliver Scalability and Performance Impact
We design scalability strategies calibrated to the growth trajectories, traffic characteristics, and reliability expectations of each industry we operate within. Our approach consistently prioritises long-term architectural sustainability over short-term performance patches. We understand the seasonal demand patterns, regulatory availability requirements, and competitive performance expectations that shape infrastructure decisions across every vertical we serve. Every industry in our portfolio reflects genuine, hands-on scalability engineering experience rather than advisory familiarity.
Scalability Assessments Backed by 1000+ Delivered Projects
Our performance specialists work from real evidence: your traffic behavior, architecture, database constraints, load-test results, autoscaling configuration, and production history, not a fixed scalability checklist. Every recommendation is tied to your actual workload, growth expectations, reliability requirements, and technology stack.
Our AI-enabled engineers and performance specialists have led scalability transformations across high-traffic, availability-critical platforms in regulated and consumer-facing environments alike.
Every bottleneck, every capacity constraint, and every scaling risk is quantified against your actual traffic patterns and growth projections — not estimated from architectural diagrams alone.
We recommend the scaling patterns, caching strategies, and architectural changes that your specific workload characteristics demand — never the ones that align with a preferred vendor or platform relationship.
Every recommendation we produce is specific, testable, and directly assignable to an engineering team — no translation layer required between assessment output and implementation action.
We document every finding, every architectural decision rationale, and every performance model assumption so your team owns the scalability strategy long after our involvement concludes.
Our Offerings in DevOps Consulting and Services
Our Latest Thinking
FAQs About Scalability & Performance Planning Assessment Services
A Scalability & Performance Assessment is a thorough technical investigation of your current architecture, application behaviour under load, database performance characteristics, and operational readiness to manage growth. It identifies every bottleneck constraining your current capacity, maps the failure modes your system will encounter as usage grows, and surfaces the architectural changes, caching strategies, and scaling configurations that will deliver the most meaningful performance improvement per unit of engineering investment. You receive a complete performance profile of your existing system alongside a phased improvement roadmap sequenced by impact and implementation complexity.
Most assessments conclude within 2 to 4 weeks, depending on the breadth of your technology stack, the number of services requiring profiling, and the availability of existing load test results and production performance data. Organizations running complex microservice architectures, multi-region deployments, or high-volume data processing pipelines may require additional time to ensure every critical performance boundary is examined thoroughly. We define the engagement timeline explicitly during the initial scoping session so expectations are aligned before work begins.
We work within whatever access boundaries your security policies permit. Read-only access to your infrastructure configuration, application performance monitoring dashboards, database query profiles, and cloud console metrics is generally sufficient for a comprehensive assessment. Where production access is restricted, we design the engagement methodology around the access level available and are transparent about any resulting coverage limitations. We have conducted performance assessments within highly regulated environments, including financial services and healthcare platforms, and are experienced in working under strict access constraints without compromising assessment quality.
Not at all — and in many cases, existing monitoring data makes the assessment more valuable because it gives our engineers direct access to real production behaviour rather than synthetic approximations. However, having monitoring in place and interpreting what it reveals are two different things. A significant proportion of the teams we work with have comprehensive observability tooling deployed, but lack the architectural context to translate what the data is telling them into prioritized, actionable improvements. Our assessment bridges that gap by combining what your monitoring reveals with deep architectural analysis to produce recommendations that are both evidence-based and practically executable.
These terms are frequently used interchangeably but describe meaningfully distinct challenges. A performance problem manifests as slow response times or high resource consumption under your current load — the system is inefficient at the scale it already operates. A scalability problem manifests when the system degrades non-linearly as load increases — it performs acceptably today, but will fail in predictable ways as your user base or transaction volumes grow. Most systems we assess exhibit both simultaneously, with performance inefficiencies compounding the severity of scalability constraints. Our assessment examines both dimensions and distinguishes clearly between what needs fixing now and what needs designing differently for the future.
Where existing load testing infrastructure is unavailable or immature, our assessment focuses on architectural analysis, production traffic pattern examination, and capacity modelling based on your actual usage data and growth projections. We identify the theoretical scaling boundaries imposed by your current architecture and validate those boundaries against real production behaviour where data is available. We also assess your load testing capability itself as part of the engagement and provide specific recommendations for building the testing infrastructure needed to validate performance improvements as they are implemented. An assessment does not require existing load testing maturity — it frequently helps organizations build it.
You receive a comprehensive performance characterization report documenting your system's current throughput limits, latency profiles, and degradation thresholds across key user journeys. This is accompanied by a bottleneck inventory mapping every identified constraint to its architectural root cause and estimated performance impact. The roadmap we provide sequences improvements across 30, 60, and 90-day execution windows based on the combination of implementation effort and expected performance gain. We also deliver a capacity planning model giving your team a quantitative framework for forecasting infrastructure requirements against projected growth scenarios, and we conclude with a live readout session walking your engineering and product leadership through every finding in detail.
Database performance receives dedicated and extensive attention within every scalability assessment we conduct, because in our experience, it is the most common and most consequential bottleneck in production systems. We examine query execution plans, index coverage, connection pool configuration, read replica utilisation, locking contention patterns, and the appropriateness of your database technology choices relative to your access patterns and data volumes. Where applicable, we evaluate caching layer effectiveness, identify queries generating disproportionate database load, and assess whether your current database architecture will sustain your projected growth trajectory or requires structural changes before the next scale threshold.
Explicitly and consistently. Every recommendation we make is evaluated against three dimensions simultaneously: the performance improvement it delivers, the implementation complexity it introduces, and the infrastructure cost impact it carries. We specifically identify and flag cases where naive performance improvements — such as aggressive over-provisioning or redundant caching layers — would increase costs without delivering proportional reliability or throughput benefits. The goal is a performance architecture that is efficient as well as capable, and our recommendations always reflect that balance rather than optimizing for raw performance metrics in isolation.
We are technology-agnostic and have delivered scalability assessments across a wide range of application frameworks, database technologies, and cloud platforms. On the infrastructure side, we work across AWS, Google Cloud Platform, and Microsoft Azure. On the application layer, our engineers have profiled performance across Node.js, Python, Java, Go, Ruby, and .NET environments, among others. Database experience spans relational systems including PostgreSQL and MySQL, NoSQL platforms including MongoDB, DynamoDB, and Cassandra, and caching layers including Redis and Memcached. Our recommendations are always driven by your workload characteristics and growth requirements — never by platform preferences.
This is one of the most consequential questions our assessment answers — and it is one that teams frequently struggle to answer objectively when they are close to the systems they have built. Our evaluation distinguishes between performance problems that are resolvable through configuration changes and targeted optimizations, and structural scalability constraints that require meaningful architectural intervention to address. Where redesign is warranted, we scope it precisely, sequence it pragmatically, and present the risk and cost of deferral alongside the investment required to act. You leave the engagement with a clear, evidence-based answer rather than an opinion shaped by familiarity or sunk cost.
The assessment is intentionally designed as a self-contained, fully executable deliverable that your engineering team can act on independently. Every recommendation is documented with sufficient technical specificity that implementation does not require our ongoing involvement to interpret or expand upon. For organizations that prefer external support during implementation, we offer targeted engineering engagement to assist with specific architectural changes, load testing programme development, or performance validation following improvements. Whether you execute independently or bring us in to support delivery, the assessment roadmap functions as the authoritative reference throughout — because we document every decision rationale, assumption, and trade-off made during the engagement.
