

Deployment and Infrastructure Automation
Unreliable releases and inconsistent environments slow your team down, eroding trust in every push to production.
We automate your deployment pipelines and infrastructure operations end-to-end, so shipping becomes the least stressful part of your engineering process.
Go from Manual Release to Automated Infra








Deployment problems rarely announce themselves all at once. They accumulate over time: a manual step here, an undocumented config there, a staging environment that quietly diverged from production months ago. By the time the cost becomes visible, it's usually through a delayed release or an outage that could have been prevented.
Our Deployment and Infrastructure Automation service is built to reverse that pattern. We start by mapping where your release and provisioning workflows are actually breaking down, then rebuild them into automated, auditable systems that your team can rely on
Client Results and Success
Production-Ready Kubernetes Architecture
The platform was designed to support scalable production deployments with minimal resource consumption, enabling faster environment provisioning and operational stability.
- environments K8s setup
- 3
- environments K8s setup
- 95%
- savings over managed Kubernetes alternatives
- 35%
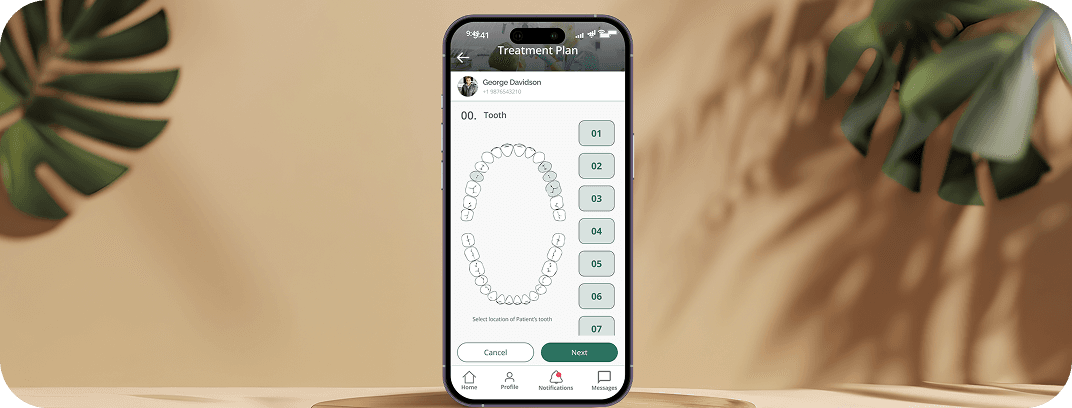
40% Faster Onboarding Completion
The redesigned system achieved a 40% reduction in onboarding completion time, directly improving platform adoption and reducing operational bottlenecks.
- Improvement in the doctor's efficiency for treatment planning
- 35%
- Reduction in onboarding completion time
- 40%
Production-Grade AI Infrastructure
The system supports scalable AI inference and automated inspection workflows, reducing manual intervention and enabling consistent performance under growing usage.
Read case study3× Faster Feature Iteration
The platform achieved 3x faster AI feature iteration cycles, significantly reducing time-to-release for new recommendation
- Reduction in meal decision time
- 40%
- Increase in daily active usage during pilot
- 2x
50% Fewer Manual Validation Cycles
The system achieved a 50% reduction in manual validation cycles, improving throughput and accelerating delivery timelines.
- Reduction in manual validation cycles
- 50%
- Faster internal testing workflows
- 30%
60% Cloud Cost Reduction
The platform achieved a 60% reduction in monthly cloud costs while maintaining uptime and transaction stability during and after optimization.
- Saved per month
- $4,800
- Annual savings
- $57,000+
Our Deployment and Infrastructure Automation Services
We ensure deployment friction does not slow down any project, individual, or clusters. Our services are designed to remove the tax every engineer faces every single day from manual steps and broken handoffs. We strengthen your configurations with automated systems that make shipping fast, predictable, and boring in the best possible way.
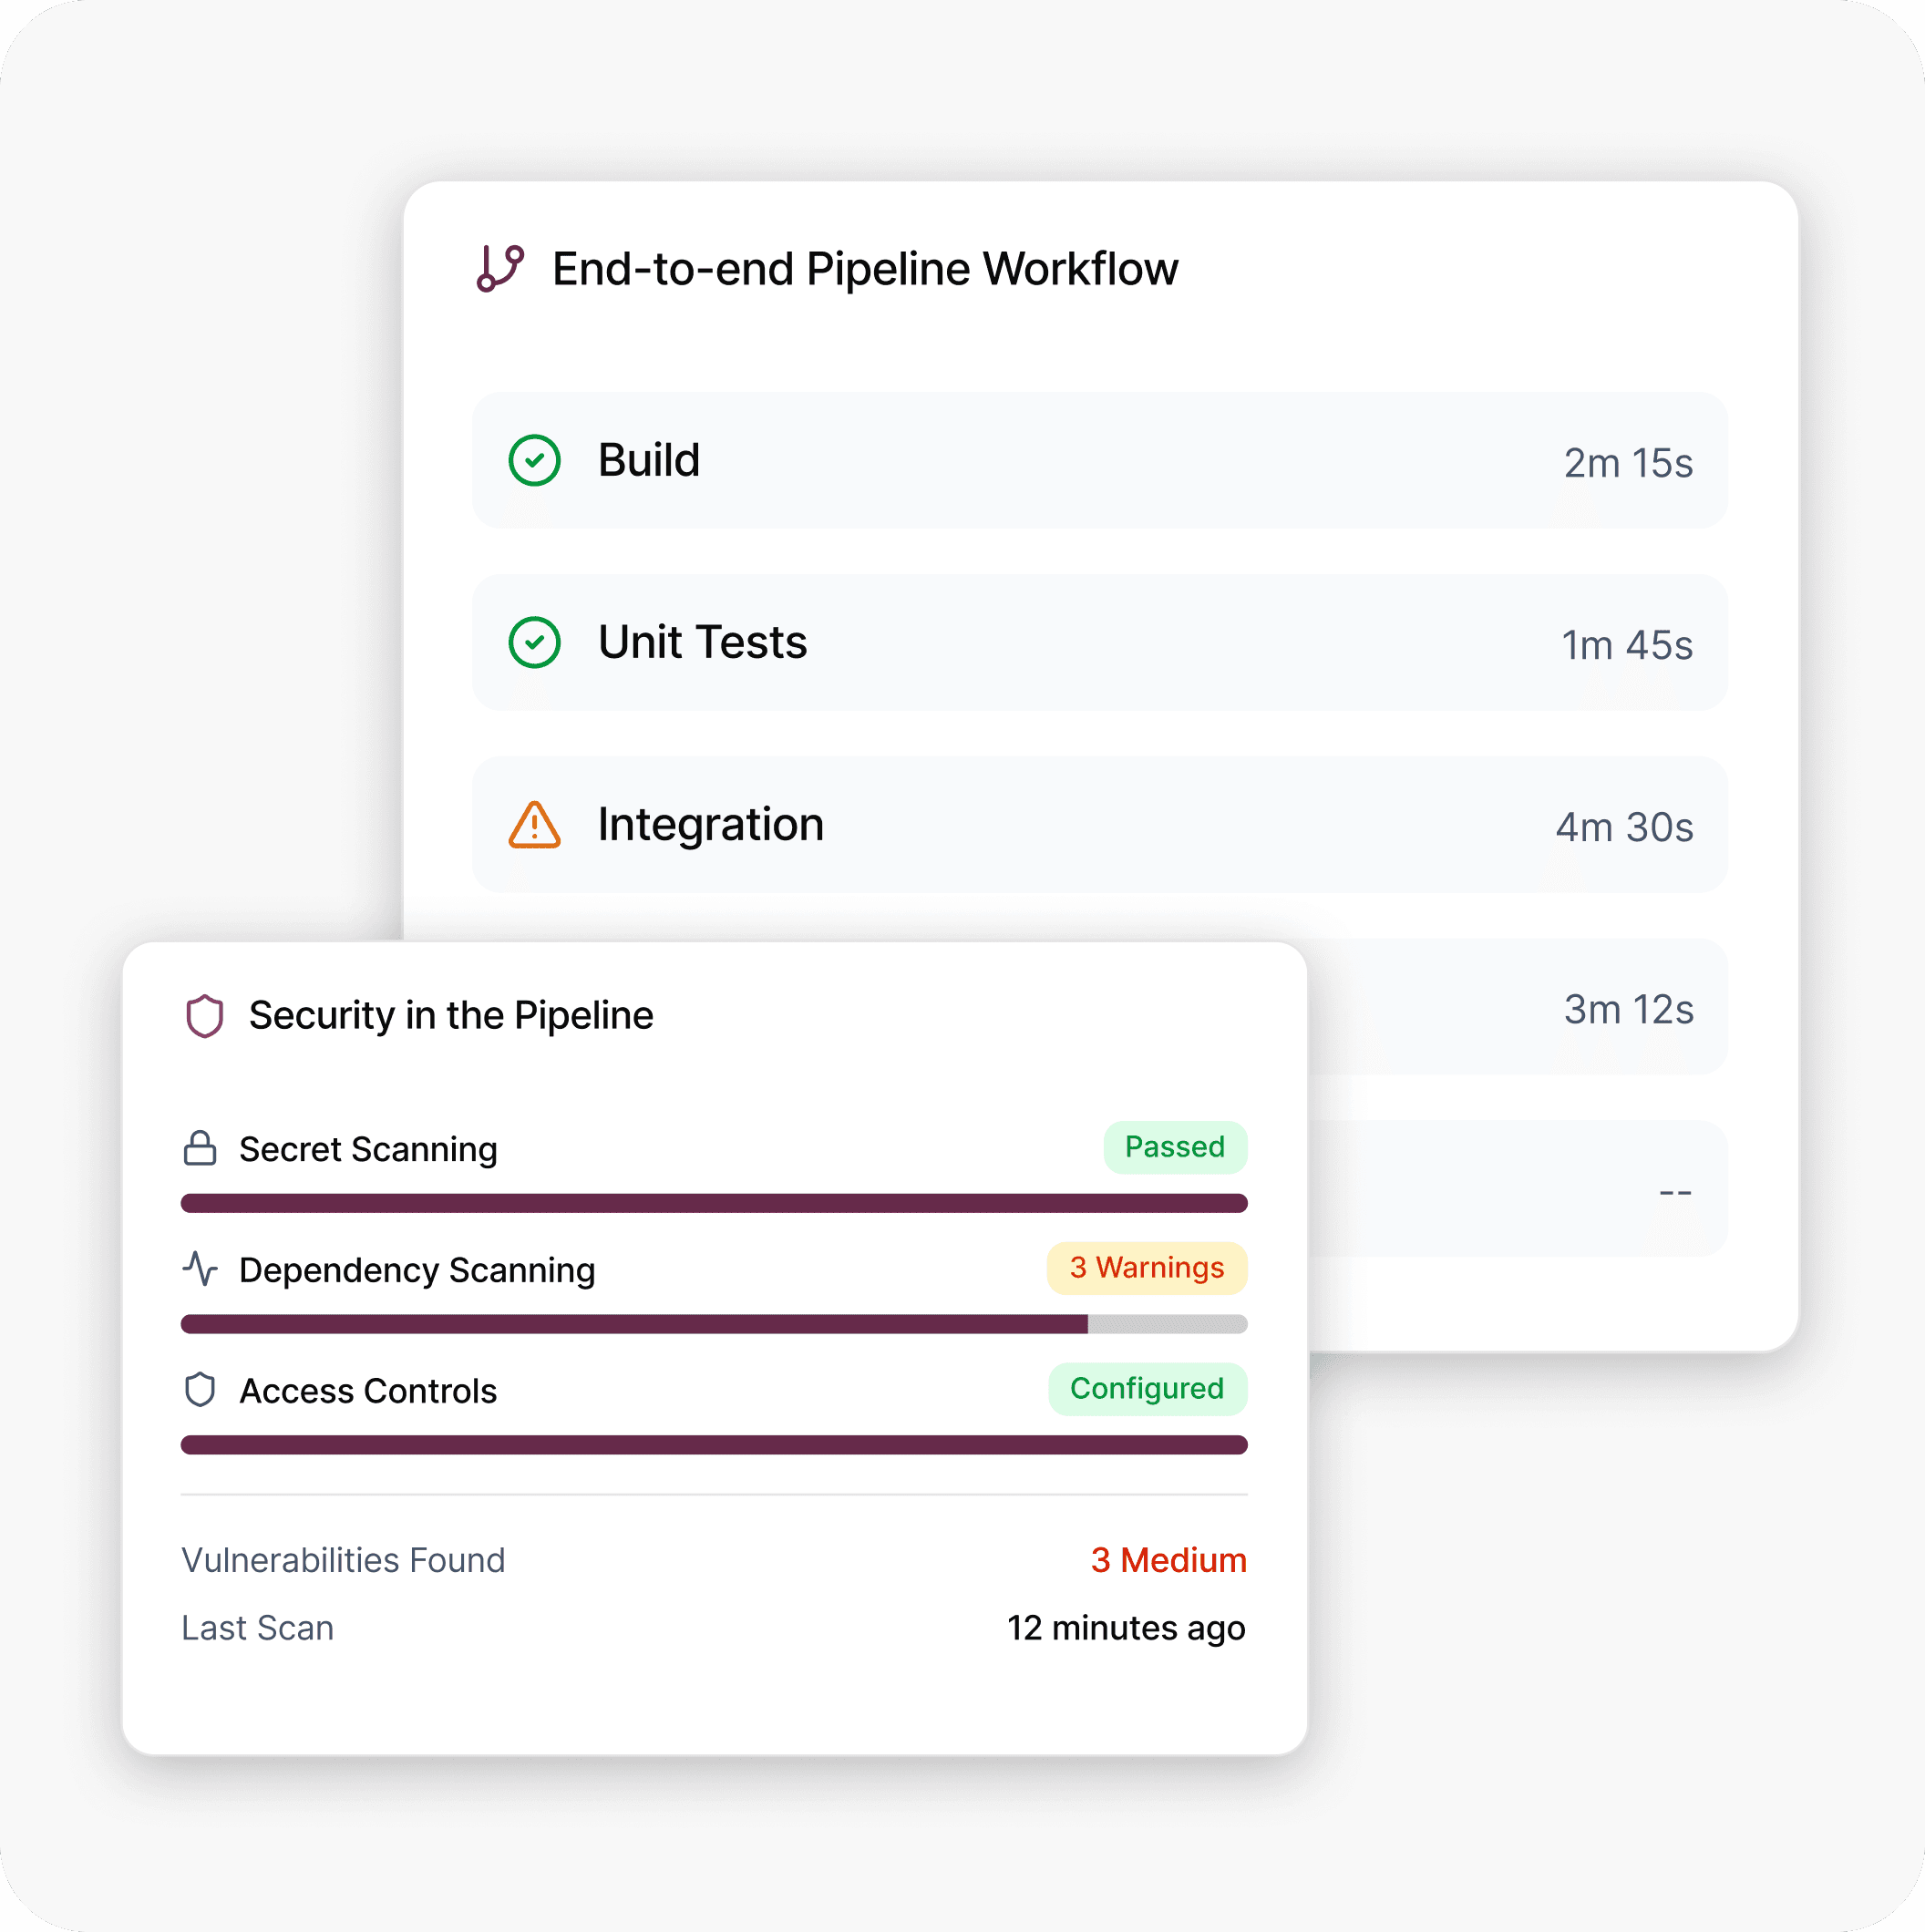
- End-to-end pipeline architecture covering your full build, test, and release sequence.
- Deployment strategy design across blue/green, canary, rolling, and feature-flagged patterns.
- Automated environment promotion gates from development through to production.
- Pipeline reliability hardening, including retry logic, flaky test isolation, and failure alerting.
- Kubernetes cluster design and day-two operations for production-grade workloads.
- Helm chart management for standardised, reusable release packaging.
- Ingress, internal routing, and traffic management configuration.
- Auto-scaling aligned to real workload demand using HPA, VPA, and cluster autoscaling.
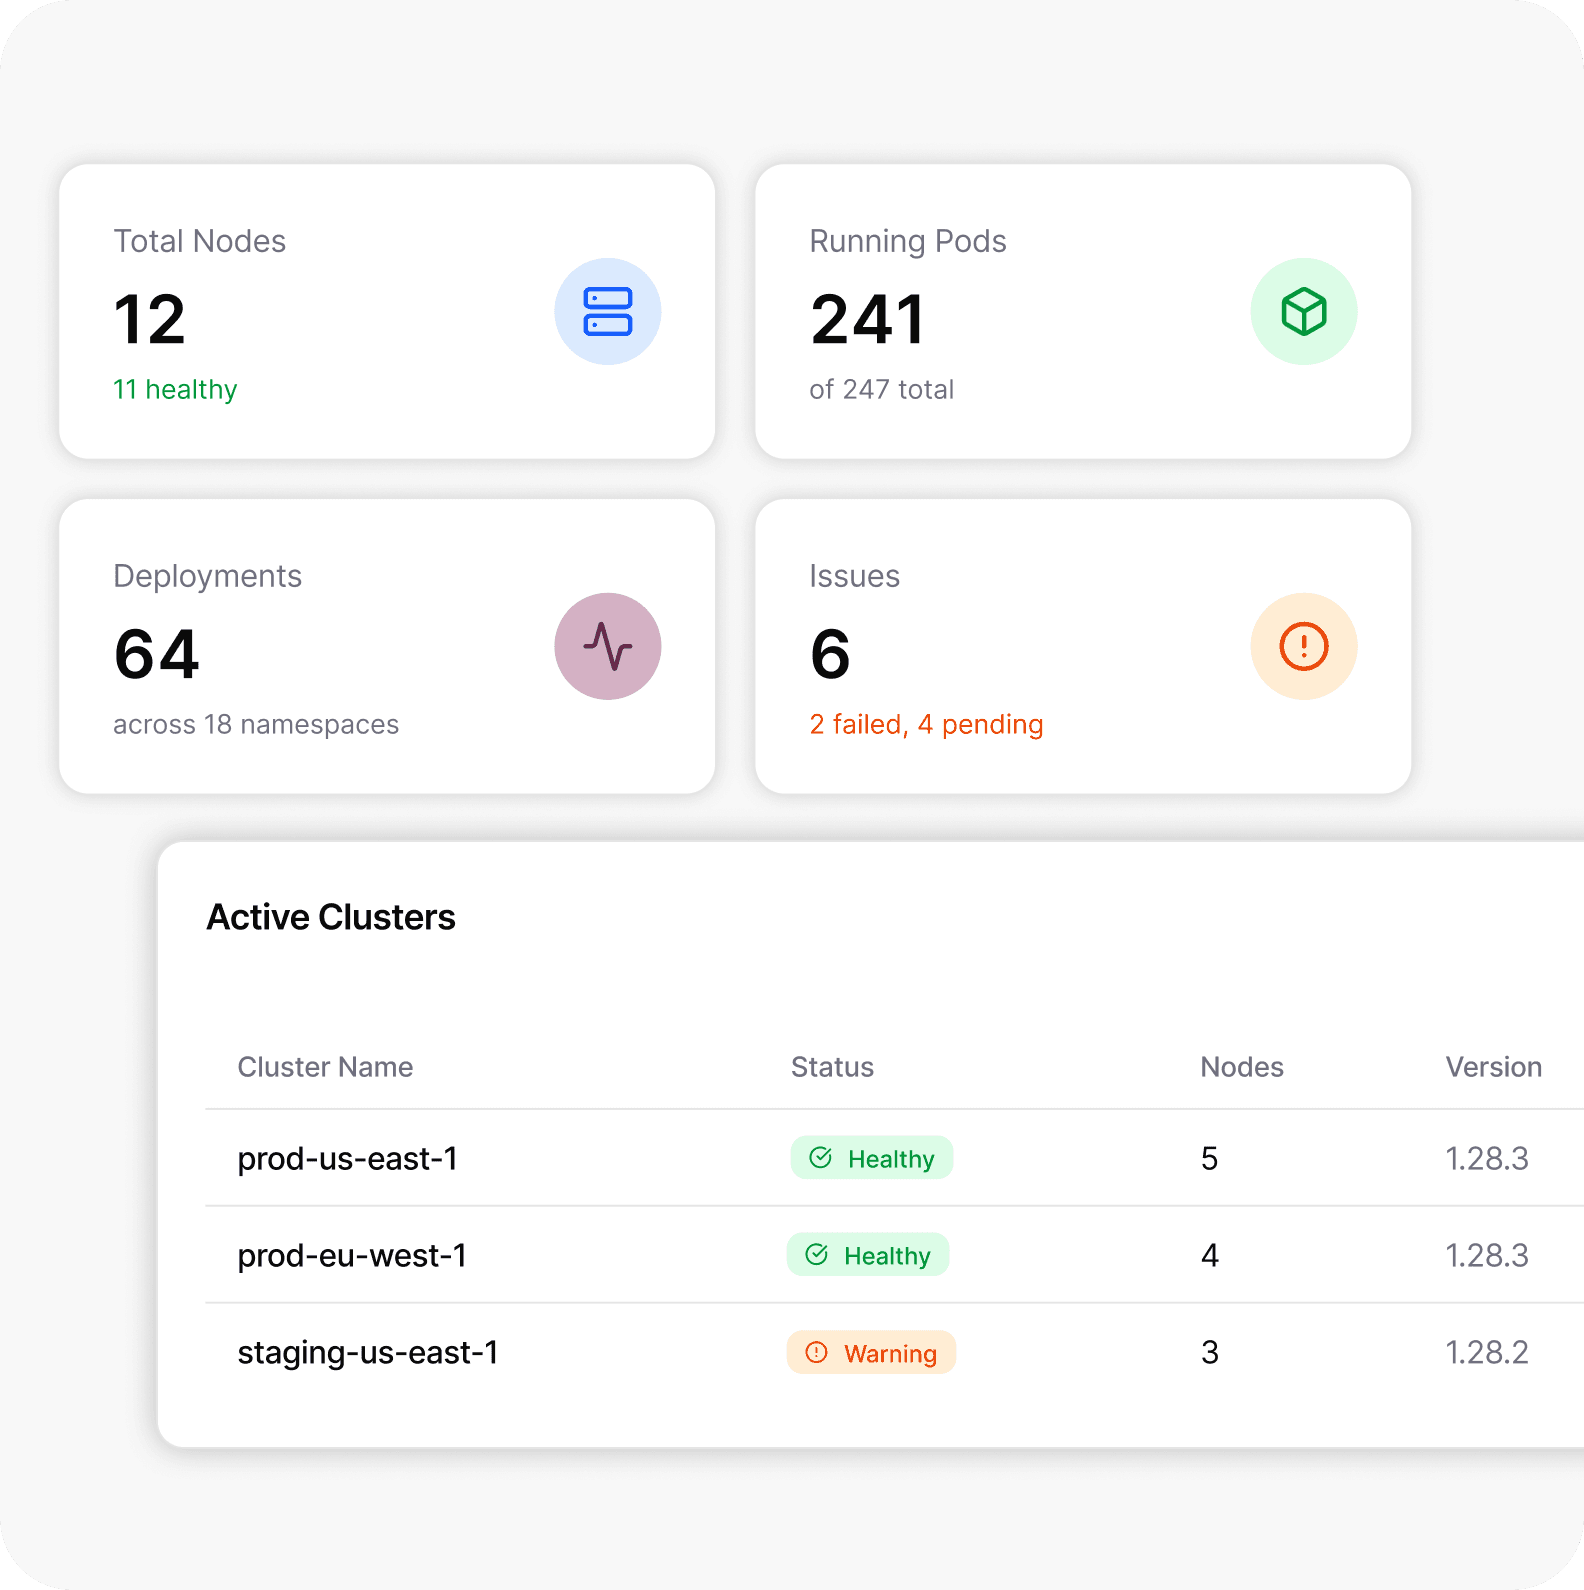
- Deployment observability with metrics, logs, and traces instrumented across your pipeline and live environment.
- Automatic rollback triggers on failed deployments.
- Threshold-based alerting, on-call routing, and documented incident response runbooks.
- Automated smoke tests and health checks that validate every release before it reaches your users.
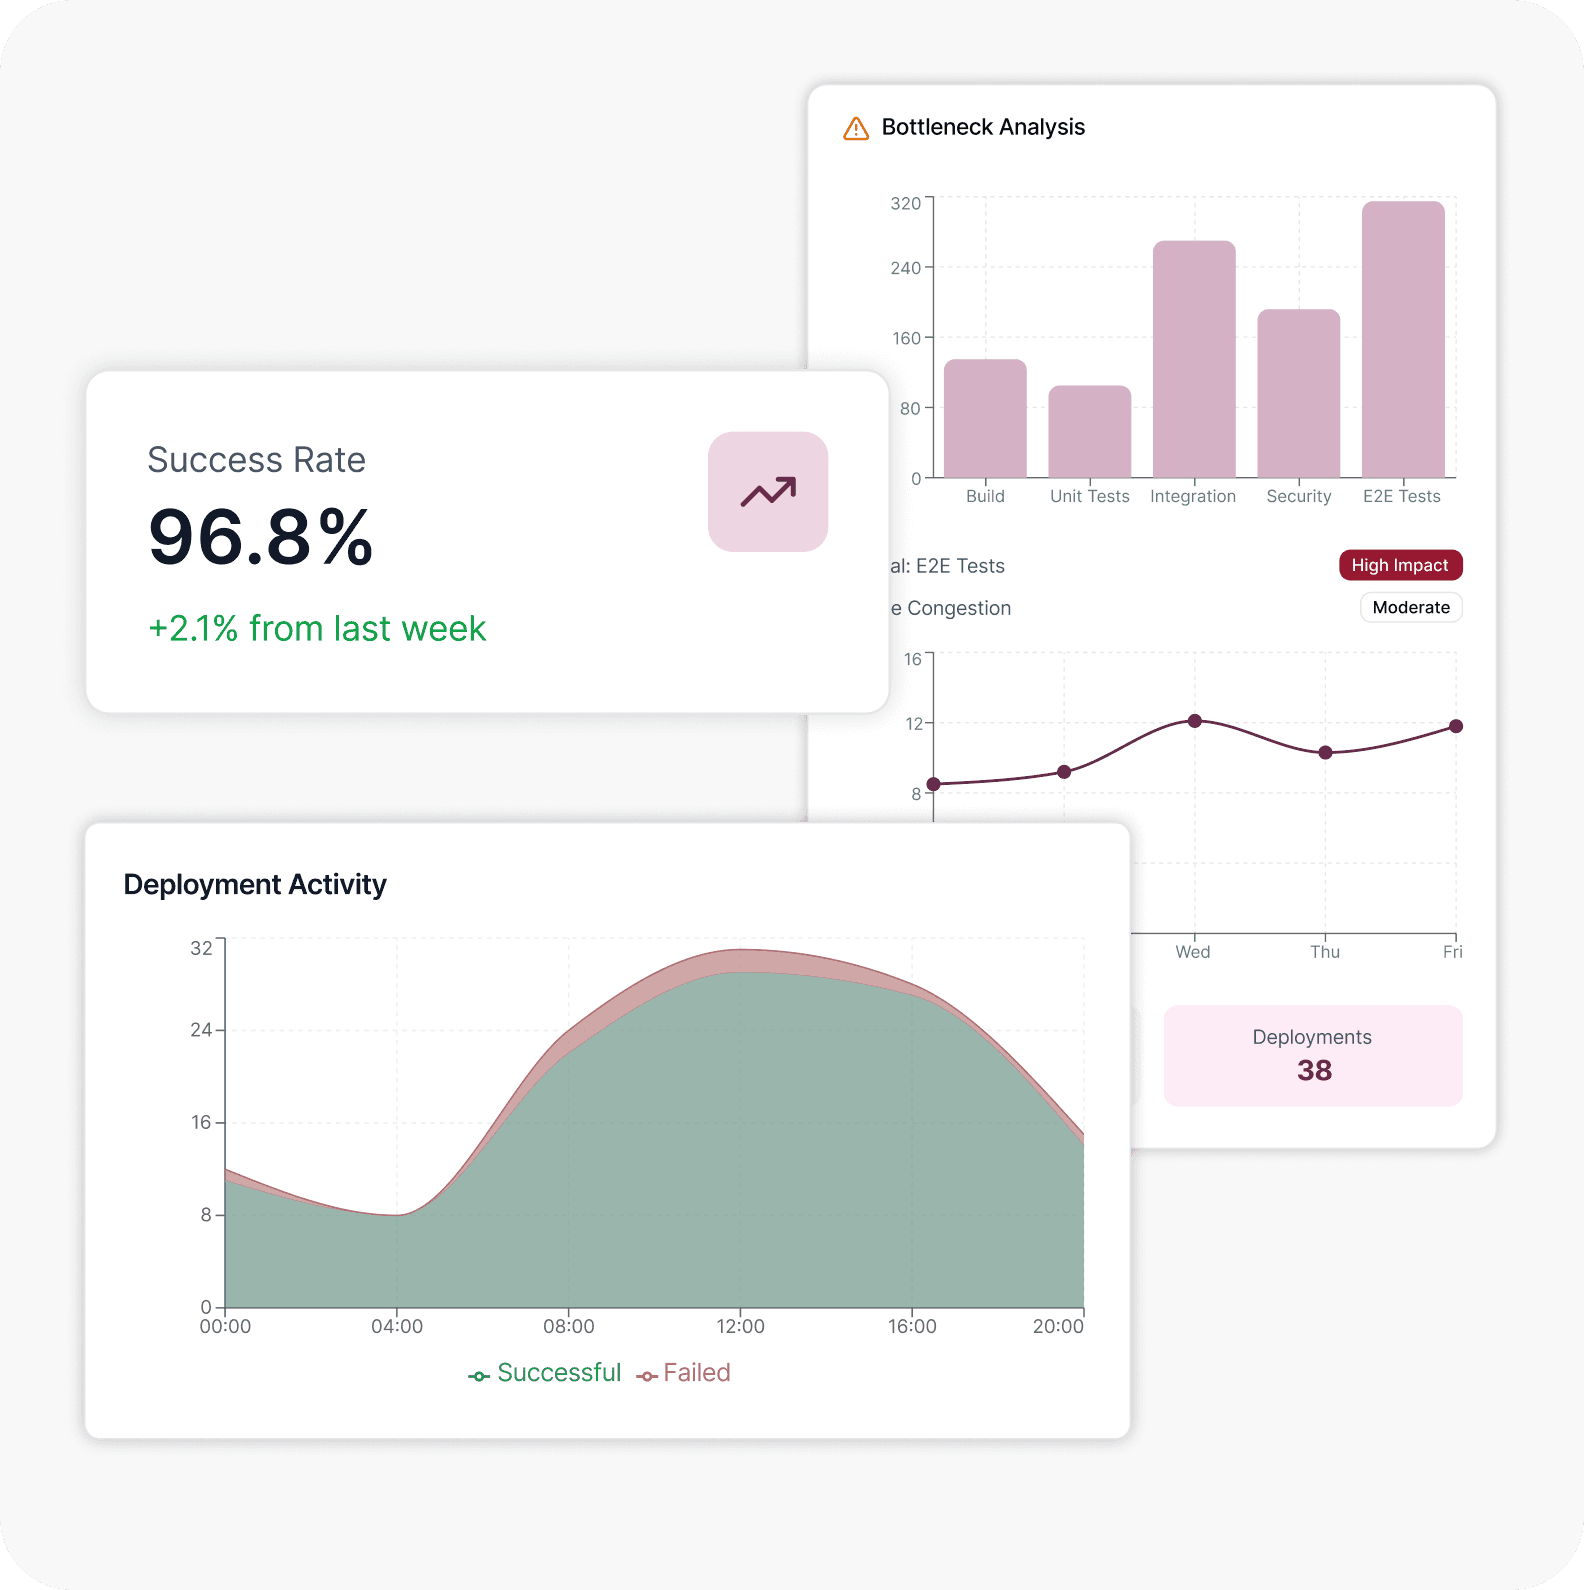
Results and Impact We Will Deliver
Our Deployment and Infrastructure Automation service ensures that deployment does not become a bottleneck for your engineering teams. They are empowered to execute what they do best and rest easy that what they built will be deployed flawlessly.
Deployments Your Team Can Trust
When pipelines are automated and rollback is built in, every release stops feeling like a gamble. Your team ships with a system behind them — not hope.
Environments That Actually Reflect Production
Infrastructure as Code and parity controls mean your staging environment stops being a liability. What passes in testing will behave the same way when it goes live.
Release Velocity That Doesn't Plateau
Removing manual steps from your release process compounds over time. The faster your team can iterate safely, the faster your product moves.
Cloud Spend Matched to Real Usage
Right-sized infrastructure means you stop paying for capacity your workloads don't actually need. Every resource in your environment earns its place.
Industries-Based Deployment and Infrastructure Automation
Every industry ships differently. Compliance requirements, traffic patterns, release cadences, and tolerance for downtime vary enormously — and a deployment architecture that works for a consumer app will fall short in a regulated healthcare or fintech environment. We build for the constraints your team is actually operating within.
Deployment and Infrastructure Automation by Engineering Teams that Have Built 1000+ Global Projects
There's a difference between knowing what a good deployment architecture looks like and knowing why most of them aren't. We've spent years inside the messy reality of production environments: pipelines that grew without a plan, infrastructure that nobody fully understood, and release processes held together by one engineer's institutional knowledge.That experience is what makes our engagements different. We don't arrive with a playbook. We arrive with the diagnostic instincts to figure out what's actually going wrong in your environment, and the engineering depth to fix it properly.
The people scoping your engagement are the same people doing the work. Our engineers have operated deployment infrastructure for products at a significant scale — and they're the ones at the keyboard.
Pipeline design, environment strategy, and release workflows are built around your deployment frequency, team structure, and operational reality — not a standard template applied regardless of context.
We work across AWS, GCP, and Azure with deep experience in Terraform, Pulumi, Kubernetes, Helm, GitHub Actions, GitLab CI, ArgoCD, Datadog, Prometheus, and more. The recommendation is always what fits — not what we happen to prefer.
Everything we hand over is fully operational, thoroughly documented, and built to be run by your team without needing to call us back.
Structured handover sessions, operational runbooks, and documentation written for the engineers who'll own the system — not just for the record.
Our Offerings in DevOps Consulting and Services
Our Latest Thinking
FAQs About Deployment and Infrastructure Automation Services
It covers the full journey from code commit to production — CI/CD pipeline design, Infrastructure as Code, container and Kubernetes configuration, environment standardisation, deployment observability, and release operations. The objective is a fully automated, low-friction release process your team can run without manual intervention or specialised knowledge locked with one person.
Most engagements are completed in three to six weeks. The variables are the number of services in scope, the current state of your pipeline and infrastructure, and how many environments are involved. Platforms operating under compliance requirements or spanning multiple regions may need additional time.
We always start from your current state. Optimising what exists is almost always faster and less disruptive than starting over. Where a meaningful architectural change is warranted, we explain why and manage the transition without impacting your ongoing releases.
That's a design principle, not an afterthought. Every engagement includes structured handover sessions, full infrastructure documentation, and operational runbooks written for the engineers who'll be running the system day-to-day.
Having a pipeline and having a pipeline worth relying on are rarely the same thing. Most established setups carry undocumented steps, configuration inconsistencies, and fragile handoffs that silently add overhead to every release cycle. The cost is usually invisible until something fails publicly.
Fully automated CI/CD pipelines, Infrastructure as Code for all environments, deployment runbooks, observability and alerting configuration, a documented architecture overview, and a handover session with your engineering team.
We're vendor-neutral across AWS, GCP, and Azure, with hands-on experience in Terraform, Pulumi, Kubernetes, Helm, GitHub Actions, GitLab CI, ArgoCD, Datadog, Prometheus, and others. Tool selection is driven by your environment and goals — not our preferences.
Yes. We design access controls, secrets management, automated audit trails, and governance checkpoints for teams operating under SOC2, ISO 27001, HIPAA, or internal regulatory frameworks.
Most teams notice measurable change within the first two weeks — faster deployments, fewer failed releases, less manual overhead. Full pipeline and infrastructure optimisation is typically handed over within four to six weeks.
A new hire spends months getting context before they can meaningfully improve anything. Our team arrives already calibrated and delivers a working, documented system in weeks — without the recruiting overhead, ramp-up cost, or gradual contribution curve.
