

Infrastructure as Code
Environment inconsistencies and configuration sprawl quietly kill engineering momentum until the damage shows up in production.
We take ownership of your infrastructure definition and provisioning workflows from the ground up, so the environments your team depends on are the last thing they ever have to worry about.
Move Beyond Click-Ops to Code-Defined Infrastructure to Automated Infra








Infrastructure debt rarely surfaces dramatically. It builds quietly — a resource provisioned by hand here, a configuration nobody wrote down there, a staging environment that stopped resembling production so long ago nobody remembers when. The bill usually comes due through an incident that version-controlled infrastructure would have made impossible.
Our Infrastructure as Code service exists to break that cycle. We begin by understanding exactly where your provisioning and environment workflows are creating risk, then replace them with code-defined, auditable systems that give your engineering team something they can genuinely depend on.
Client Results and Success
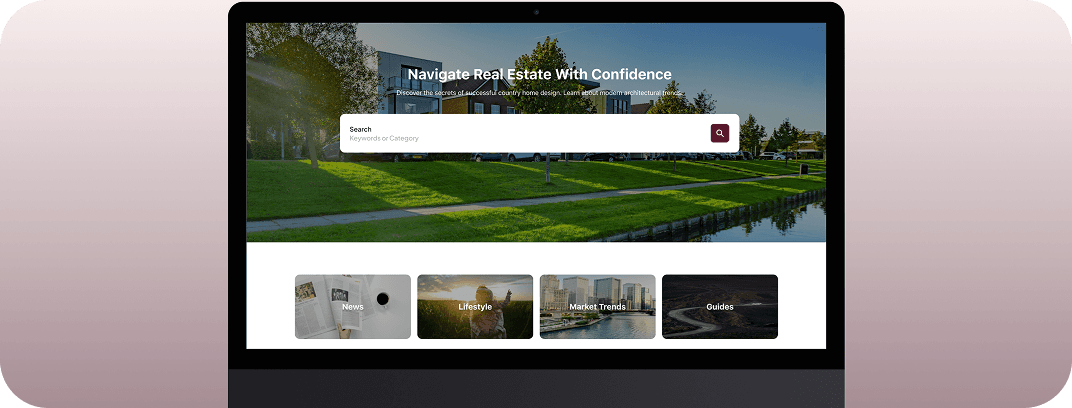
Production-Ready Kubernetes Architecture
The platform was designed to support scalable production deployments with minimal resource consumption, enabling faster environment provisioning and operational stability.
- environments K8s setup
- 3
- environments K8s setup
- 95%
- savings over managed Kubernetes alternatives
- 35%
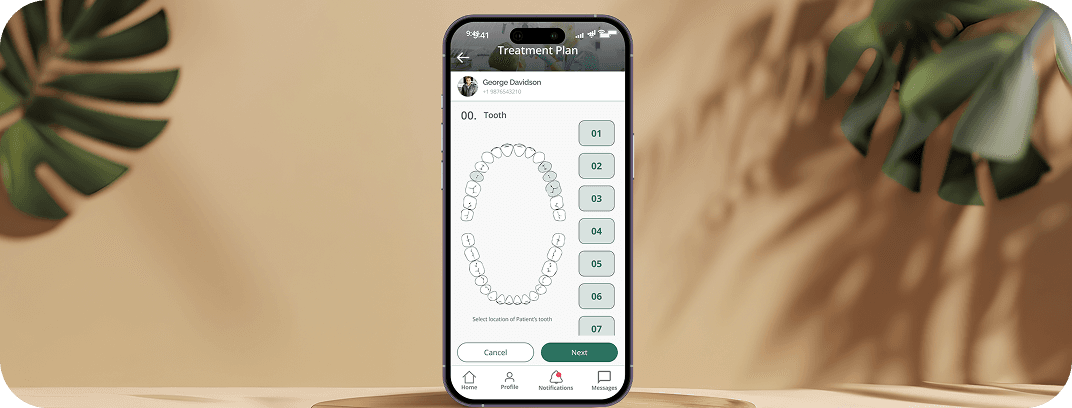
40% Faster Onboarding Completion
The redesigned system achieved a 40% reduction in onboarding completion time, directly improving platform adoption and reducing operational bottlenecks.
- Improvement in the doctor's efficiency for treatment planning
- 35%
- Reduction in onboarding completion time
- 40%
Production-Grade AI Infrastructure
The system supports scalable AI inference and automated inspection workflows, reducing manual intervention and enabling consistent performance under growing usage.
Read case study3× Faster Feature Iteration
The platform achieved 3x faster AI feature iteration cycles, significantly reducing time-to-release for new recommendation
- Reduction in meal decision time
- 40%
- Increase in daily active usage during pilot
- 2x
50% Fewer Manual Validation Cycles
The system achieved a 50% reduction in manual validation cycles, improving throughput and accelerating delivery timelines.
- Reduction in manual validation cycles
- 50%
- Faster internal testing workflows
- 30%
60% Cloud Cost Reduction
The platform achieved a 60% reduction in monthly cloud costs while maintaining uptime and transaction stability during and after optimization.
- Saved per month
- $4,800
- Annual savings
- $57,000+
Our Infrastructure as Code Services
Infrastructure complexity should not be a tax your engineers pay every day. Our services eliminate the friction that comes from manual provisioning, environment drift, and configuration that exists only in someone's head. What replaces it is infrastructure that lives in code and becomes reviewable, repeatable, and reliable.
- Full infrastructure design covering resource definitions, provisioning logic, and environment teardown across your entire stack.
- Environment strategy built around modular, reusable IaC patterns suited to your cloud footprint and team structure.
- Automated environment promotion with drift detection built into the workflow from development through to production.
- Robust state management, dependency resolution, and failure alerting that keep your infrastructure honest..
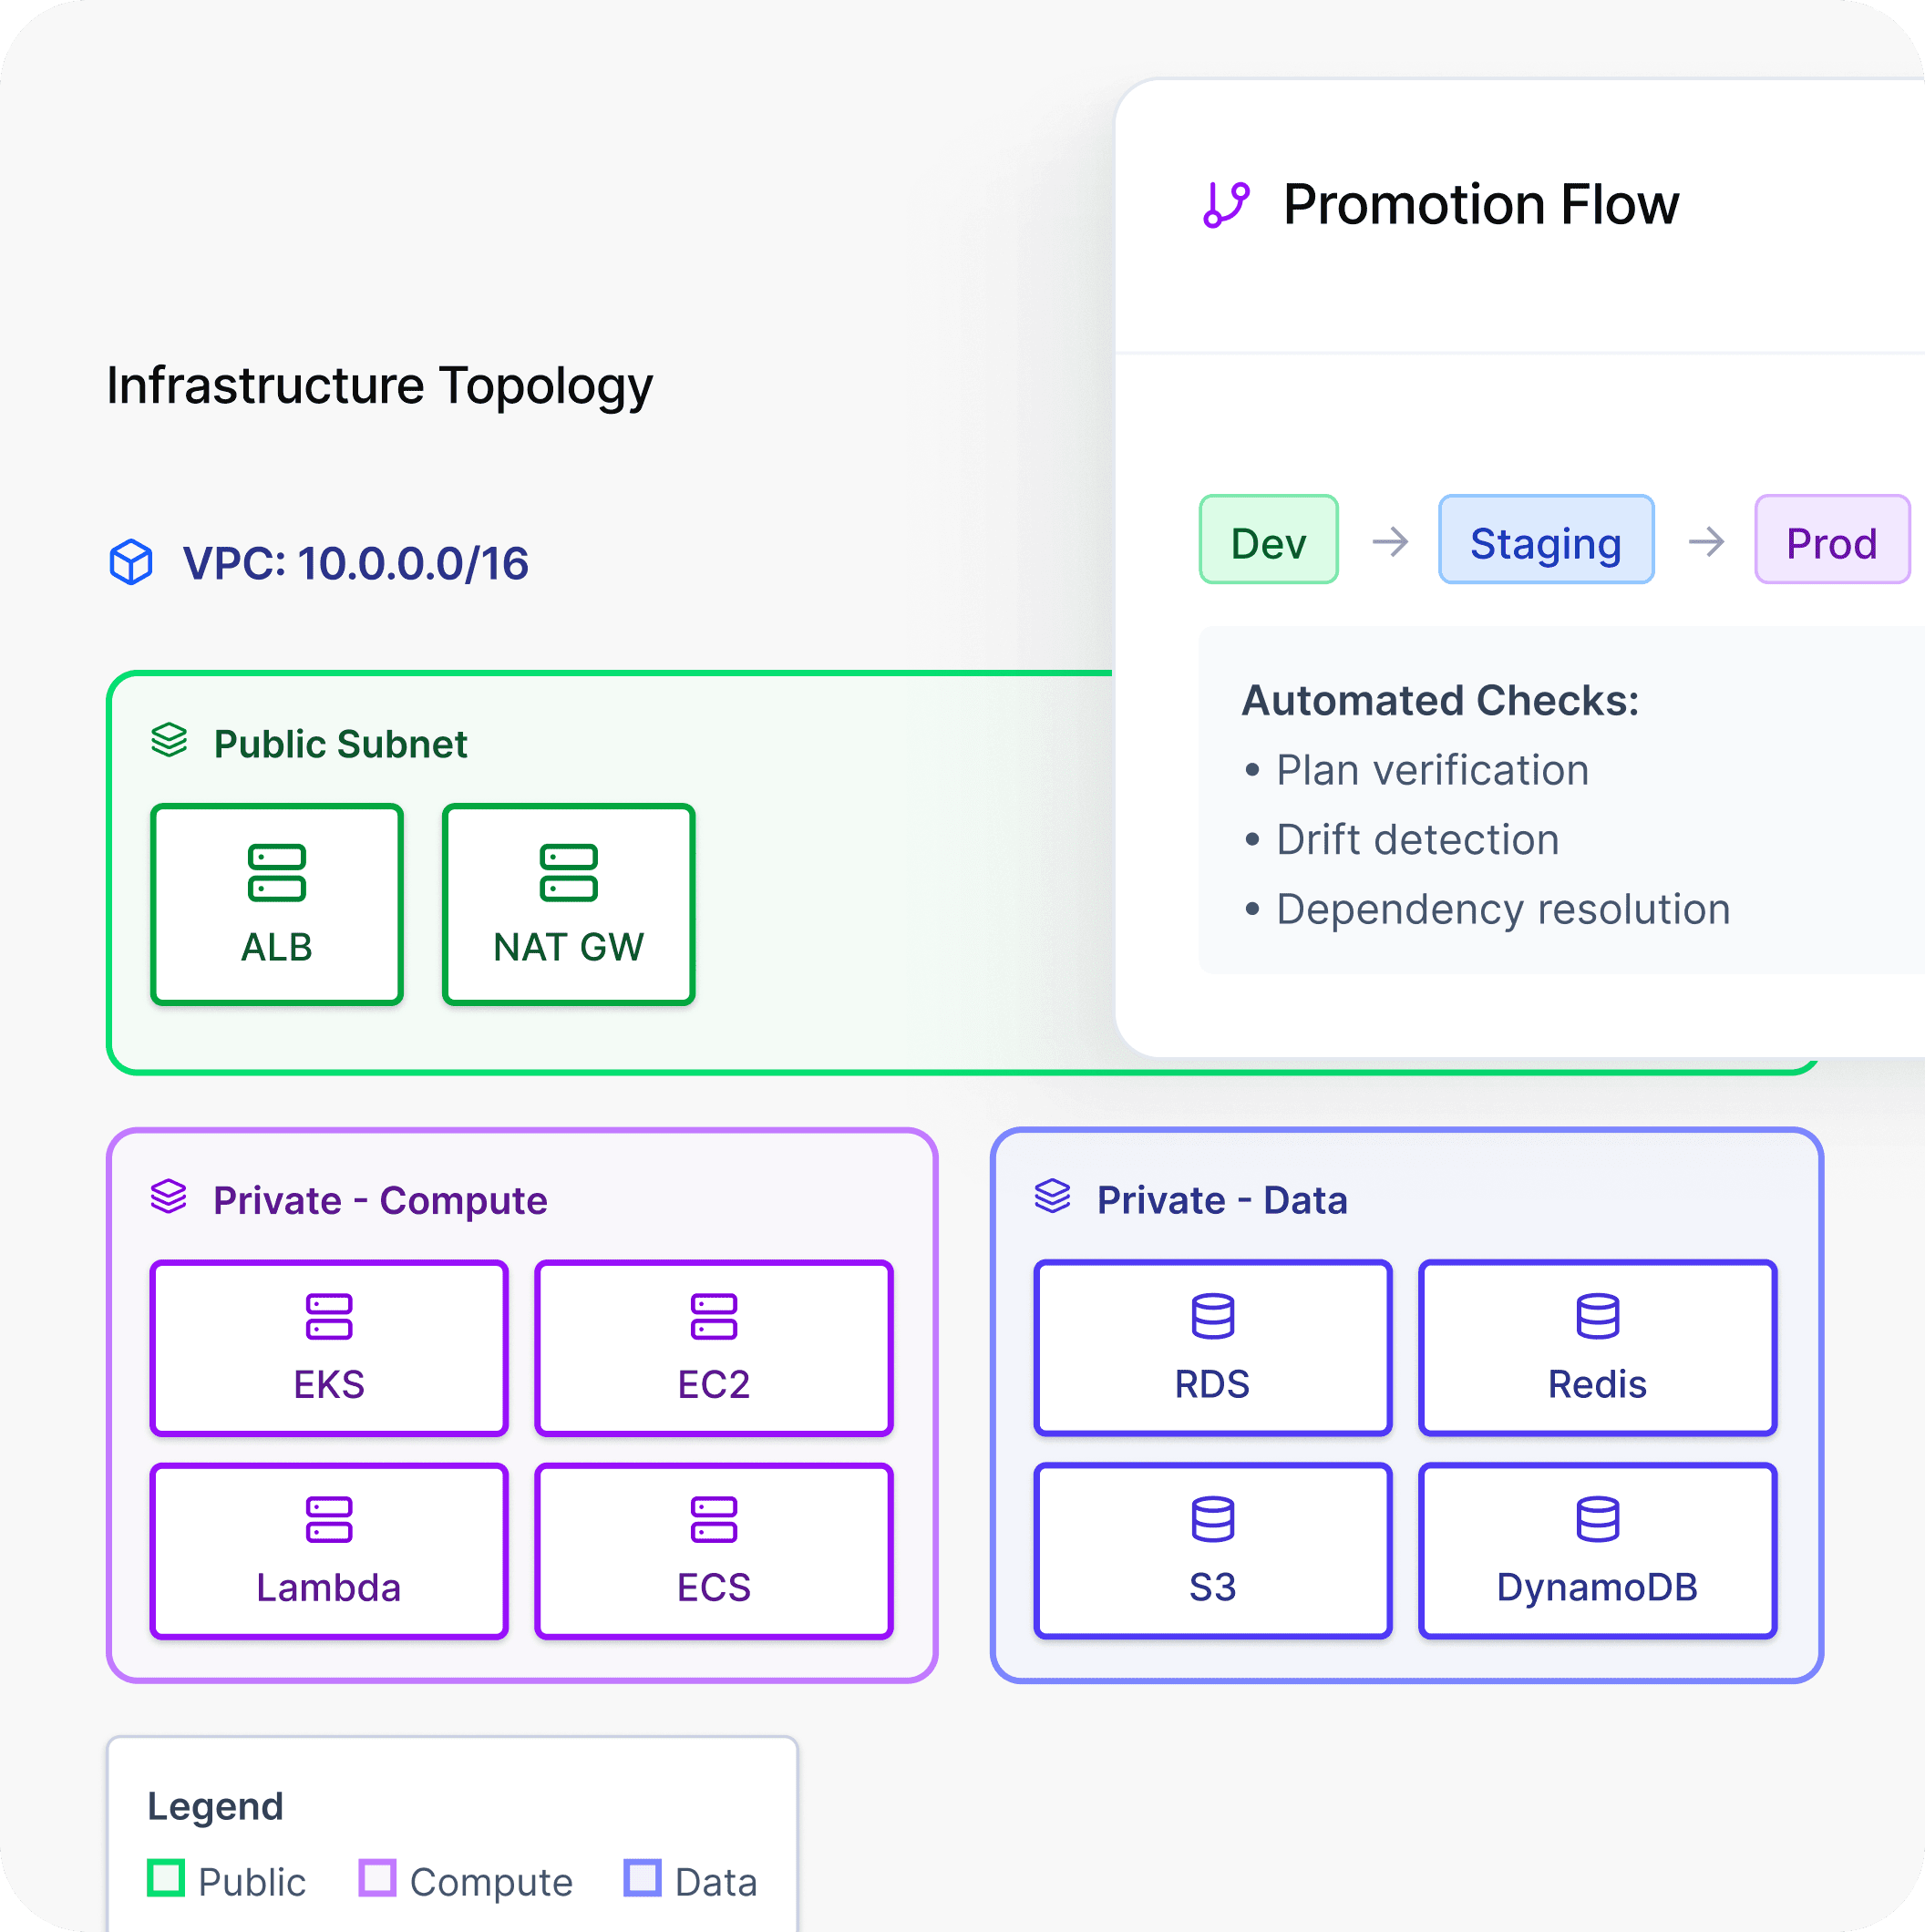
- Terraform and Pulumi module architecture is designed for production-grade environments and built to evolve with your platform.
- Shared module libraries that standardise how infrastructure is defined, packaged, and reused across teams.
- Network topology, internal routing, and traffic management are codified and version-controlled alongside the rest of your infrastructure.
- Scaling policies tied to real workload behaviour, provisioned and updated through code rather than manual adjustment.
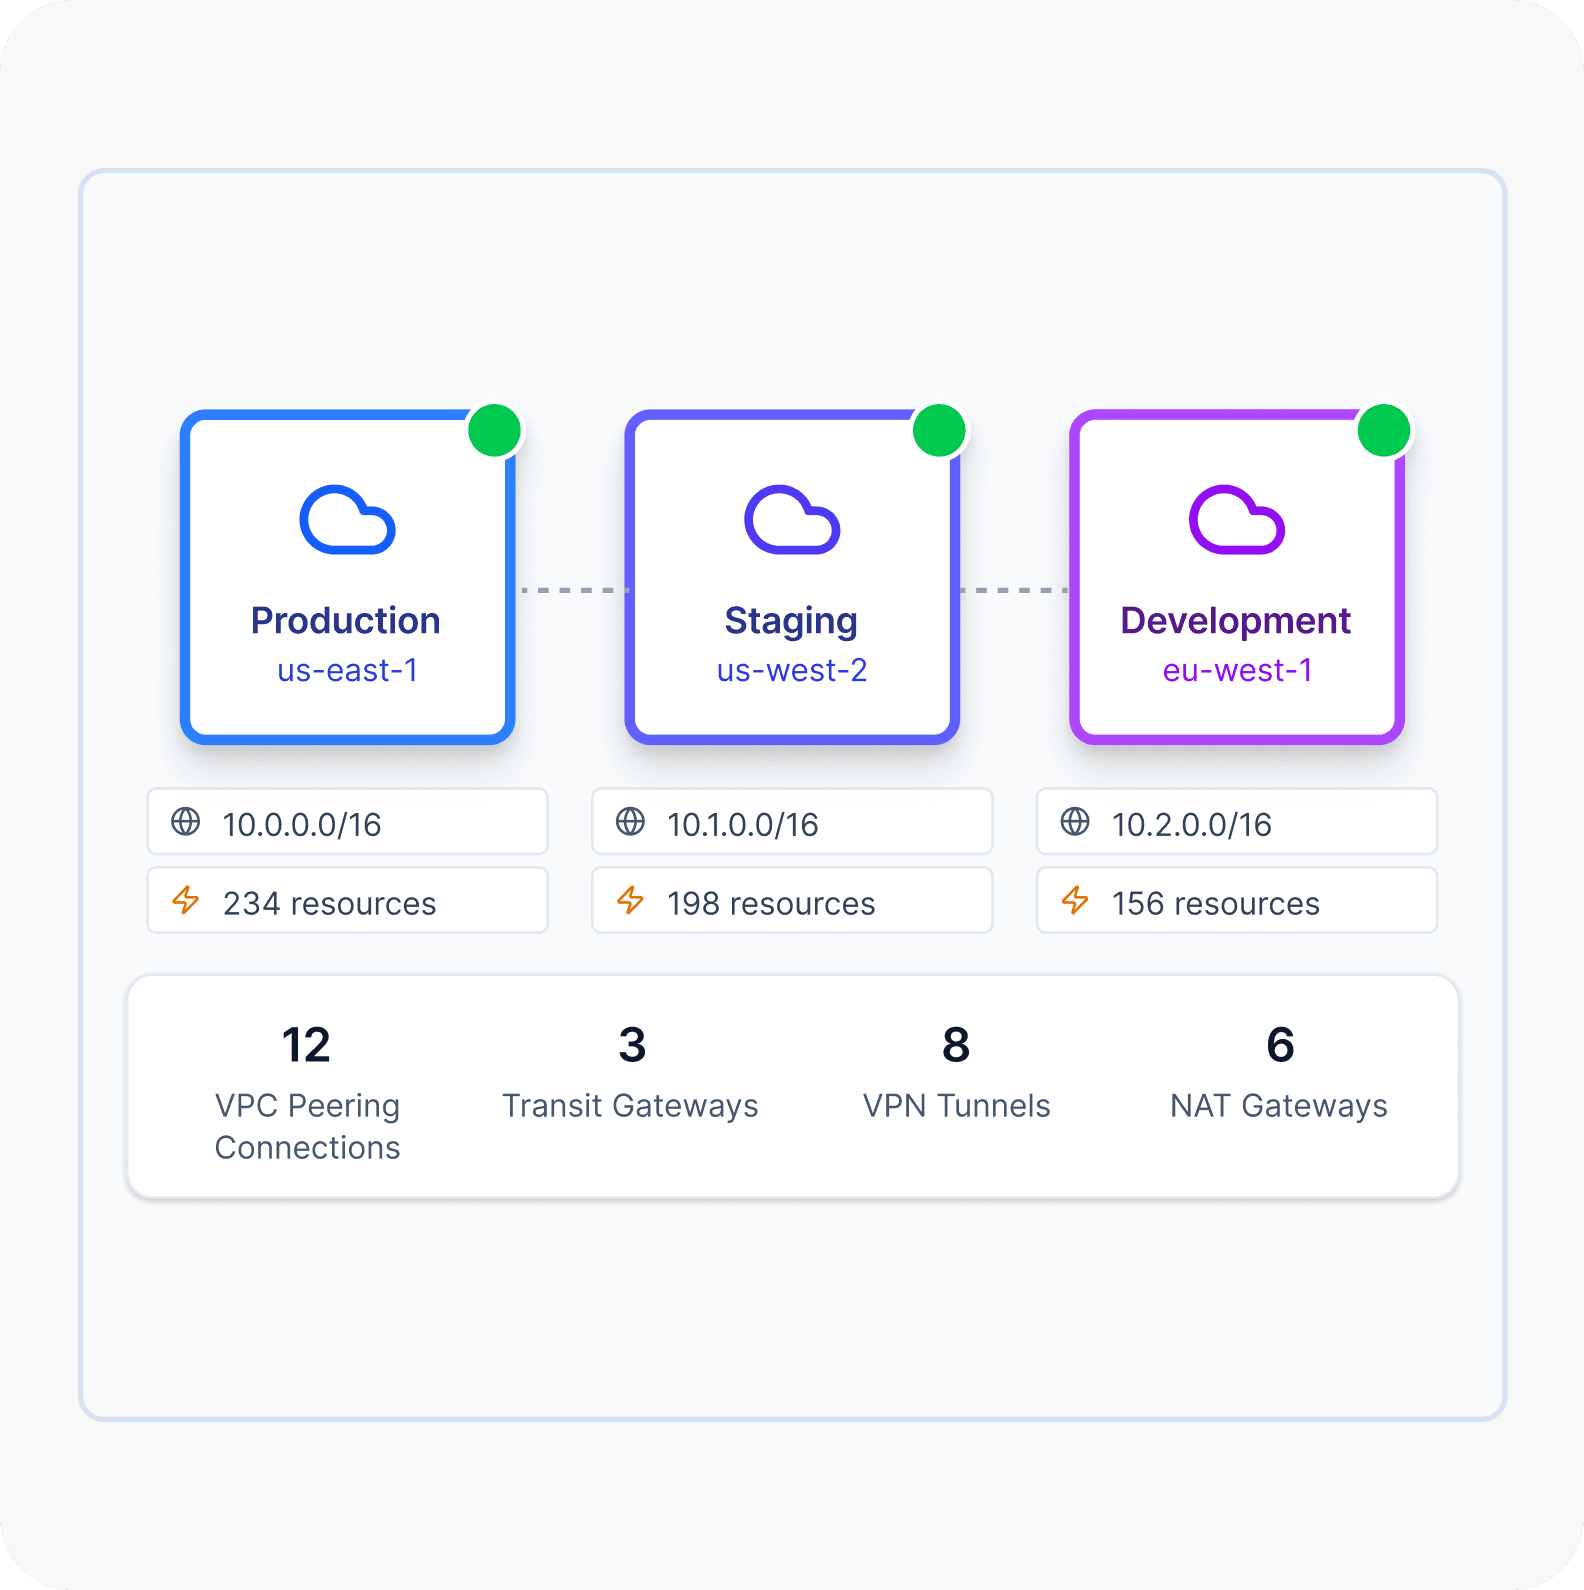
- Full infrastructure change tracking with metrics, logs, and audit trails surfaced across your provisioning workflows and live environments.
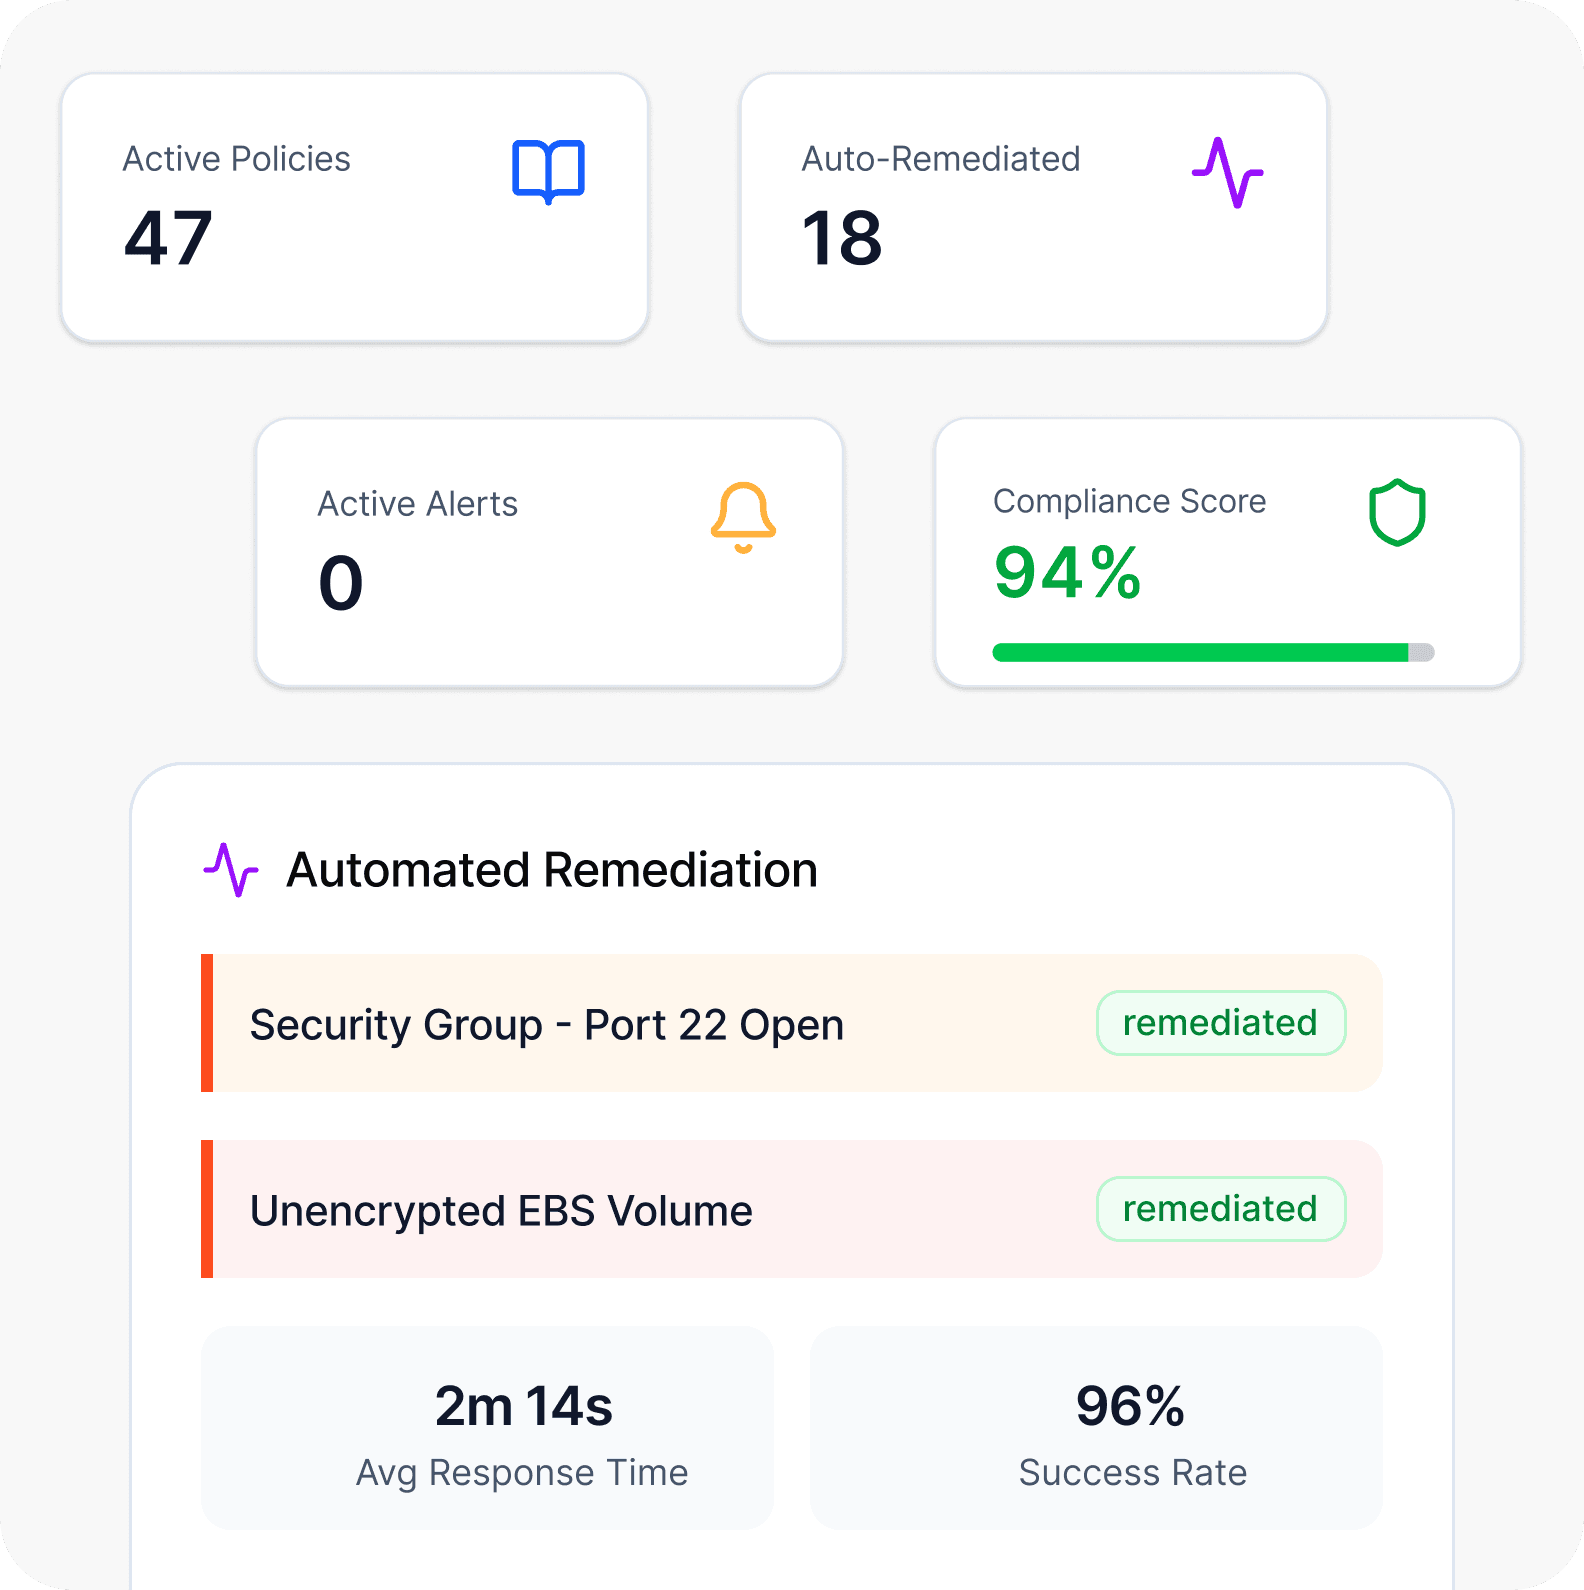
- Automated remediation logic that responds to drift before it becomes an incident.
- Threshold-based alerting, escalation routing, and documented runbooks for infrastructure events.
- Policy-as-code validation and compliance checks that gate infrastructure changes before they reach production
Infrastructure as Code Across Every Industry
Our Infrastructure as Code service removes environment management as a constraint on your engineering team. They stay focused on building. The infrastructure takes care of itself.
Infrastructure Your Team Can Actually Trust
When every resource has a definition and drift is caught automatically, provisioning stops being a source of anxiety. Your team has a system working with them — not against them.
Staging That Behaves Like Production
Code-defined parity means the gap between your environments closes for good. What works in testing works the same way when it matters most.
Provisioning Speed That Scales With Your Team
Every manual step removed from your infrastructure workflow compounds. Faster, safer environment cycles mean your product moves at the pace your engineers are capable of doing.
Cloud Bills That Reflect Reality
Right-sized, code-defined infrastructure means no resource exists without a reason. Your cloud spend aligns to what your workloads actually need — nothing more.
Industries-Based Deployment And Infrastructure Automation
The way infrastructure needs to behave varies enormously depending on where it operates. Compliance obligations, traffic profiles, change frequency, and acceptable blast radius in a regulated fintech environment look nothing like those in a consumer app. We design IaC architectures around the real constraints your team lives within — not a generalised blueprint applied regardless of context.
Infrastructure as Code from Engineers Who Have Operated It at Scale Across 1000+ Projects
Understanding what well-written IaC looks like is straightforward. Understanding why most production infrastructure isn't — and what it takes to fix it — comes from experience. We've worked inside environments where provisioning was tribal knowledge, where modules had never been refactored, and where nobody was entirely sure what would happen if they ran a plan against production.That's the background we bring to every engagement. Not a framework applied generically, but the judgment to understand what's actually failing and the engineering capability to address it properly.
There's no handoff to a delivery team after the sales conversation. The engineers who assess your environment are the same ones writing your Terraform, managing your state, and building your modules.
Module design, state management strategy, and environment architecture are shaped by your provisioning cadence, team structure, and platform constraints — not a one-size-fits-all approach borrowed from a different use case.
We work across AWS, GCP, and Azure with deep practical experience in Terraform, Pulumi, Kubernetes, Helm, GitHub Actions, GitLab CI, ArgoCD, Datadog, Prometheus, and more. The right tool is whatever fits your environment best.
Everything delivered is production-ready, fully documented, and designed to be operated by your team independently. The goal is for us to become unnecessary.
Handover sessions, operational runbooks, and documentation are written for the engineers inheriting the system — with enough context to own it, extend it, and make good decisions about it going forward.
Our Offerings in DevOps Consulting and Services
Our Latest Thinking
FAQs About Infrastructure as Code Services
We cover everything from initial resource definition to fully operational environments — module architecture, Terraform or Pulumi implementation, state management, environment standardisation, drift detection, and infrastructure observability. The end state is a provisioning workflow your team can operate without relying on manual steps or knowledge that lives with one person.
Most are wrapped up within three to six weeks. The timeline depends on how many environments are in scope, the current condition of your infrastructure and configuration management, and whether compliance or multi-region requirements are involved.
We start from where you are. Codifying and improving existing infrastructure is almost always the faster path. When a structural change makes sense, we make the case clearly and handle the transition in a way that doesn't disrupt what's already running.
That's the whole point. Every engagement is designed to leave your team with a system they understand and can operate. Handover sessions, runbooks, and documentation are standard — not optional extras.
Having infrastructure written in Terraform and having infrastructure you can trust are two different things. Most codebases that grew organically carry unmanaged state, inconsistent modules, and undocumented dependencies that accumulate overhead with every change cycle. Those gaps tend to stay invisible until something breaks visibly.
Modularised IaC across all environments, configured state management, provisioning runbooks, observability and alerting setup, a documented architecture overview, and a structured handover session with your engineering team.
We're cloud-agnostic across AWS, GCP, and Azure, with hands-on experience in Terraform, Pulumi, Kubernetes, Helm, GitHub Actions, GitLab CI, ArgoCD, Datadog, Prometheus, and others. Tool recommendations are based on what works for your environment — not what we're most comfortable with.
Yes. Access controls, secrets management, audit trail automation, and policy-as-code governance are part of how we build for teams operating under SOC2, ISO 27001, HIPAA, or their own internal compliance frameworks.
Most teams see meaningful change within the first couple of weeks — faster provisioning, more consistent environments, and less time spent on infrastructure management. The full implementation is typically complete and handed over within four to six weeks.
A new hire needs months to develop the context required to make meaningful changes to production infrastructure. Our team arrives with that context already built, delivers a working and documented system in weeks, and does so without the recruiting timeline, onboarding overhead, or slow ramp-up curve.
