
Feature flags are one of the cheapest tools in engineering to adopt and one of the most expensive to leave unmanaged. Teams use them for gradual rollouts, A/B tests, kill switches, and gating unfinished work, but few teams have a matching process for removing them once they have served their purpose. As a result, flags that were meant to be temporary become permanent, adding unnecessary complexity to the codebase.
This article explains why flag cleanup gets skipped and why it creates a real engineering cost. It also walks through a staleness-detection implementation, a flag-removal exercise, and a practical checklist for managing flags across their full lifecycle, from creation to removal.
Why Flags Are Easy to Add and Hard to Remove
Adding a flag is a small, fast PR. Wrapping a block of code in a conditional and wiring it to a config value takes minutes, and it ships in the same PR as the feature it gates — there's no separate approval step, no extra review, no reason for anyone to push back. Removing a flag involves a different kind of work. You have to find every place it is checked, including references in logging, analytics, and monitoring code, confirm which branch is now permanently "on" or "off," delete the dead branch, update or delete the tests that covered it, and verify that nothing downstream depends on the old behavior. This multi-step effort competes with new feature work for the same sprint capacity, so cleanup often gets pushed to a later sprint until the flag becomes a permanent part of the codebase.
There's also a confidence problem. Once a flag has been live for months, the person who added it may have moved teams, changed roles, or forgotten why it was added. Removing the conditional can feel risky when its dependencies are unclear, so teams may leave it in place. That decision can turn a two-week release flag into a permanent part of the codebase.
Underneath both of these is a structural gap: a flag rarely comes with a ticket, an expiry date, or a named owner responsible for its removal. By default, creating a flag does not create a corresponding task to revisit it later. Without documented future work, the flag can remain in place. Meanwhile, teams add new flags every sprint while removing few of the old ones, so the backlog grows and cleanup becomes more complex as additional flags enter the same code paths.
The Flag Lifecycle
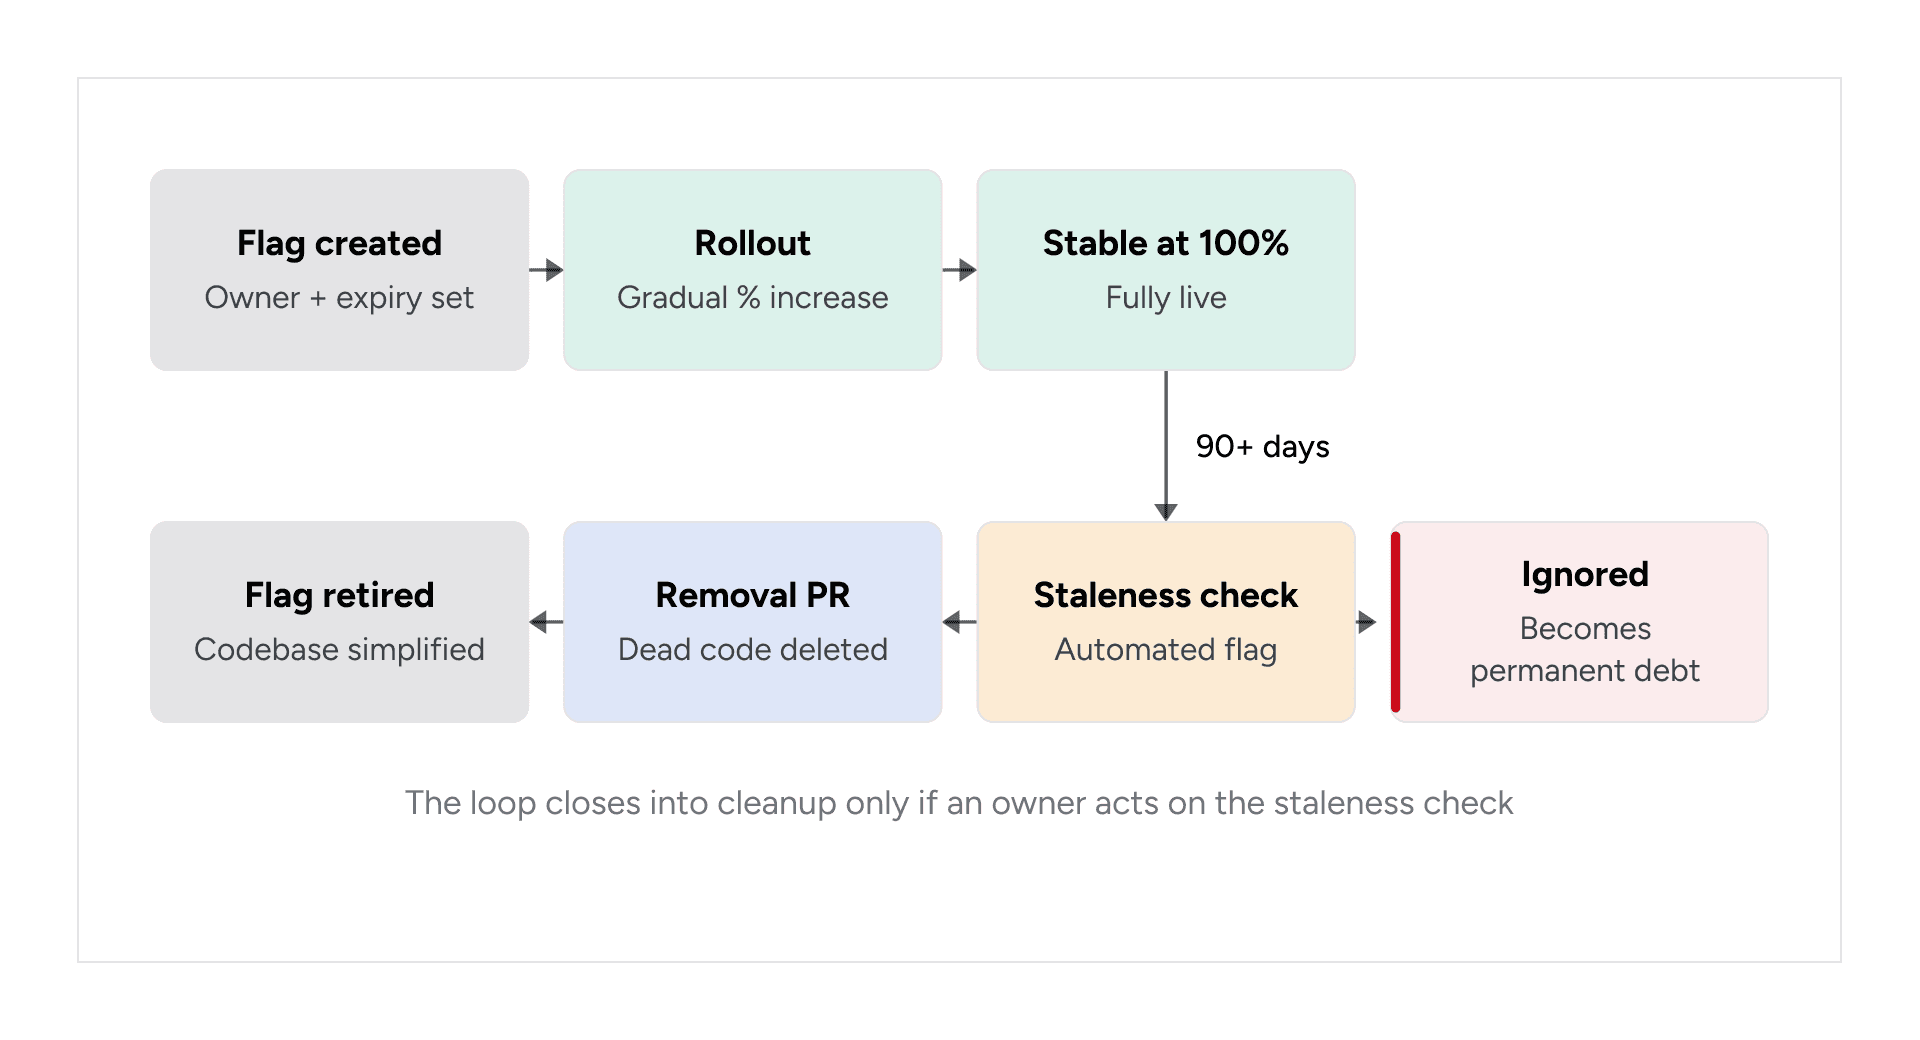
The diagram below lays out the full path a flag should take, from creation to retirement. The critical fork sits in the middle of the diagram: once a flag reaches "stable at 100%," it either gets caught by an automated staleness check and routed to a removal PR, or it gets ignored and drifts into permanent technical debt. Most flags fail at exactly this point — not because removal is technically difficult, but because nothing in the default engineering workflow forces the question to be asked. Without an automated trigger, a flag can sit at "stable" for years with nobody ever explicitly deciding to leave it that way; it simply never comes up.
Why This Is a Real Cost, Not Just Clutter
Each independent binary flag can double the number of possible runtime states. A function gated by three independent flags can have up to eight possible states, but teams may have designed or tested only a subset of those combinations. The remaining states can introduce interactions that were not considered during development or testing.
Stale flags can create bugs through untested interactions. Two flags that are each considered "basically always on" can still interact in a combination the team did not anticipate. If the team assumes that only one meaningful state is live, that interaction may not be covered during testing or code review and can surface only under production traffic.
New engineers may avoid code affected by unfamiliar flags. When it is unclear which flags are critical and which can be removed, team members may work around that code rather than risk breaking an unknown dependency. This can slow down simple changes and introduce workarounds that add further complexity.
The number of dependencies can grow the longer a flag remains in place. Flag checks can extend into related systems, including analytics events tied to flag state, log lines that reference the flag, monitoring dashboards built around it, and configurations in other services. As these dependencies accumulate, removing the flag can require changes across several parts of the system.
Not All Flags Are the Same
A major reason cleanup gets mishandled is that teams treat every flag the same, even though the appropriate lifespan depends on why the flag exists. Classifying a flag at creation establishes its expected lifespan and removal requirements before the original context is lost.
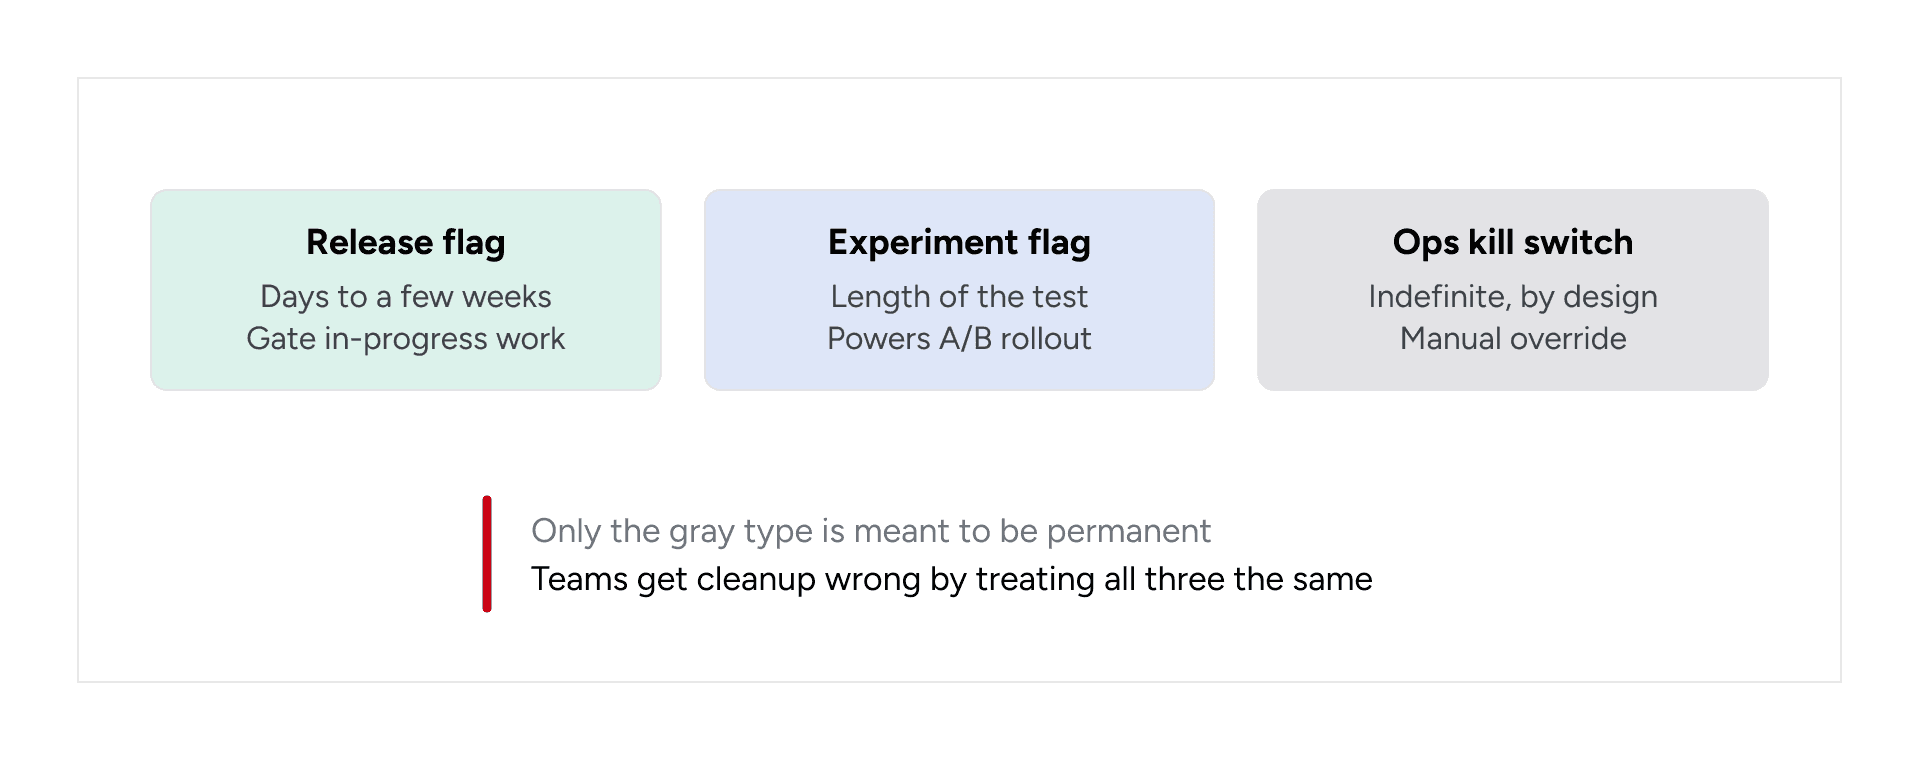
Flag type | Typical lifespan | Purpose | Cleanup urgency |
|---|---|---|---|
Release flag | Days to a few weeks | Gates an in-progress feature during development and rollout | High — remove immediately after 100% rollout stabilizes |
Experiment flag | Length of the test | Powers an A/B test or gradual, data-driven rollout | High — remove as soon as the experiment concludes, win or lose |
Ops / kill-switch flag | Indefinite, by design | Manual override for a risky dependency or emergency control | Low — meant to persist; review periodically instead of removing |
The table highlights a common cleanup problem: a release or experiment flag with a short intended lifespan can receive the same caution as an ops kill switch designed to remain in place. That mismatch can turn a two-week flag into a permanent one.
Building the Staleness Detector
The checklist below recommends automating staleness detection, so it helps to show what that implementation looks like. The following example presents the core logic, simplified for readability. In practice, it receives data from the flag provider in use, such as LaunchDarkly, Unleash, or a homegrown configuration table, with each flag providing a rollout percentage, type, and the length of time its state has remained unchanged.
# Flags anything sitting at 0% or 100% rollout longer than its
# type's threshold. Run weekly; post the output to Slack.

THRESHOLDS = {"release": 14, "experiment": 45, "ops": 365}

def is_stale(flag, days_unchanged):
    if flag["rollout_percentage"] not in (0, 100):
        return False  # still ramping, not a cleanup candidate
    return days_unchanged >= THRESHOLDS[flag["type"]]

def build_report(flags):
    stale = [f for f in flags if is_stale(f, f["days_unchanged"])]
    for f in stale:
        owner = f.get("owner", "UNASSIGNED")
        print(f"{f['key']} ({f['type']}, {f['rollout_percentage']}%) "
              f"— owner: {owner}, unchanged {f['days_unchanged']} days")
Two design choices here matter more than the code itself:
Thresholds are per-type, not global. A single "flag unchanged for 90 days" rule either fires constantly on ops flags that are correctly untouched, or lets release flags rot for far too long. Splitting the threshold by type — pulled directly from the classification the team should already be doing at creation — makes the report something people trust instead of something they learn to ignore.
The report identifies UNASSIGNED owners. An unowned stale flag has no person or team responsible for acting on the report, which can leave it in the codebase without a clear path to removal. Surfacing that ownership gap instead of defaulting to "team lead" makes responsibility for cleanup visible.
Wiring this into a weekly Slack post or a lightweight internal dashboard, including a spreadsheet as a starting point, turns staleness into something the team reviews on a fixed cadence rather than discovers during an unrelated investigation.
Removing a Stale Flag: A Worked Example
Detection is only half the problem. Deleting a flag safely requires a defined procedure because missed dependencies can create production issues. The sequence below shows how to remove a release flag that has remained at 100% for several weeks, using a checkout-discount flag as an example.
- Confirm the resolved state, not just the current one. Check the flag's rollout history, not just its current value — a flag sitting at 100% today that was flipped back to 0% twice in the last month is not actually stable, regardless of what the staleness report says this week.
- Search for every reference, not just the obvious one. A project-wide search for the flag's key (checkout_discount_v2) can reveal references beyond the if branch in the checkout service, including a log line that prints the flag's value, an analytics event property, and a conditional in a monitoring dashboard's alert query. All of these references need to be accounted for so the cleanup does not leave dead references behind.
- Delete the dead branch, not just the flag check. Before removal, the code checks the flag and branches between apply_discount_v2(cart) and apply_discount_legacy(cart). After removal, it calls apply_discount_v2(cart) directly, with both the flag check and the unused branch removed. Leaving both branches as dead code "just in case" preserves unnecessary code outside the flag inventory. If apply_discount_legacy has no other callers, remove it as well.
- Remove the tests for the dead branch, not just add tests for the surviving one. The legacy-path test coverage is now testing code that no longer exists in any reachable state; leaving it in the suite either silently rots (mocking a function that's been deleted) or keeps a maintenance burden alive for behavior nobody can trigger anymore.
- Ship it as its own PR, reviewed as a deletion. Bundling flag removal into an unrelated feature PR can reduce the attention given to the search results from step 2. A standalone "remove checkout_discount_v2" PR keeps the review focused on deletion. Any addition in that diff warrants additional review.
This procedure is often undocumented, which can make cleanup PRs feel riskier than they are.
When Cleanup Doesn't Happen: A Technical Walkthrough
The scenario below illustrates a failure pattern common enough that most teams running flags at any scale will recognize a version of it, even if the specifics differ.
A team adds checkout_discount_v2 to gate a new checkout flow. The rollout succeeds within two weeks and reaches 100% — by every functional measure, the flag has done its job. But it stays in the code for over a year, because removal was never written into any ticket and nobody was assigned to come back to it.
Months later, a second flag, checkout_pricing_experiment, is added to the same checkout path for an unrelated pricing test. It runs after the discount flag: it takes whatever total the discount logic produced and applies an experimental pricing adjustment on top.
Individually, each flag was tested and behaved correctly. However, apply_experimental_pricing was written and reviewed under the assumption that total came from apply_discount_legacy. By that point, checkout_discount_v2 had remained at 100% long enough that engineers working on the checkout path no longer considered it a meaningful variable, even though it remained in the code and continued to execute.
apply_discount_v2 returned a total that had already been floored to two decimal places; apply_discount_legacy had not. apply_experimental_pricing applied a percentage multiplier and then rounded. This worked with apply_discount_legacy's unrounded output but could produce an off-by-one-cent total with apply_discount_v2's pre-rounded output for a narrow set of cart values. This type of bug can escape testing when no test covers the combination of two flags operating on the same code path.
The fix required a two-line change to apply rounding consistently in one place. The greater cost came from the bug reaching production and requiring someone to identify a cent-level discrepancy in reconciliation data and trace it through a code path that was not expected to contain two active flags.
This is the pattern the checklist below is designed to prevent: the gradual accumulation of untracked complexity that can lead to production issues.
Build vs. Buy: Tooling Trade-offs
Teams generally use one of three approaches for flag management, and the right choice depends less on team size than on how comfortable the organization is with an external SaaS dependency in the request path.
Approach | Strengths | Trade |
|---|---|---|
Managed platform (e.g. LaunchDarkly) | Rich targeting rules, built-in audit log and change history, staleness/insights features out of the box, minimal setup time | Recurring cost that scales with seats/MAU; another network dependency in the request path; staleness detection still needs an owner to act on it |
Open-source self-hosted (e.g. Unleash) | No per-seat cost, full control over data residency, extensible | Team owns uptime, upgrades, and scaling of the flag service itself; fewer built-in insights than managed platforms unless configured |
Homegrown config table | Zero new infrastructure, trivial to query directly for a custom staleness report like the one above | No UI, no audit trail unless built deliberately, easy for targeting logic to sprawl across the codebase instead of staying centralized |
The staleness detector shown earlier works with all three approaches because it requires only a list of flags with a rollout percentage and a last-modified timestamp. This keeps the implementation compatible with each approach. Managed platforms may expose this information through a report or webhook, while the other two approaches can use the script above or a similar implementation. The tooling decision affects how much the team needs to build, but each approach still requires a process for detecting stale flags and assigning cleanup work.
A Practical Checklist for Managing Flag Lifecycle
Each step below maps directly onto a stage in the lifecycle diagram — together they're what turns the diagram from an aspiration into something a team actually follows.
Step | What it involves | Why it matters |
|---|---|---|
1. Classify at creation | Tag the flag as release, experiment, or ops at the moment it's created | Sets the correct removal expectation from day one |
2. Assign owner + expiry | Name a person or team and set a target removal date, even if it is approximate | A flag without an owner or deadline can remain in the codebase without a clear removal path |
3. Bake removal into the ticket | Add "remove the flag" as part of the original story's definition of done | Removes the need to re-prioritize cleanup later, when it always loses |
4. Automate staleness detection | Run a scheduled check for flags at 0% or 100% beyond their type-specific staleness threshold | Makes stale flags visible without relying on memory |
5. Maintain a flag inventory | Dashboard of every live flag, its type, owner, and age | Answers "how many flags do we actually have" at a glance |
6. Recurring review cadence | Review flag owners against staleness data each month or quarter | Catches drift before the backlog becomes unmanageable |
7. Prioritize removal PRs | Treat flag-deletion PRs as focused cleanup work | These PRs remove code rather than add it, which can reduce the review scope |
A note on step 2: individual ownership can become outdated when the named owner changes teams or leaves the company. Tying ownership to a service or feature area rather than a specific person provides continuity when personnel change and reduces the risk of flags becoming orphaned.
Closing Thought
Feature flags are useful, but flag creation represents only part of their lifecycle. A temporary flag without a removal plan can become a permanent addition to the codebase and increase its complexity over time.
Closing that gap requires a per-type staleness threshold, a script that checks it on a schedule, and a removal procedure that treats deletion PRs as part of planned engineering work. This approach builds removal into the same process as creation, classifies flags by type when they are created, and uses automated staleness checks to identify flags that require attention. Together, these changes make flag removal part of the same engineering process as flag creation.
Make Feature Flag Cleanup Part of the Engineering Lifecycle
Feature flags work best when removal is treated as part of the same engineering lifecycle as creation and rollout. Clear ownership, type-specific staleness checks, scheduled reviews, and focused removal PRs help teams prevent temporary controls from becoming permanent technical debt. For teams looking to strengthen these practices across deployment, automation, monitoring, and production operations, GeekyAnts’ DevOps consulting services provide support across the software delivery lifecycle.