

Key Takeaways
- In-house hiring builds long-term AI capability but commits the company to recruitment, salaries, and retention.
- AI staff augmentation adds individual specialists while the internal team retains delivery management and day-to-day direction.
- A dedicated AI product pod brings multiple roles together around a defined outcome, with delivery responsibilities agreed upfront.
- The lowest upfront cost may not mean the lowest total cost. Startups must weigh spending against runway and time to market; mid-sized companies should also consider management capacity, delivery risk, and long-term skill needs.
A company gets approval to build an AI feature and opens a role for a senior AI engineer.
The proposed annual salary is $200,000, which initially appears manageable.
Later on, an additional $50,000 for benefits and payroll costs, and $30,000 for recruitment and onboarding costs can go up to $280,000 before equity, tools, and internal management time.
All of a sudden the first-year cost looks quite different.
Even if these are planning-based assumptions, they show why considering salary alone is an unfavorable way to compare hiring options, as actual costs will vary by location, seniority, employer, and hiring process.
Hiring delays can push back launches, extend proof-of-concept testing, or pull engineers away from other work. So the key question is whether waiting for a hire costs more than external support, including lost time for product testing, delayed revenue, and fewer chances to learn from customers. A 2026 Gartner survey of 100 CFOs found that acquiring and developing AI and digital talent was among CFOs’ top near-term challenges, highlighting that the issue affects workforce planning as well as recruitment. In addition, LinkedIn’s 2026 research found that two-thirds of recruiters said finding qualified talent has become difficult over the previous year.
AI hiring costs are also influenced by the demand for specialized skills. An Oxford University study found that AI-specific skills commanded a 23% wage premium in the UK job market. For growing companies, this adds another consideration when deciding whether to hire permanent AI specialists, bring in external expertise, or engage a dedicated AI product team.
How Can Hiring Delays Affect AI Product Delivery and Budget?
A delayed launch can drain a startup’s runway before it proves demand, while an unfilled AI role can hold up a mid-sized team’s roadmap. External specialists can fill specific skill gaps, a dedicated pod can coordinate several roles, and in-house hiring can build lasting AI capability. The right choice depends on the cost of waiting, the work involved, and the team’s ability to manage delivery.
In this guide we’ll compare the three models across five factors such as cost, control, management effort, delivery risks, and production speed to help companies choose a team structure that fits their roadmap, budget, and internal team capacity.
Which AI Team Model Provides the Right Balance of Cost, Control, and Delivery Ownership?
There are three different ways to add AI engineering capability: hire permanent employees, add individual specialists through AI staff augmentation, or assemble a dedicated AI product pod around a defined product area.
Decision Factor | In-House AI Team | AI Staff Augmentation | Dedicated AI Product Pod |
|---|---|---|---|
Upfront Cost | High because recruitment, onboarding, benefits, and tooling sit with the company | Usually lower initial hiring and recruitment costs for the client, but fees depend on the specialist’s rate, engagement length, and onboarding requirements. | Moderate to high because a cross-functional team carries several capabilities |
Ongoing Cost | Salaries, benefits, retention, management, and specialist development remain internal | Usually tied to contracted capacity or hours used | Recurring team cost based on the agreed team structure and capacity |
Hiring Time | Can take weeks or months, especially for specialist AI roles | Can be faster, subject to specialist availability, onboarding, and access to internal systems | Team formation can happen faster than building every role internally |
Time to Productivity | Includes hiring, notice periods, onboarding, and product ramp-up | Faster when the internal team already has clear tasks and technical direction | Faster when the pod brings product, engineering, AI, QA, and delivery capabilities together |
Internal Management Effort | High. Managers own hiring, priorities, performance, retention, and delivery | Depends on the specialist’s autonomy, the scope of work, and the client’s capacity to manage delivery | Moderate. The pod may coordinate day-to-day execution and delivery across agreed workstreams, while internal leaders retain product direction, key decisions, and acceptance responsibilities. |
Day-to-Day Control | Highest. Internal leaders control priorities, processes, and staffing | High. Internal teams generally assign work directly | Shared. The customer controls product priorities while the pod manages execution within the agreed scope |
Delivery ownership | Internal leaders manage execution and delivery. | Internal leaders coordinate specialists and remain accountable for delivery. | Pod manages agreed workstreams; the customer retains product decisions and acceptance. |
Speed to Production | Depends on hiring timelines, onboarding, and internal delivery readiness | Can accelerate defined work when the existing team manages integration, testing, and release | Can accelerate coordinated delivery when the pod has the required roles, clear responsibilities, and timely client decisions |
AI Specialization | Builds AI expertise around the company’s products and systems over time, depending on its ability to recruit and retain the required skills | Adds specific AI specialists to address skill gaps or increase capacity | Combines AI expertise with complementary capabilities such as application engineering, QA, design, and delivery, depending on the agreed team composition |
Continuity | Strong if the company retains the team | Depends on specialist continuity and knowledge transfer | Designed around team continuity and retained product context |
Scalability | Slower as each new capability can require another hiring cycle | High at the individual-role level | High at the team or capability level |
Governance | Fully internal | Internal governance with external contributors | Governance responsibilities are agreed upon across the customer and delivery team |
Knowledge Retention | Knowledge can remain within the company, provided it is documented and shared | Requires deliberate documentation and handover | Product knowledge can remain with the pod, but the customer should retain key business and architectural context |
Exit Flexibility | Low. Employment and organizational commitments remain | High. Capacity can usually be reduced as needs change | Moderate to high, depending on the engagement terms and team structure |
Best Suited For | A long-term AI capability that is central to the company’s operating model | A defined skill gap, short-term capacity need, or specialist requirement | An evolving AI product or roadmap that needs several disciplines working together |
Choosing a team model also involves deciding how much delivery coordination should remain internal. Explore the GeekyAnts Dedicated Team Engagement Model to understand how a dedicated team can be structured around product priorities and delivery requirements.
What is the difference between control and delivery ownership?
The in-house team gives companies direct control and responsibility for delivery. Staff augmentation adds specialists while internal leaders continue coordinating their work. A dedicated AI product pod can take on more execution responsibilities while the customer retains product priorities and business decisions.
Adding developers will not fix delivery bottlenecks if internal leaders lack capacity to define requirements, review architecture, and resolve dependencies. The right model depends on whether the company needs extra skills, more delivery capacity, or a team accountable for an agreed product workstream.
What Are You Actually Buying With Each AI Team Model?
Three models may look similar in a proposal, but they place different responsibilities on the buyer.
1. What Does In-house AI Hiring Actually Buy?
In-house hiring builds AI capability within the company as it recruits people, defines their roles, manages performance, develops their skills, and retains the product knowledge they gain. This model suits companies that expect AI to remain a core, ongoing capability and need to decide how AI specialists will work with product management, application engineering, QA, architecture, security, and the wider engineering team. If demand changes six months later, the company still has the employment commitment.
2. What Does AI Staff Augmentation Actually Buy?
AI staff augmentation adds individual specialists to the existing team. An external AI developer, ML engineer, or other specialist works within the company’s priorities, tools, processes, meetings, and technical direction, while the provider handles employment and related staffing responsibilities. This model suits companies with a specific skills gap and internal leaders who can assign work, resolve dependencies, and manage delivery.
3. What Does a Dedicated AI Product Pod Actually Buy?
A dedicated AI product pod brings together the roles needed to achieve a defined product outcome. Depending on the engagement, it may include product support, delivery leadership, AI and application engineering, QA, and governance. The pod’s responsibility for execution, delivery milestones, and acceptance criteria depends on the agreed terms and does not automatically take over the customer’s business or governance responsibilities. The customer retains product direction and business decisions, while execution responsibilities depend on the engagement.
A pod suits AI features that require coordinated work across model integration, application changes, testing, and release preparation. Adding a specialist can fill in the skills gap while a pod brings the required roles together under an agreed delivery structure.
What Does an AI Team Really Cost Over 12 Months?
The salary or hourly rate is only the starting point. The real cost of an AI team includes the time spent finding people, helping them get productive, managing their work, fixing coordination problems, and keeping delivery on track.
When comparing AI teams, we look beyond the monthly cost to what the business can deliver with the required investment. Hiring delays, management time, and specialists waiting for decisions all affect the return. For a growing company, a delayed launch can also mean lost revenue or a missed market opportunity. Those costs belong in the decision from day one.
 Kunal KumarChief Revenue Officer
The U.S. Bureau of Labor Statistics reported a mean annual wage of $148,100 for software developers. The BLS figure is a separate national benchmark for software developers and should not be treated as the salary for the senior AI engineer used in this illustrative cost model.
What Costs Should Each AI Delivery Model Account For?
Cost Factor | In-House AI Team | AI Staff Augmentation | Dedicated AI Product Pod |
|---|---|---|---|
Recruitment | Hiring fees, recruiter time, and months spent filling specialist roles | Usually handled by the provider | Usually handled by the provider |
Compensation | Salaries, payroll taxes, benefits, and possible equity | Hourly or monthly provider fees | Monthly fee for the agreed team and scope |
Onboarding | Internal training access setup and time to learn the product | Product, codebase, and process onboarding | Product onboarding across the team |
Management | Internal engineering and people management | Internal product and engineering management remain essential | Delivery coordination may be included; the client retains product direction. |
Continuity | Retention, replacement hiring, and knowledge transfer | Re-onboarding when specialists change | Team continuity can reduce repeated onboarding, subject to the engagement terms |
Hidden Costs | Vacancies, retention, replacement hiring, unused capacity, and specialist gaps | Coordination, fragmented knowledge, and vendor transitions | Higher monthly commitment and the risk of paying for capacity the roadmap does not use |
What Are the Illustrative 12-Month Budgets for Different AI Team Setups?
The following table illustrates 12-month costs under three different capacity assumptions, including one in-house developer, 160 hours per month of staff augmentation, and a four-person dedicated pod. These options do not provide equivalent capacity, so the figures should be used for initial budgeting instead of a like-for-like price comparison.
Cost Item | In-House Hire | Staff Augmentation | Dedicated AI Pod |
|---|---|---|---|
Base assumption | 1 developer at $148,100/year | 160 hours/month at $120/hour | 4-person pod at $35,000/month |
Annual salary or service fees | $148,100 | $230,400 | $420,000 |
Benefits and payroll allowance | $37,025 (assumed 25%) | Included in assumed rate | Included in assumed fee |
Recruitment allowance | $29,620 (assumed 20% of salary) | $0 direct recruiting fee assumed | $0 direct recruiting fee assumed |
Onboarding and internal management allowance | $20,000 | $31,000 | $20,600 |
Illustrative 12-month total | $234,745 | $261,400 | $440,600 |
The dedicated pod has the highest total cost in this example, but it also includes a broader team than either individual-capacity option.
Note: These figures are illustrative planning estimates, not a like-for-like comparison of delivery capacity. Benefits, recruitment, onboarding, and management costs are assumptions; provider rates and fees also vary by engagement. Replace these inputs with current quotes and company-specific estimates before making a budget decision.
Which Hidden Costs Can Change the Decision?
Choosing the right model involves weighing direct costs against the cost of delivery delays, unused capacity, and missed market opportunities. Compare the 12-month investment with the work each model can deliver, the internal effort it requires, and the cost of getting the product to market later than planned.
Which AI Delivery Team Model Fits Your Growth Stage, Roadmap, and Management Capacity?
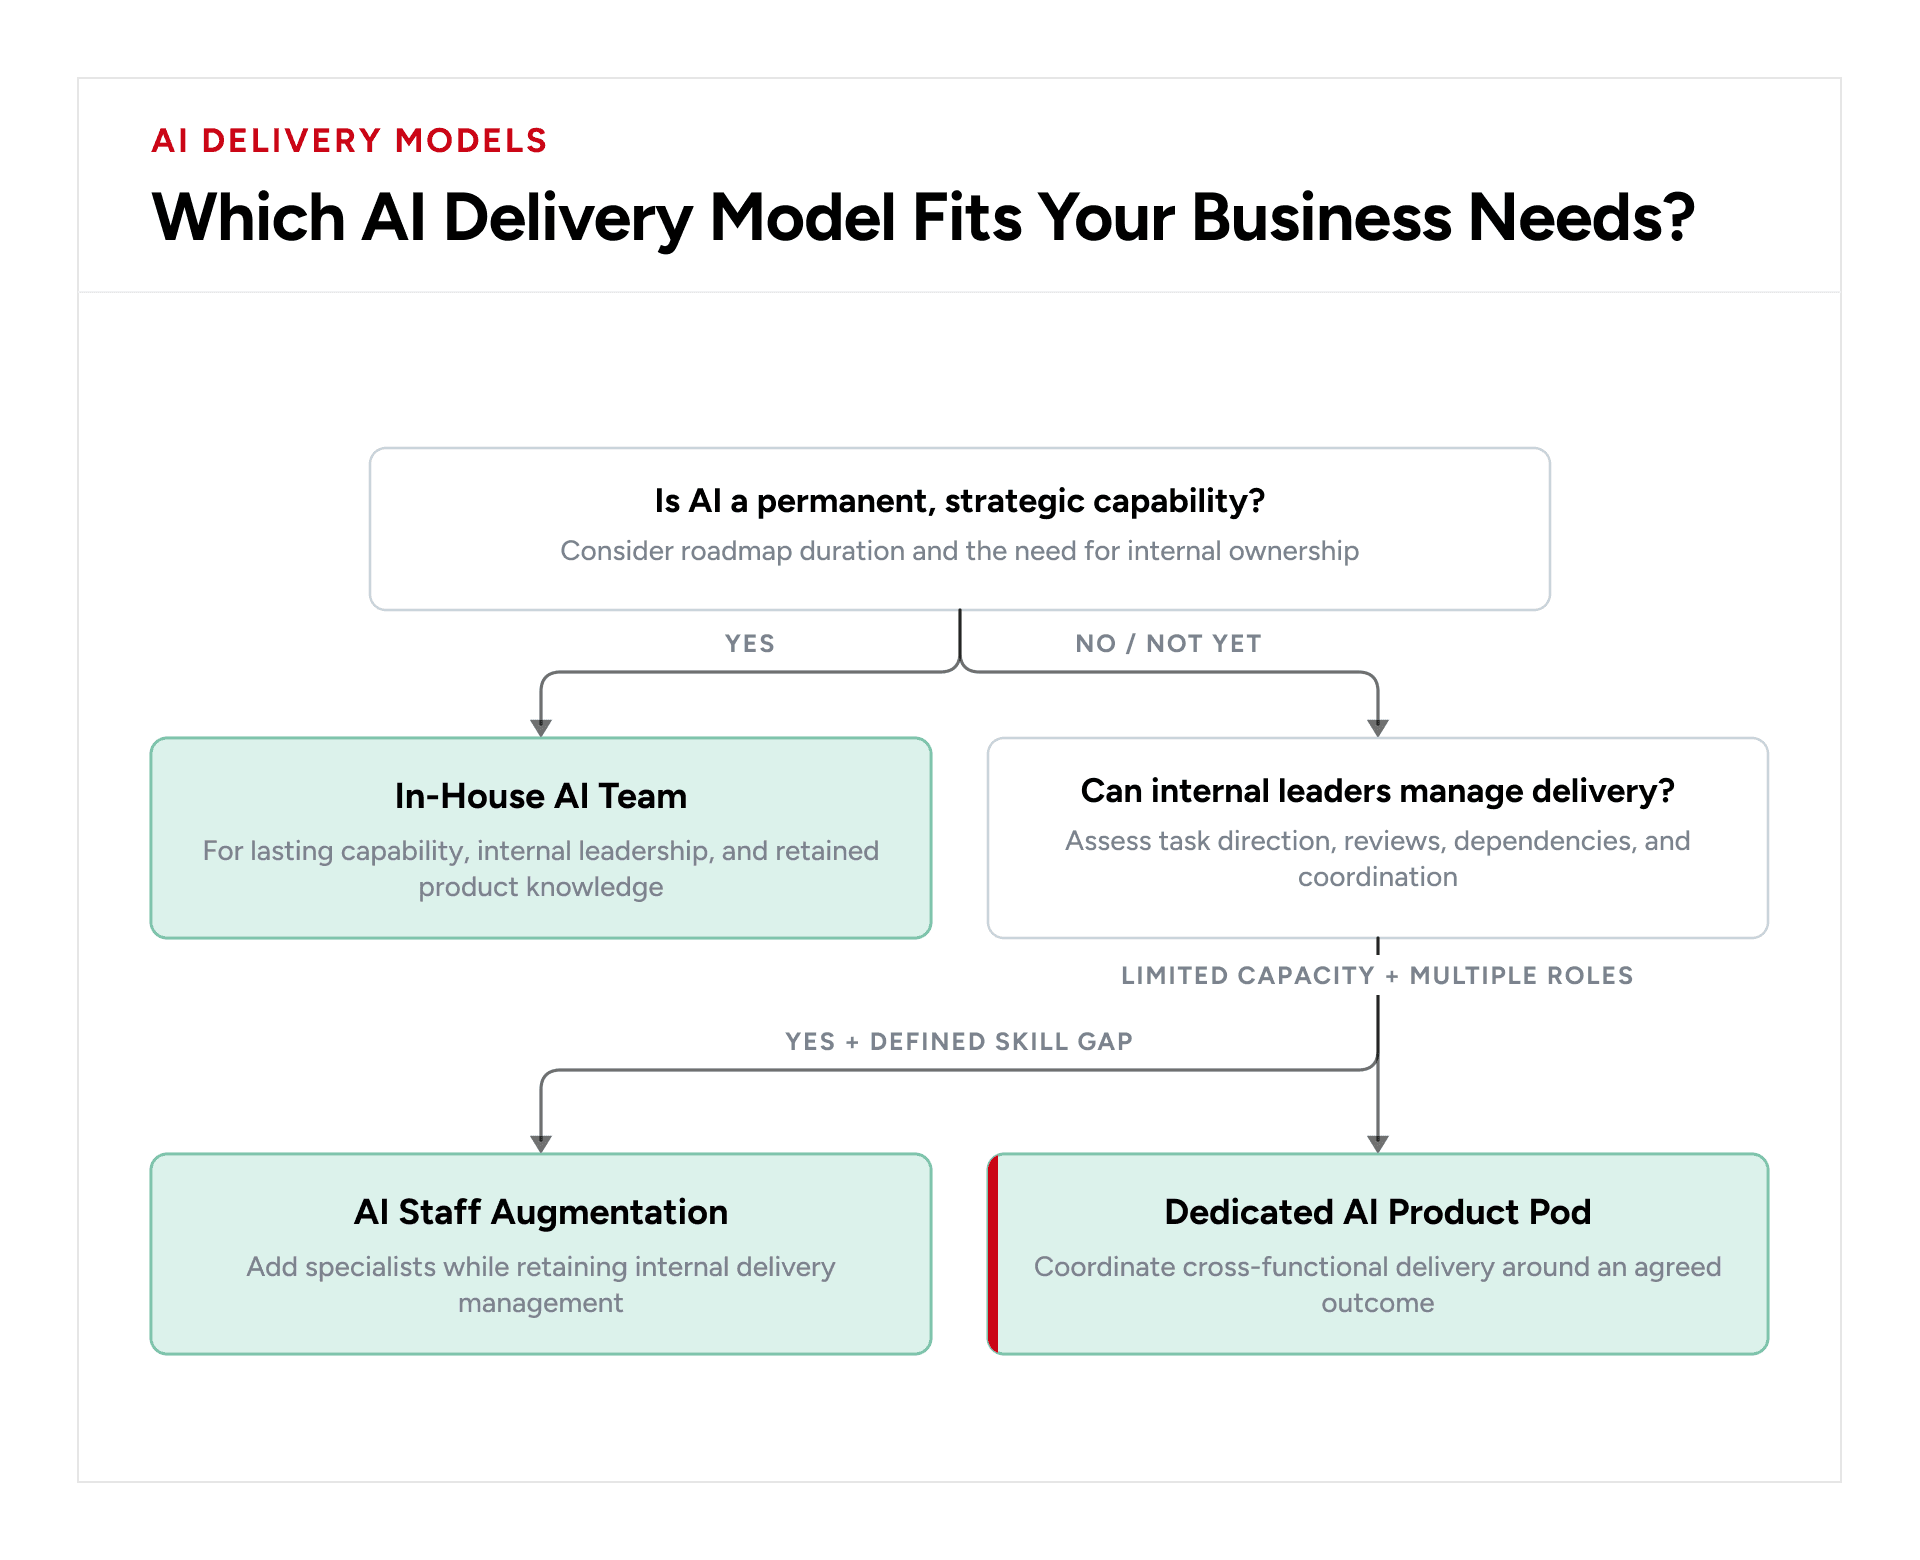
The right AI delivery model depends on what the company needs to prove, how quickly it must ship, and who has to manage the work.
Startups are still trying to answer the biggest question: whether customers will actually pay for an AI feature that has different requirements from a funded company preparing for launch. Meanwhile, mid-sized SaaS businesses have a different juggling act of adding AI to an established product without pulling their engineering team away from the roadmap that is already in progress.
When a buyer says the team needs more developers, we want to understand what factor is holding back the delivery process. If specialists are waiting for decisions, priorities keep shifting, or nobody coordinated work across roles, adding people may only increase the management load. The key question is whether the business needs more engineering capacity or clearer ownership of delivery.
Kunal KumarChief Revenue OfficerWhich AI Delivery Model Fits The Company’s Current Stage?
1. Testing an AI idea
Use AI staff augmentation to test a model or build a prototype if the existing team can manage the work. Consider a pod if the project needs several roles working together.
2. Accelerating after funding
Staff augmentation can fill skill gaps, while a pod can coordinate delivery against launch milestones. In-house hiring suits longer-term needs.
3. Launching a new AI product
A pod can bring product, AI engineering, development, and QA together. Hire in-house when these skills need to remain core capabilities.
4. Modernizing an existing SaaS product
Use staff augmentation for specific technical gaps or a pod for broader changes across architecture, AI integration, and testing. Keep product and architecture decisions clear.
5. Scaling after validation
Hire internally to build lasting AI capability, use staff augmentation to cover temporary gaps, or choose a pod to coordinate work across disciplines.
The right choice depends on the work, the expertise already available, and how much delivery management the internal team can take on.
How much management capacity does the company have?
This question should come before comparing rates. Staff augmentation works best when a product manager, engineering manager, or technical lead has to assign work, answer questions, review code, and resolve dependencies.
Before adding people, identify what is slowing delivery. If several disciplines need to work together and internal leadership cannot manage every handoff, a pod may be the better fit.
How Can You Choose the Right Model for Your Roadmap?
Work through these questions in order as they distinguish a need for individual capacity from a need for permanent capability or coordinated delivery.
Decision Question | In-House Hiring | AI Staff Augmentation | Dedicated AI Product Pod |
|---|---|---|---|
How long will the capability be needed? | Long-term, core product capability | Temporary or specific skill gaps | Ongoing product work with coordinated roles |
What kind of work needs to be done? | Continuing responsibilities the company wants to own | Defined tasks led by the internal team | Cross-functional work spanning multiple disciplines |
Who will manage the work? | Internal product and engineering leaders | The internal team directs individual contributors | External team coordinates delivery; internal leaders set priorities |
How quickly must the next milestone be reached? | Allow time for recruitment and onboarding | Confirm specialist availability and onboarding time | Confirm team availability and time needed to understand the product |
How predictable is the budget? | Ongoing salary and employment costs | Flexible capacity, depending on contract terms | Typically a defined recurring team cost |
How likely is the roadmap to change? | Best suited to sustained internal responsibilities | Fits clearly scoped tasks and skill gaps | Can support evolving work across multiple disciplines |
Where should execution ownership exist? | Within the company | With the internal team managing augmented contributors | With the pod for agreed delivery responsibilities, while the company retains product direction |
When is Each AI Team Model the Wrong Fit?
- In-house Hiring: When the workload is short-term, the required skills change after experimentation, or the company cannot support the ongoing employment costs.
- Staff Augmentation: When no leader has time to assign work, review results, and manage dependencies.
- AI Product Pod: When the work is a small, well-defined task that the internal team can manage.
Which Model Best Matches the Company’s Current Conditions?
Use this scorecard to identify which model deserves closer evaluation. Choose the answer that best describes the company’s situation today, rather than the team it hopes to have in six months.
Which AI Delivery Model Fits Your Current Needs? |
|---|
1. What do you need most right now? |
2. How much delivery management can your internal team provide? |
3. How long will you need this capability? |
4. How clearly defined is the work? |
5. What is the main delivery constraint? |
6. What kind of ownership should the company build? |
7. What is the most realistic operating model for the next 12 months? |
How to interpret your answers |
Who Owns Delivery Risk Across In-House AI Teams, Staff Augmentation, and Dedicated Pods?
Every AI delivery model carries risk, the difference is who has to deal with it when something breaks, a specialist leaves, or a release misses its deadline.
An external team can build a product, but the company still needs to understand why key decisions were made and how the system fits the business. Product context, architecture knowledge, and decision-making should not sit with a single team or individual. Keeping that knowledge accessible makes future changes easier, whether the company expands its team, changes partners, or brings more work in-house.
 Kumar PratikFounder & CEO
How Does Delivery Risk Differ Across the Three Models?
Delivery risk differs across the three models in the following ways.
Risk factor | In-house | Staff augmentation | Dedicated AI product pod |
|---|---|---|---|
Delivery ownership | Internal leaders typically manage execution and delivery accountability. | The client typically directs day-to-day work; responsibility for delivery depends on the engagement terms. | The pod may manage agreed workstreams; the client typically retains product decisions and acceptance authority. |
Hiring failure | The company bears recruitment costs and the impact of an unfilled role. | The provider may source a replacement, subject to availability and contract terms; delays can still affect delivery. | The provider may be responsible for assembling the agreed team, subject to availability and replacement terms. |
Turnover and replacement | The company manages replacement hiring and knowledge transfer. | Replacement and handover responsibilities depend on the provider agreement. | The agreement should specify team continuity, replacement timelines, and handover responsibilities. |
Continuity and knowledge | Knowledge can remain in-house when documentation and handovers are maintained. | Knowledge transfer depends on documentation, access, and agreed handover practices. | Continuity depends on team stability, documentation, and the agreed transition process. |
Architecture | Internal technical leaders typically own architecture decisions. | The client generally retains architectural accountability unless responsibilities are explicitly delegated. | The pod may implement agreed architecture; ownership of wider architectural decisions should be defined upfront. |
Security and governance | The company establishes and enforces its security and governance requirements. | The client generally retains governance responsibility, while the provider must meet agreed security obligations. | Responsibilities are shared according to the agreement; the client typically retains business-level governance and approval of key controls. |
Quality assurance | The internal team defines testing and release criteria and manages QA. | The client typically integrates specialists into its QA process unless testing responsibilities are separately agreed. | The pod may perform agreed testing; acceptance criteria and release authority should be defined upfront. |
Deadline slippage | The company manages internal dependencies and delivery delays. | Delays may result from specialist availability, client dependencies, or coordination; escalation responsibilities should be agreed. | The pod may manage delivery against agreed milestones, while both parties address dependencies and blockers within their control. |
Vendor dependency | Dependency may arise around key employees, systems, or specialist knowledge. | Dependency may concentrate around an external specialist; documentation and handover reduce transition risk. | Dependency may arise around the provider’s team or processes; documentation, access, and exit planning help reduce it. |
IP and knowledge retention | The company should maintain appropriate access to code, documentation, and internal knowledge. | IP rights and work-product access should be defined in the contract, alongside documentation and handover expectations. | The agreement should specify IP rights, repository and system access, documentation, and transition obligations. |
Scaling | Scaling depends on recruitment, retention, and internal management capacity. | Scaling depends on specialist availability, rates, and the client’s ability to coordinate additional people. | Scaling depends on provider capacity, team composition, fees, onboarding, and the agreed scope. |
Responsibilities depend on the contract, agreed scope, dependencies, acceptance criteria, security obligations, and escalation arrangements. Even when a dedicated pod manages execution, the customer generally retains responsibility for business priorities and the governance decisions assigned to it.
Which AI-specific risks should the buyer check?
AI products introduce risks that a general software staffing plan can overlook.
1. Prototype-to-Production Failure
Moving beyond proof of concept requires production integration, evaluation, monitoring, and defined release responsibilities.
2. Ungoverned AI Tooling
The company should set rules for approved tools, data handling, human review, and access to production systems, regardless of which team model it chooses.
3. Dependence on One AI Specialist
Augmentation engagements need handover requirements while dedicated pods need enough overlap between team members to prevent specialist knowledge from becoming a private store of information.
4. Model and Vendor Changes
The technical team should document its model dependencies, define evaluation criteria, and decide which parts of the architecture need to remain replaceable.
What Happens When Something Goes Wrong?
- With an in-house team: With direct control, teams must have enough people and expertise to resolve the issue without leaving the work unattended.
- With Staff Augmentation: If the root cause in the model involves a missing evaluation process or an integration problem, adding another specialist will not resolve the ownership gap by itself.
- With a Dedicated AI Product Pod: The pod investigates issues, coordinates fixes, and validates changes. The client decides whether the remaining risk is acceptable and whether the product should launch.
How Can a Founder Transfer Risk Without Losing Control?
The CTO or CEO should confirm five things, such as named accountability, replacement and continuity terms, shared technical records, production acceptance criteria, and exit and transition arrangements. This delegates execution without surrendering business decisions or creating unnecessary vendor dependency.
Build and Scale AI Products with GeekyAnts’ AI Engineering and Delivery Teams
Choosing a delivery model comes down to the company's requirements and the capacity it has to manage the same. GeekyAnts brings product design, AI engineering, application development, QA, and technical leadership together to help companies move from product validation to production. With 20 years of product engineering experience since 2006 and 550+ engagements across products and enterprises, the company has worked across different stages of product development.
How Has GeekyAnts Enabled AI Product Development at Different Stages?
1. Smart Pantry - Building an AI Product from Discovery to MVP
Smart Pantry needed a personalized meal recommendation platform that interprets pantry inputs, accounts for user preferences, and improves its recommendations over time. GeekyAnts combined product development and testing to build a personalized meal recommendation MVP, resulting in 40% less time spent deciding meals, 2x daily active usage during the pilot, and 3x faster AI feature iteration. This demonstrates how several disciplines can contribute to an AI product from its early stages.
Read the Smart Pantry Case Study
2. Nexus - Adding AI Expertise to an Existing Product
Nexus needed to bring AI advancements to its business management platform’s AI roadmap without slowing its existing development work. GeekyAnts supported Nexus with RAG evaluation, intelligent SQL agents, and automated benchmarking. The work reduced manual validation cycles by 50% and improved internal testing speed by 30%. This is relevant for companies with established engineering teams that need additional AI expertise to move specific work forward.
How Can the Engagement Change as the Product Grows?
GeekyAnts offers project-based or hybrid engagements for discovery and feasibility testing, cross-functional pods for MVP development, and managed engineering pods for production readiness and scaling. Companies with established teams can use time-bound specialists to fill specific skill gaps. Our fractional engineering offering includes ‘Startup, Growth, and Scale Pod’ configurations for different levels of delivery support.
What Does GeekyAnts Manage, and What Stays with the Customer?
The customer retains control of product priorities, business goals, roadmap direction, budget, and acceptance decisions. These determine what the product needs to achieve and which trade-offs the business is willing to make.
Under a managed pod arrangement, GeekyAnts can coordinate agreed engineering execution, technical planning, code reviews, testing, and delivery progress. Both sides should agree on architecture decisions, security requirements, release approvals, staffing changes, and escalation procedures at the start of the engagement. The exact division depends on the engagement model and should be documented in the agreement.
Which AI Team Model Fits Your Budget, Control, and Roadmap?
The right AI team model depends on the work, the budget, and how much of the delivery process the company can manage. In-house hiring makes sense when AI is a long-term capability that needs internal ownership. AI staff augmentation fills a specific skills gap when the existing team can direct the work and integrate it into the product. A dedicated AI product pod suits an initiative that needs several roles working together toward a shared outcome.
Before choosing, compare the full cost of each model, including recruitment, onboarding, management time, team continuity, and the impact of delayed releases. Be clear about who makes product decisions, sets technical direction, tracks delivery milestones, maintains quality, and transfers knowledge.
Every model carries delivery risk. The aim is to choose a setup that fits the roadmap, budget, internal expertise, and level of accountability the company needs.
Ask one question before deciding: Does the next AI milestone need a specialist, a team that can coordinate delivery, or an in-house capability the company will need for years? The answer gives the company a starting point for choosing an engagement model.
Sources and Citations
- https://www.gartner.com/en/newsroom/press-releases/2026-03-23-gartner-survey-reveals-acquiring-and-developing-ai-and-digital-talent-is-cfos-top-near-term-challenge
- https://www.linkedin.com/business/talent/blog/talent-acquisition/ai-in-hiring
- https://www.ox.ac.uk/news/2025-03-04-skills-based-hiring-driving-salary-premiums-ai-sector-employers-face-talent-shortage
- https://www.bls.gov/news.release/ocwage.t01.htm