

An AI feature can pass a demonstration and fail under repeated testing. On a clinical education platform, a model missed a critical treatment error. A family-records app inferred a child's gender from speech lacking that information. An engineering assistant passed software tests while disregarding developer requirements.
GeekyAnts evaluates model tasks, application controls, and release conditions to expose such failures.
How Does GeekyAnts Set Accuracy Tests and Acceptance Criteria?
The clinical education platform contains 14 places where application code sends instructions, called prompts, to an AI model. Tasks include grading spoken responses, identifying critical errors, and extracting exam cases from PDFs. Each task has expert-labeled examples, automated checks through application code, and a measured starting score called a baseline.
Clinical evaluation check | Acceptance threshold |
|---|---|
Safety-critical fail-trigger match | 1.00 |
PDF field extraction accuracy | 0.90 |
Examination checklist accuracy | 0.80 |
Essential clinical points F1 | 0.75 |
Critical-error detection F1 | 0.75 |
F1 combines the share of expected items detected with the share of flagged items that were correct. These thresholds describe required scores; test results establish performance. Label corrections require written reasons. Each prompt change includes its revised baseline in the same code update, giving reviewers a record of the measured effect.
In the family-records app, a confidence score flags uncertain details for human review. Its 0.75 cutoff is provisional pending a planned dataset targeting 200 labeled transcripts.
The internal AI engineering assistant has 18 behavior tests: 13 for selecting an appropriate workflow skill and five for inspecting the work produced. A separate October 7, 2026 comparison reported 13 passes in 17 cases with the plugin and zero passes without it. The plugin adds workflow instructions and capabilities.
What Have AI Evaluations Revealed Across Three Projects?
Clinical Education: An Inconsistent Safety Score
A learner described giving oxygen and fluids during an allergic reaction but omitted adrenaline and stopping the responsible antibiotic. Across ten runs on the same response, the model detected missing adrenaline in ten of ten runs and the antibiotic error at a rate near one-third. The failure remains in the reference dataset; the team requires a minimum of three runs for changed results before evaluation decisions.
The review exposed faulty reference answers. Checking the airway for swelling had received credit for diagnosing anaphylaxis, a severe allergic reaction. Stopping surgery had received credit for stopping the offending drug. Reviewers corrected the labels and documented the reasons.
Family Records: Unsupported Claims and Privacy Defects
When a user said "my child Alex," the model returned "son." The speaker had supplied no evidence of gender. Validation rules require evidence from the speaker's words. A test checks that saved records come from the user-approved draft.
Review of a speech component identified two privacy risks: logs could retain encoded audio, and cached speech clips could contain family members' names. Tests caught a vendor refusal treated as speech and an account-deletion defect that could have retained voice sessions. The design restricts cached speech to fixed prompts and uses an explicit deletion step.
Engineering Assistant: Passing Code With Missed Requirements
Two simulated developers requested a loan-renewal feature. One preferred tests before code; the other began with specifications. All four runs, with and without the assistant, passed ten hidden software tests. The assistant imposed unnecessary approvals, missed a rule in an earlier specification, and dropped another requirement.
Six fixes addressed those problems. An evaluation for preserving specification rules improved from 4/5 to 5/5.
How Does GeekyAnts Check Hallucinations, Security, and Bias?
A hallucination is information that the supplied evidence fails to support. Clinical scoring outputs must follow a defined data format. Invalid responses receive one repair attempt; quoted reasons must match the learner's transcript. Non-answers pass through a simple check before scoring. Generated exam cases remain drafts until a person approves publication.
The family-records app applies seven checks to extracted data. Its security tests include fake system messages, administrator requests, and another user's identifier inside speech transcripts. This is prompt injection: instructions placed inside user content to redirect the model. The extraction component has no database access. A privacy test checks for audio in database writes, caches, logs, and temporary files. Clinical test datasets reject learner identifiers.
The engineering assistant's graders verify execution records and generated files against task requirements. Four AI reviewers examined engineering templates; engineers confirmed over 30 security findings, including a flaw involving unverified email ownership. Another evaluation exposed a way to bypass a one-time login code. Six defects arose during security fixes, prompting a second engineer to inspect the changes.
Fairness tests cover defined risks. Clinical scoring uses common case criteria, but accent-based transcription accuracy remains unmeasured. The family-records app tests English and Hindi and checks each vendor's language support before offering a language to users. The coding assistant is evaluated against different developer working styles.
How Does GeekyAnts Measure Response Time and Cost?
The clinical platform records the provider, model, tokens consumed, and response time for each call. Tokens are units of text used for model billing. Simple checks catch skipped answers before paid scoring, and background jobs build scorecards. A scoring attempt has a 120-second default timeout and a maximum of three retries for network errors or vendor request limits.
The family-records app caps each user at two active sessions, ten sessions per day, 40 turns, and ten minutes of audio per session. A recording has a two-minute or 8 MB limit. Vendor failure sends the user to a manual form. A measured cost per session is required before launch.
For the coding assistant, changes to the workflow produced these results in the same evaluation scenario:
Measure | Before | After |
|---|---|---|
Developer messages | 9 | 3 |
Approvals before coding | 6 | 1 |
Cost per scenario run | $9.46 | $2.58 |
Elapsed time | 20.8 minutes | 5.9 minutes |
Its separate automated evaluation suite has a $5 ceiling per run; one full evaluation run cost $2.73.
What Must Pass Before Production Release?
The clinical project requires a minimum of ten expert-labeled examples per prompt before production scoring. Automated checks can reveal regressions, or performance declines after changes, while clinical accuracy requires expert review. Its test data includes misleading answers and false-positive traps. The source reports no separate formal red-team exercise for the clinical project. Such an exercise simulates attacks to expose vulnerabilities.
The family-records app separates code approval from voice-feature activation. Activation requires a product decision, confirmation of recording consent, a named data-processing provider in the privacy policy, and a measured cost ceiling. For the engineering assistant, release requires passing evaluations, reviewed security findings, tests for fixes, and engineer approval.
A feature flag, a software switch controlling user access, keeps the feature disabled pending sign-off. These project-level decisions align with NIST's AI Risk Management Framework, which calls for governing, measuring, and managing AI risks.
Conclusion: Evidence Drives Production Decisions
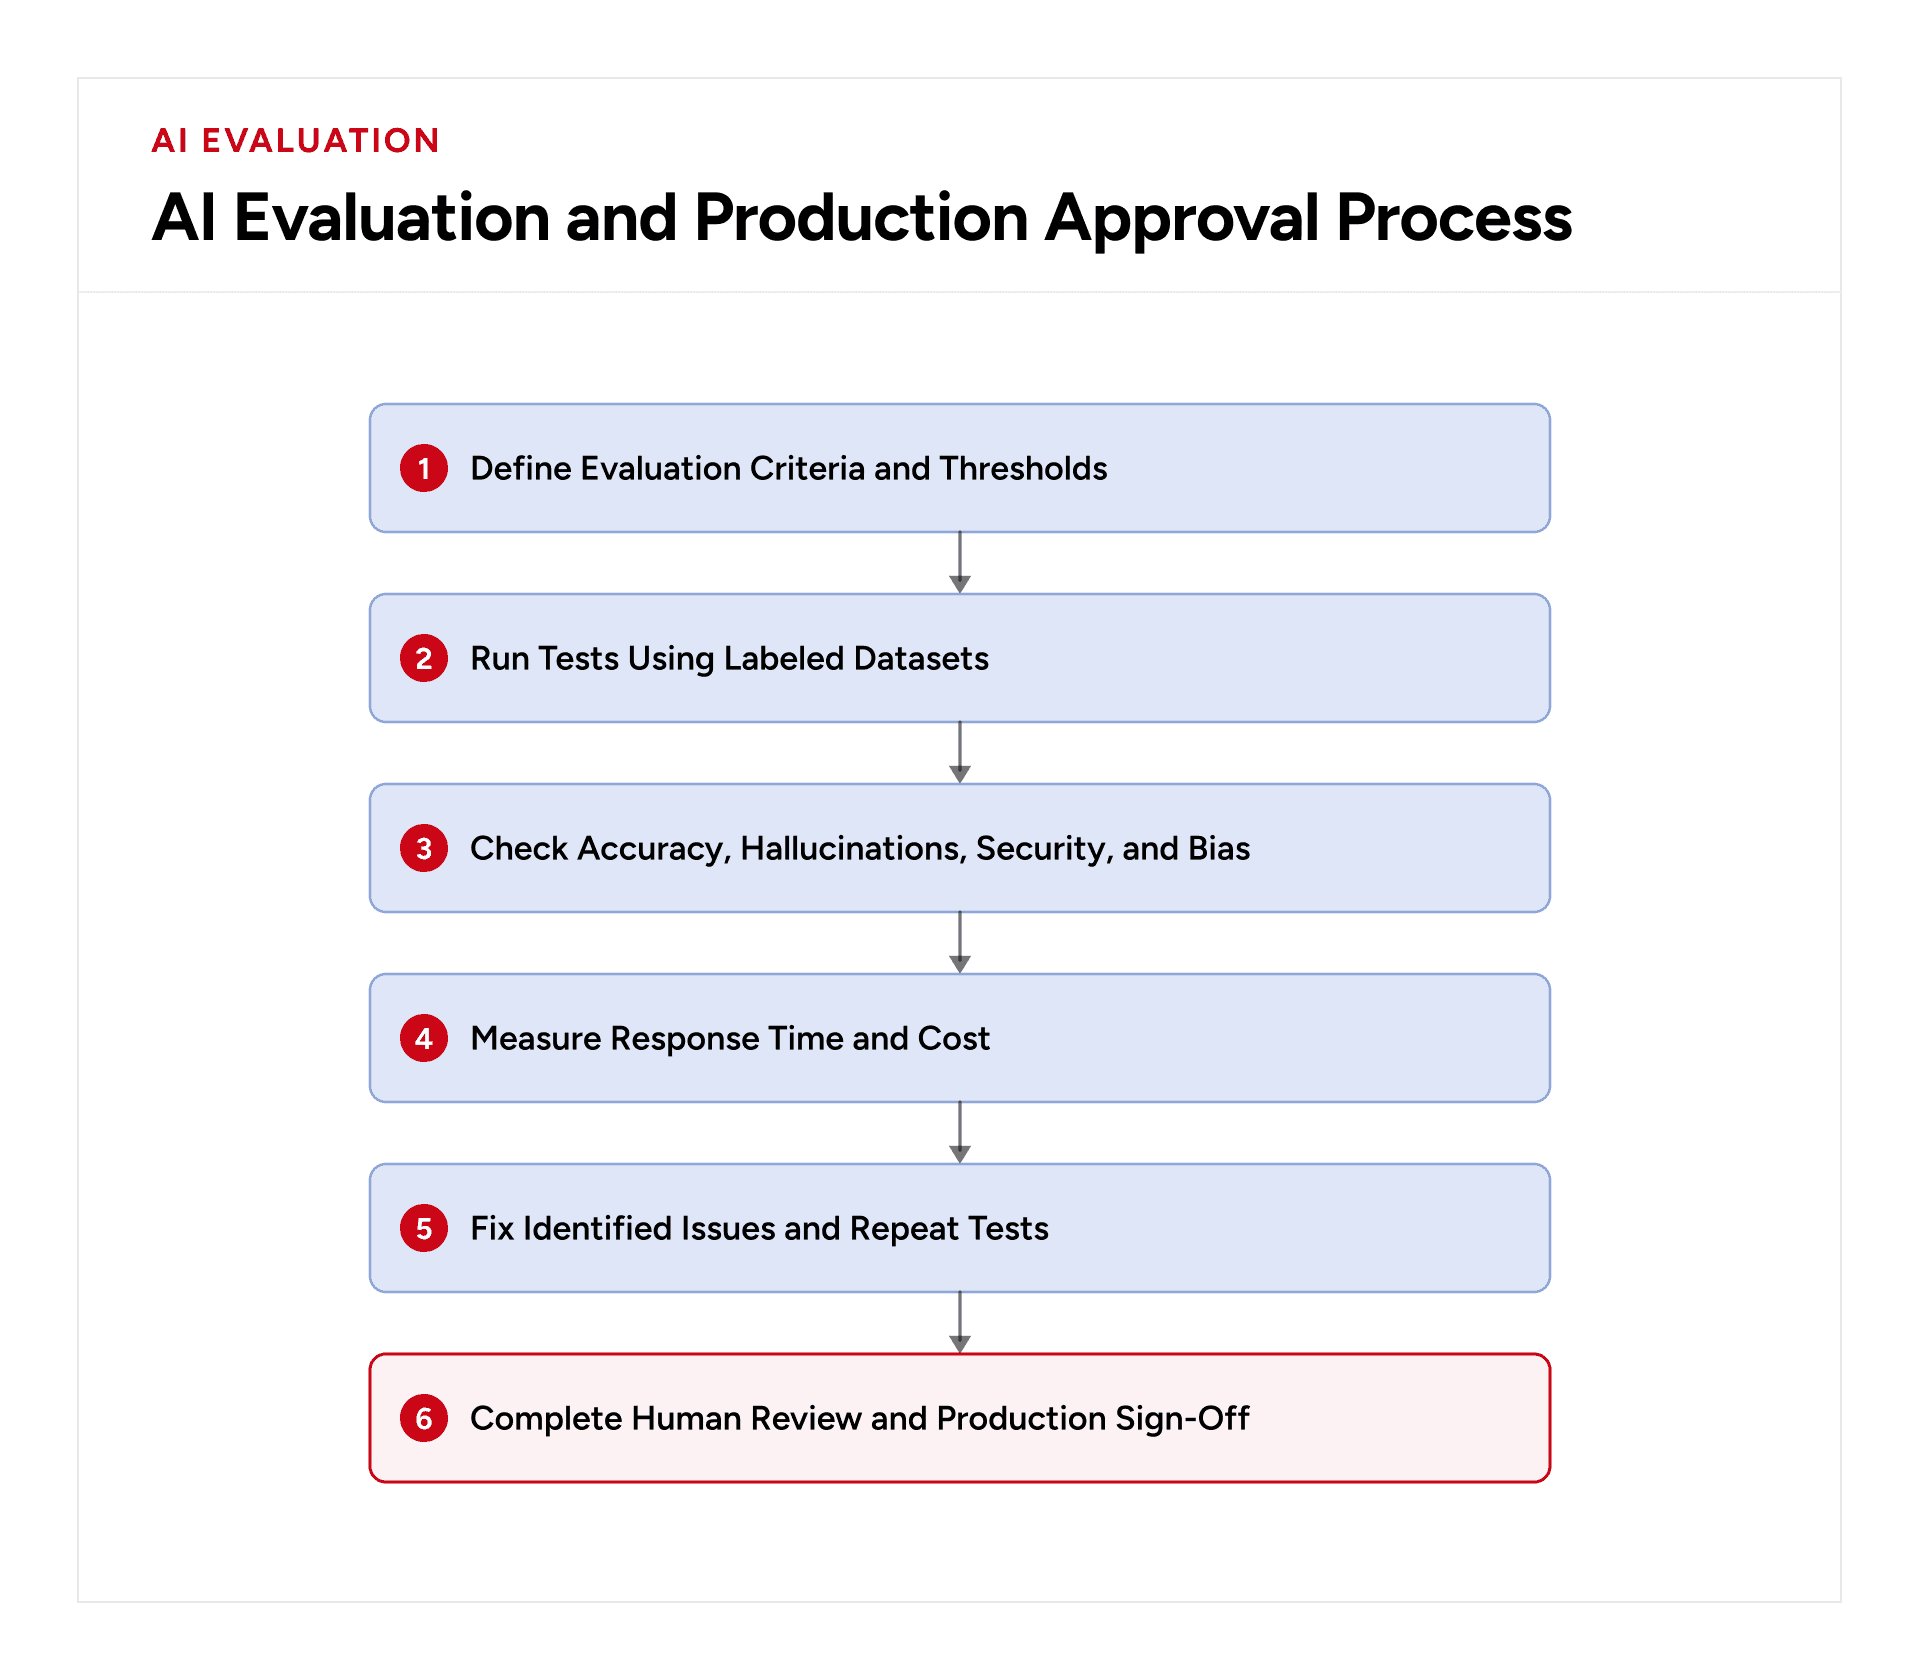
Production approval requires evidence beyond a successful demonstration. GeekyAnts uses task-specific tests, repeated runs, access restrictions, cost measurements, and human sign-off to identify risks before release. Businesses preparing an AI product can explore GeekyAnts' AI-Powered Product Engineering Services for support with development, testing, and production readiness.