Retrieval-Augmented Generation (RAG) Development Services
From enterprise RAG pipelines to domain-tuned search experiences, we build AI systems that combine retrieval precision with generative fluency to deliver faster answers, better insights, and reliable decision support.
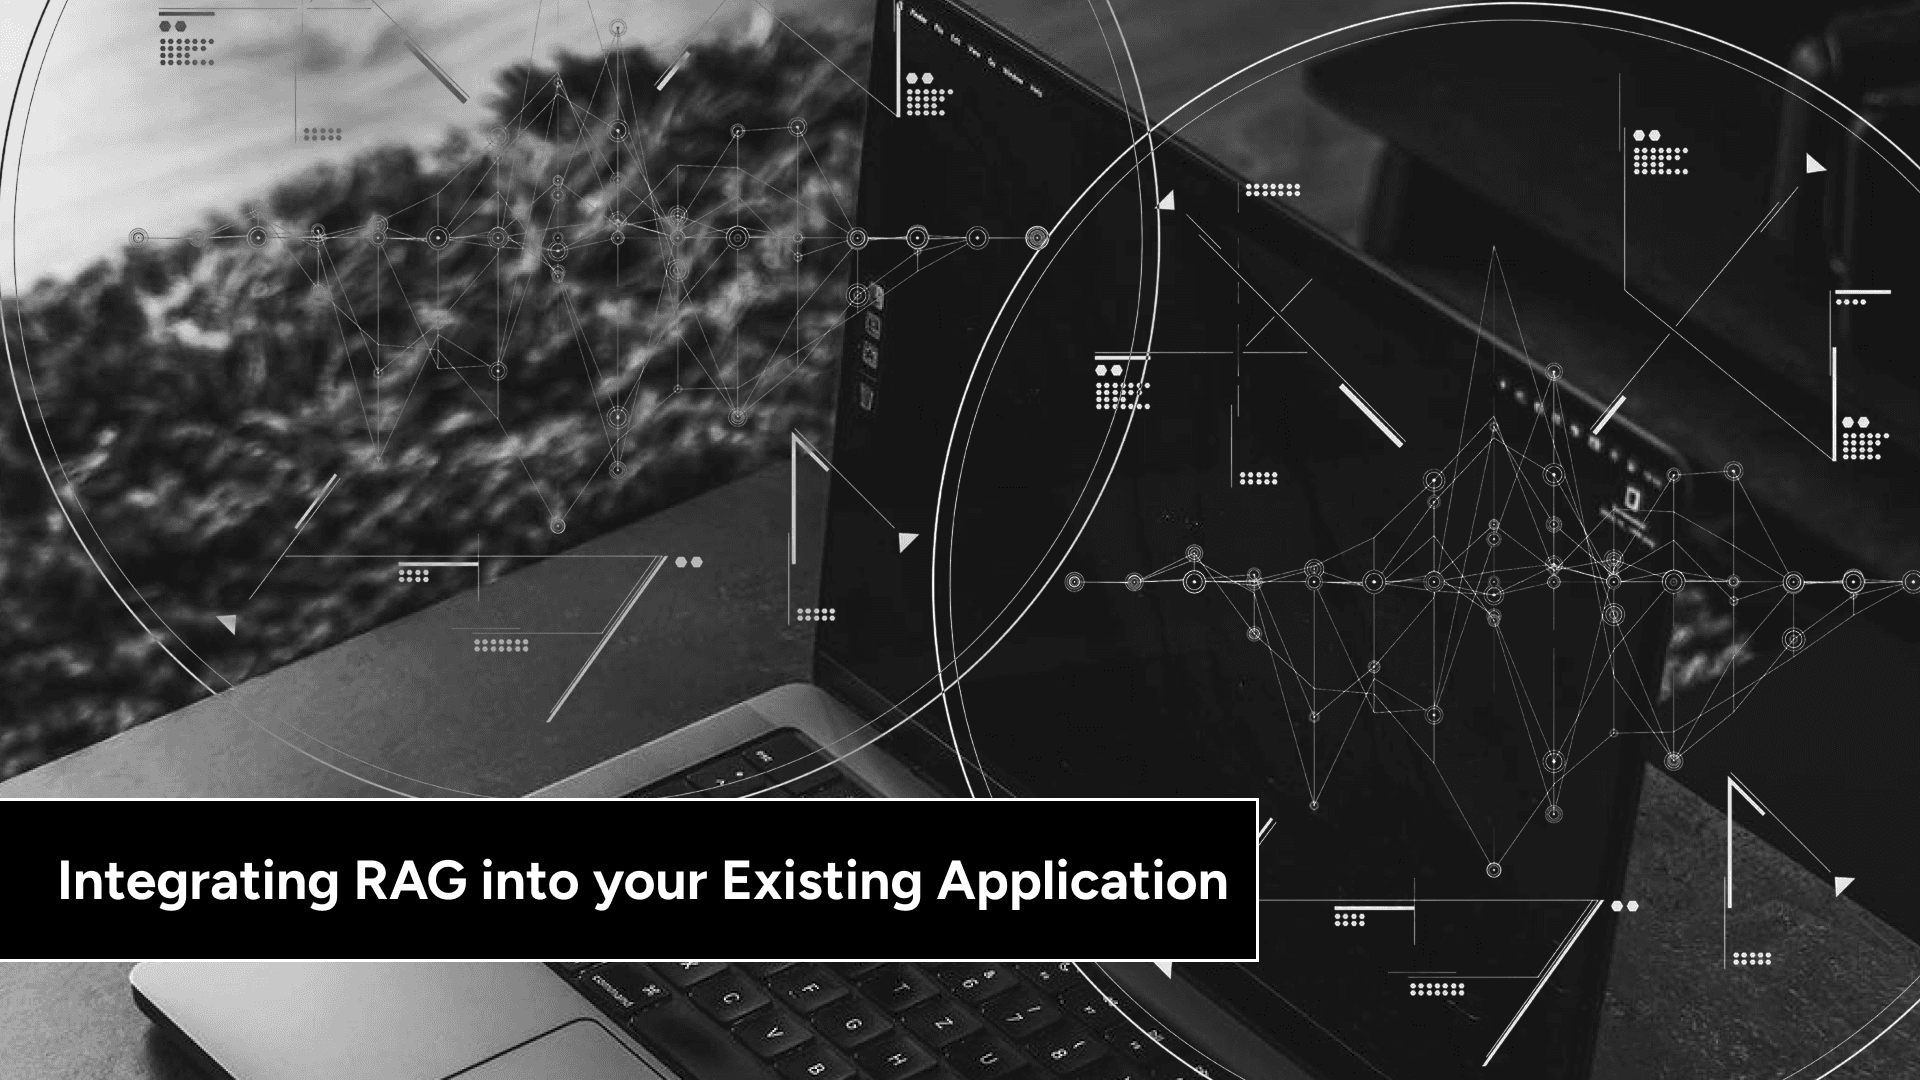
Whether you're enabling internal Q&A, building AI support tools, or automating document workflows, our custom RAG Development Services and Large Language Model (LLM) solutions enhance efficiency, surface knowledge, and accelerate informed outcomes.








Our Custom Retrieval-Augmented Generation (RAG) Services for Enterprises and Mid-scale Companies
Our enterprise RAG development services and solutions cover knowledge-source planning, retrieval workflow design, retriever and generator engineering, response validation, platform integration, and ongoing governance. GeekyAnts builds each RAG system around your data sources, user queries, security requirements, and business workflows.
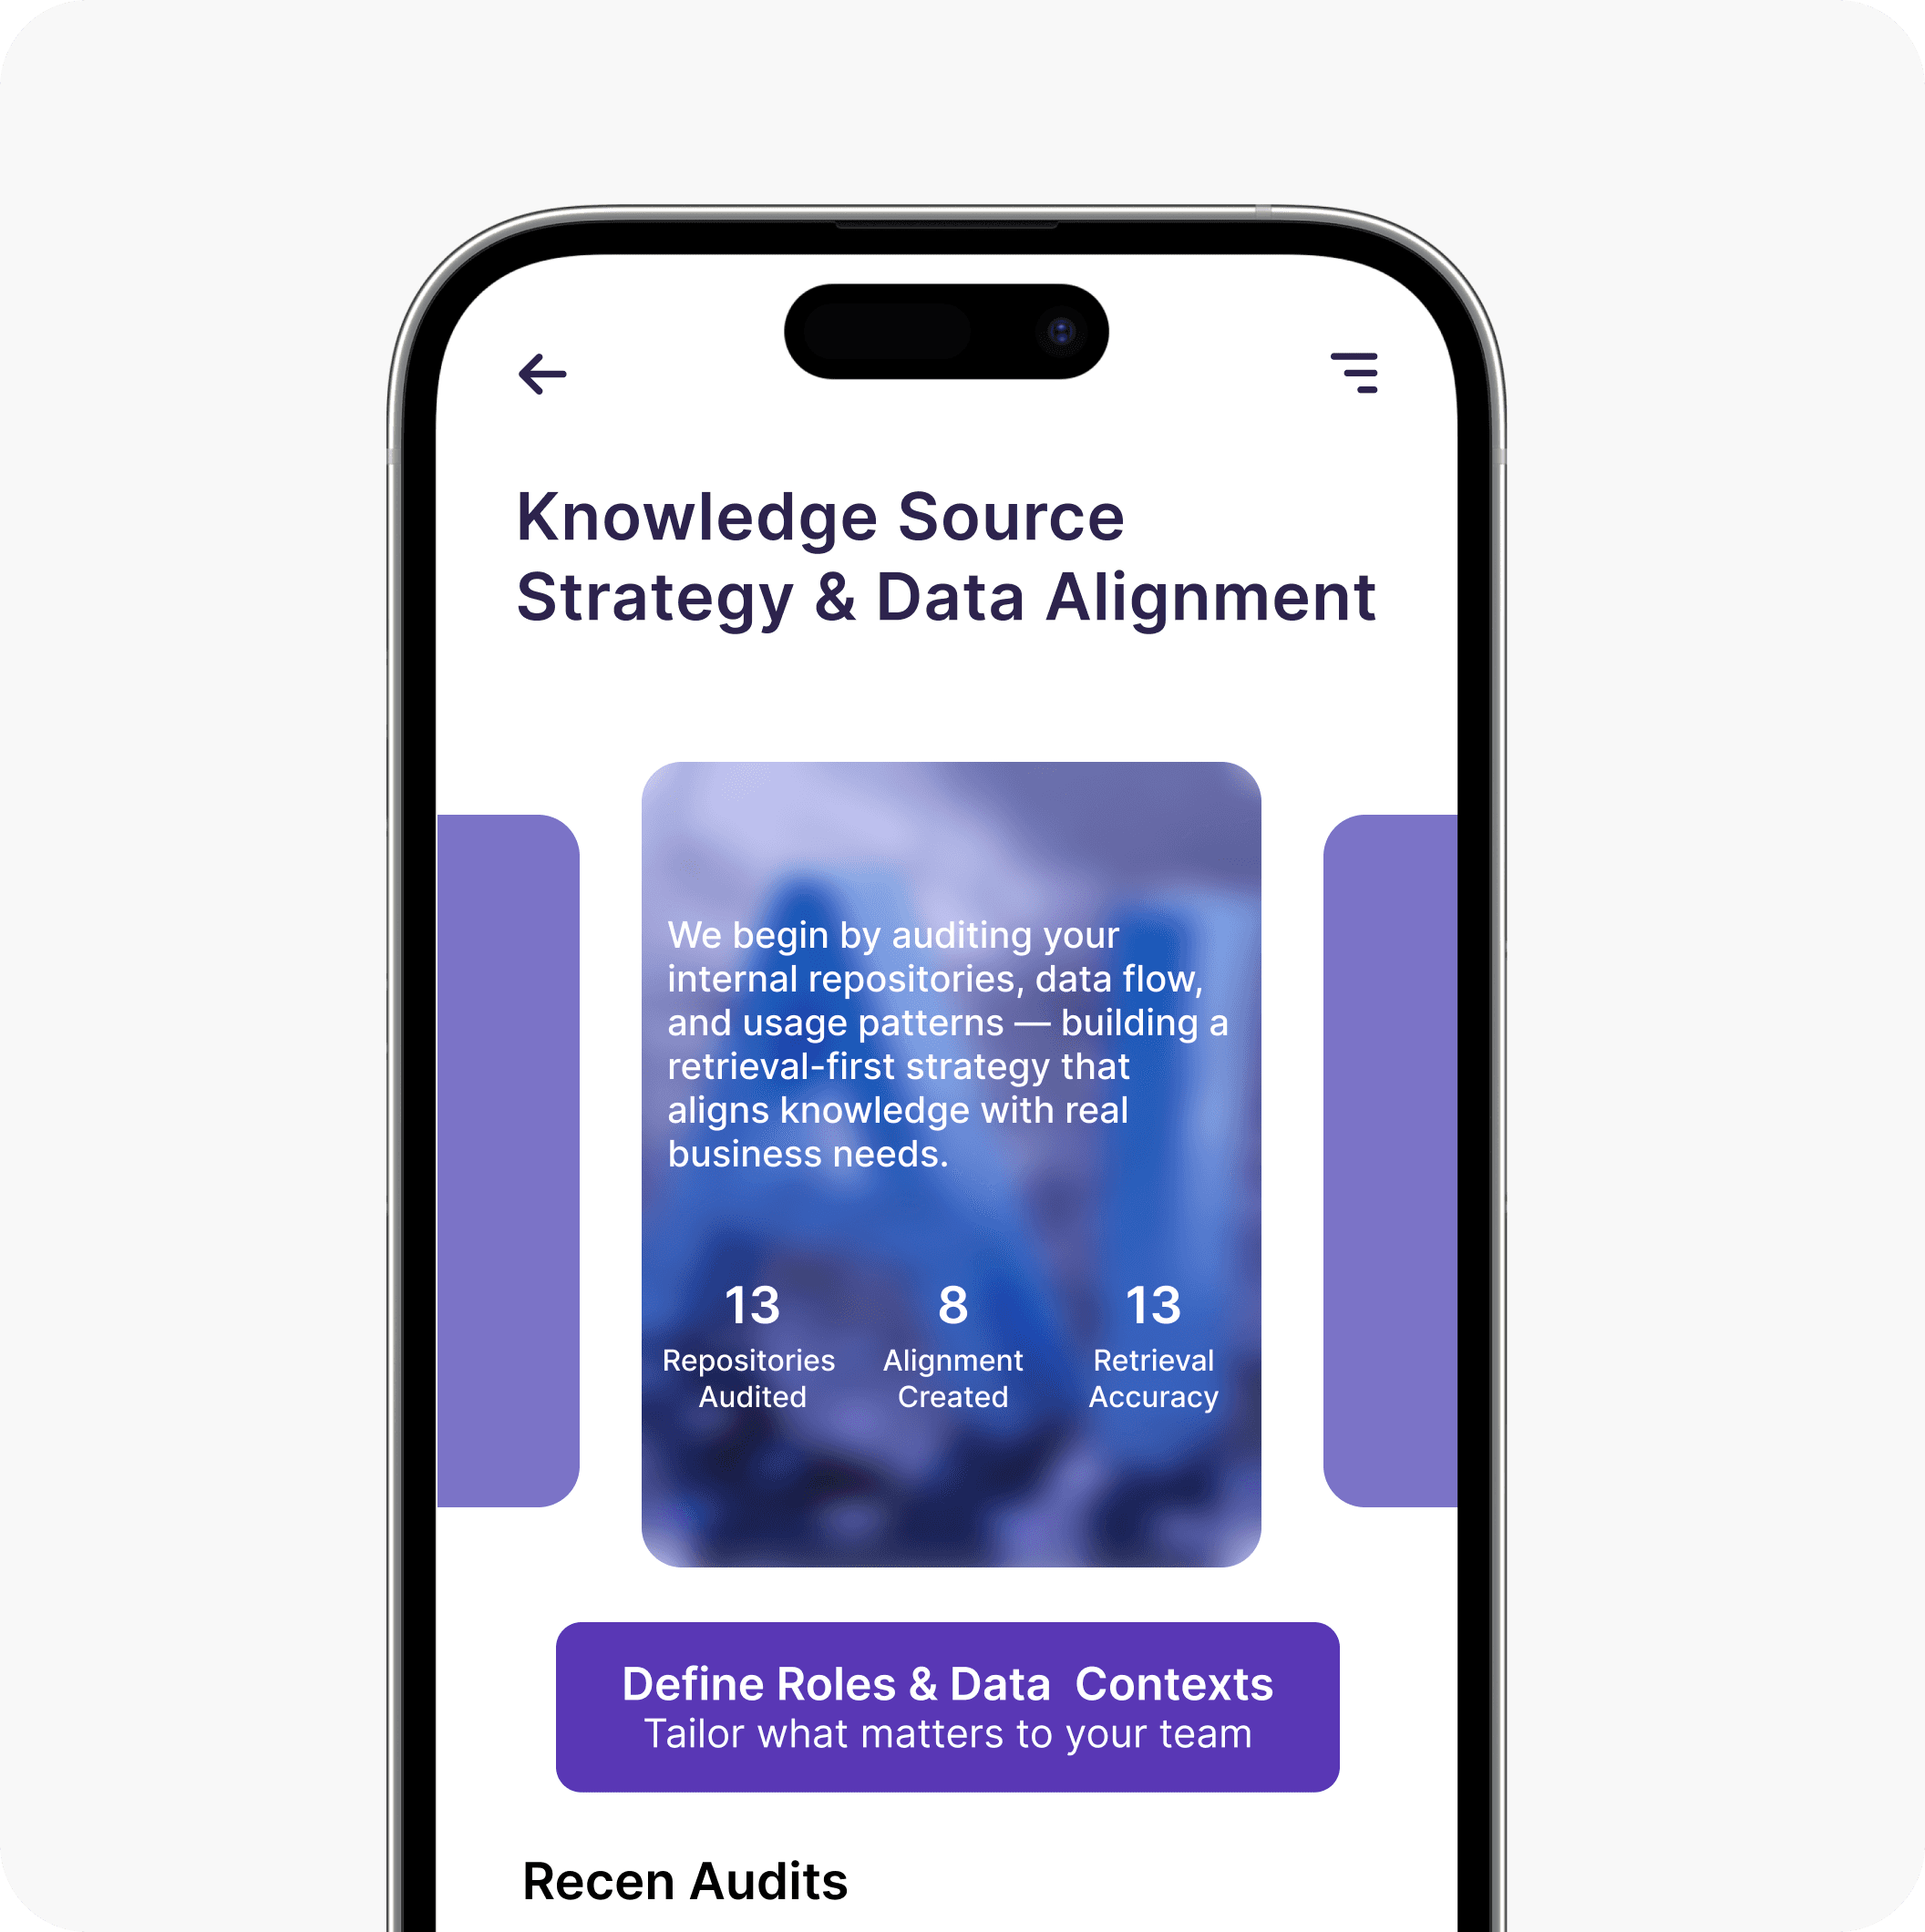
Our RAG Experts begin by auditing your internal repositories, data flow, and usage needs—defining a retrieval-first plan that aligns with functional roles and business contexts.
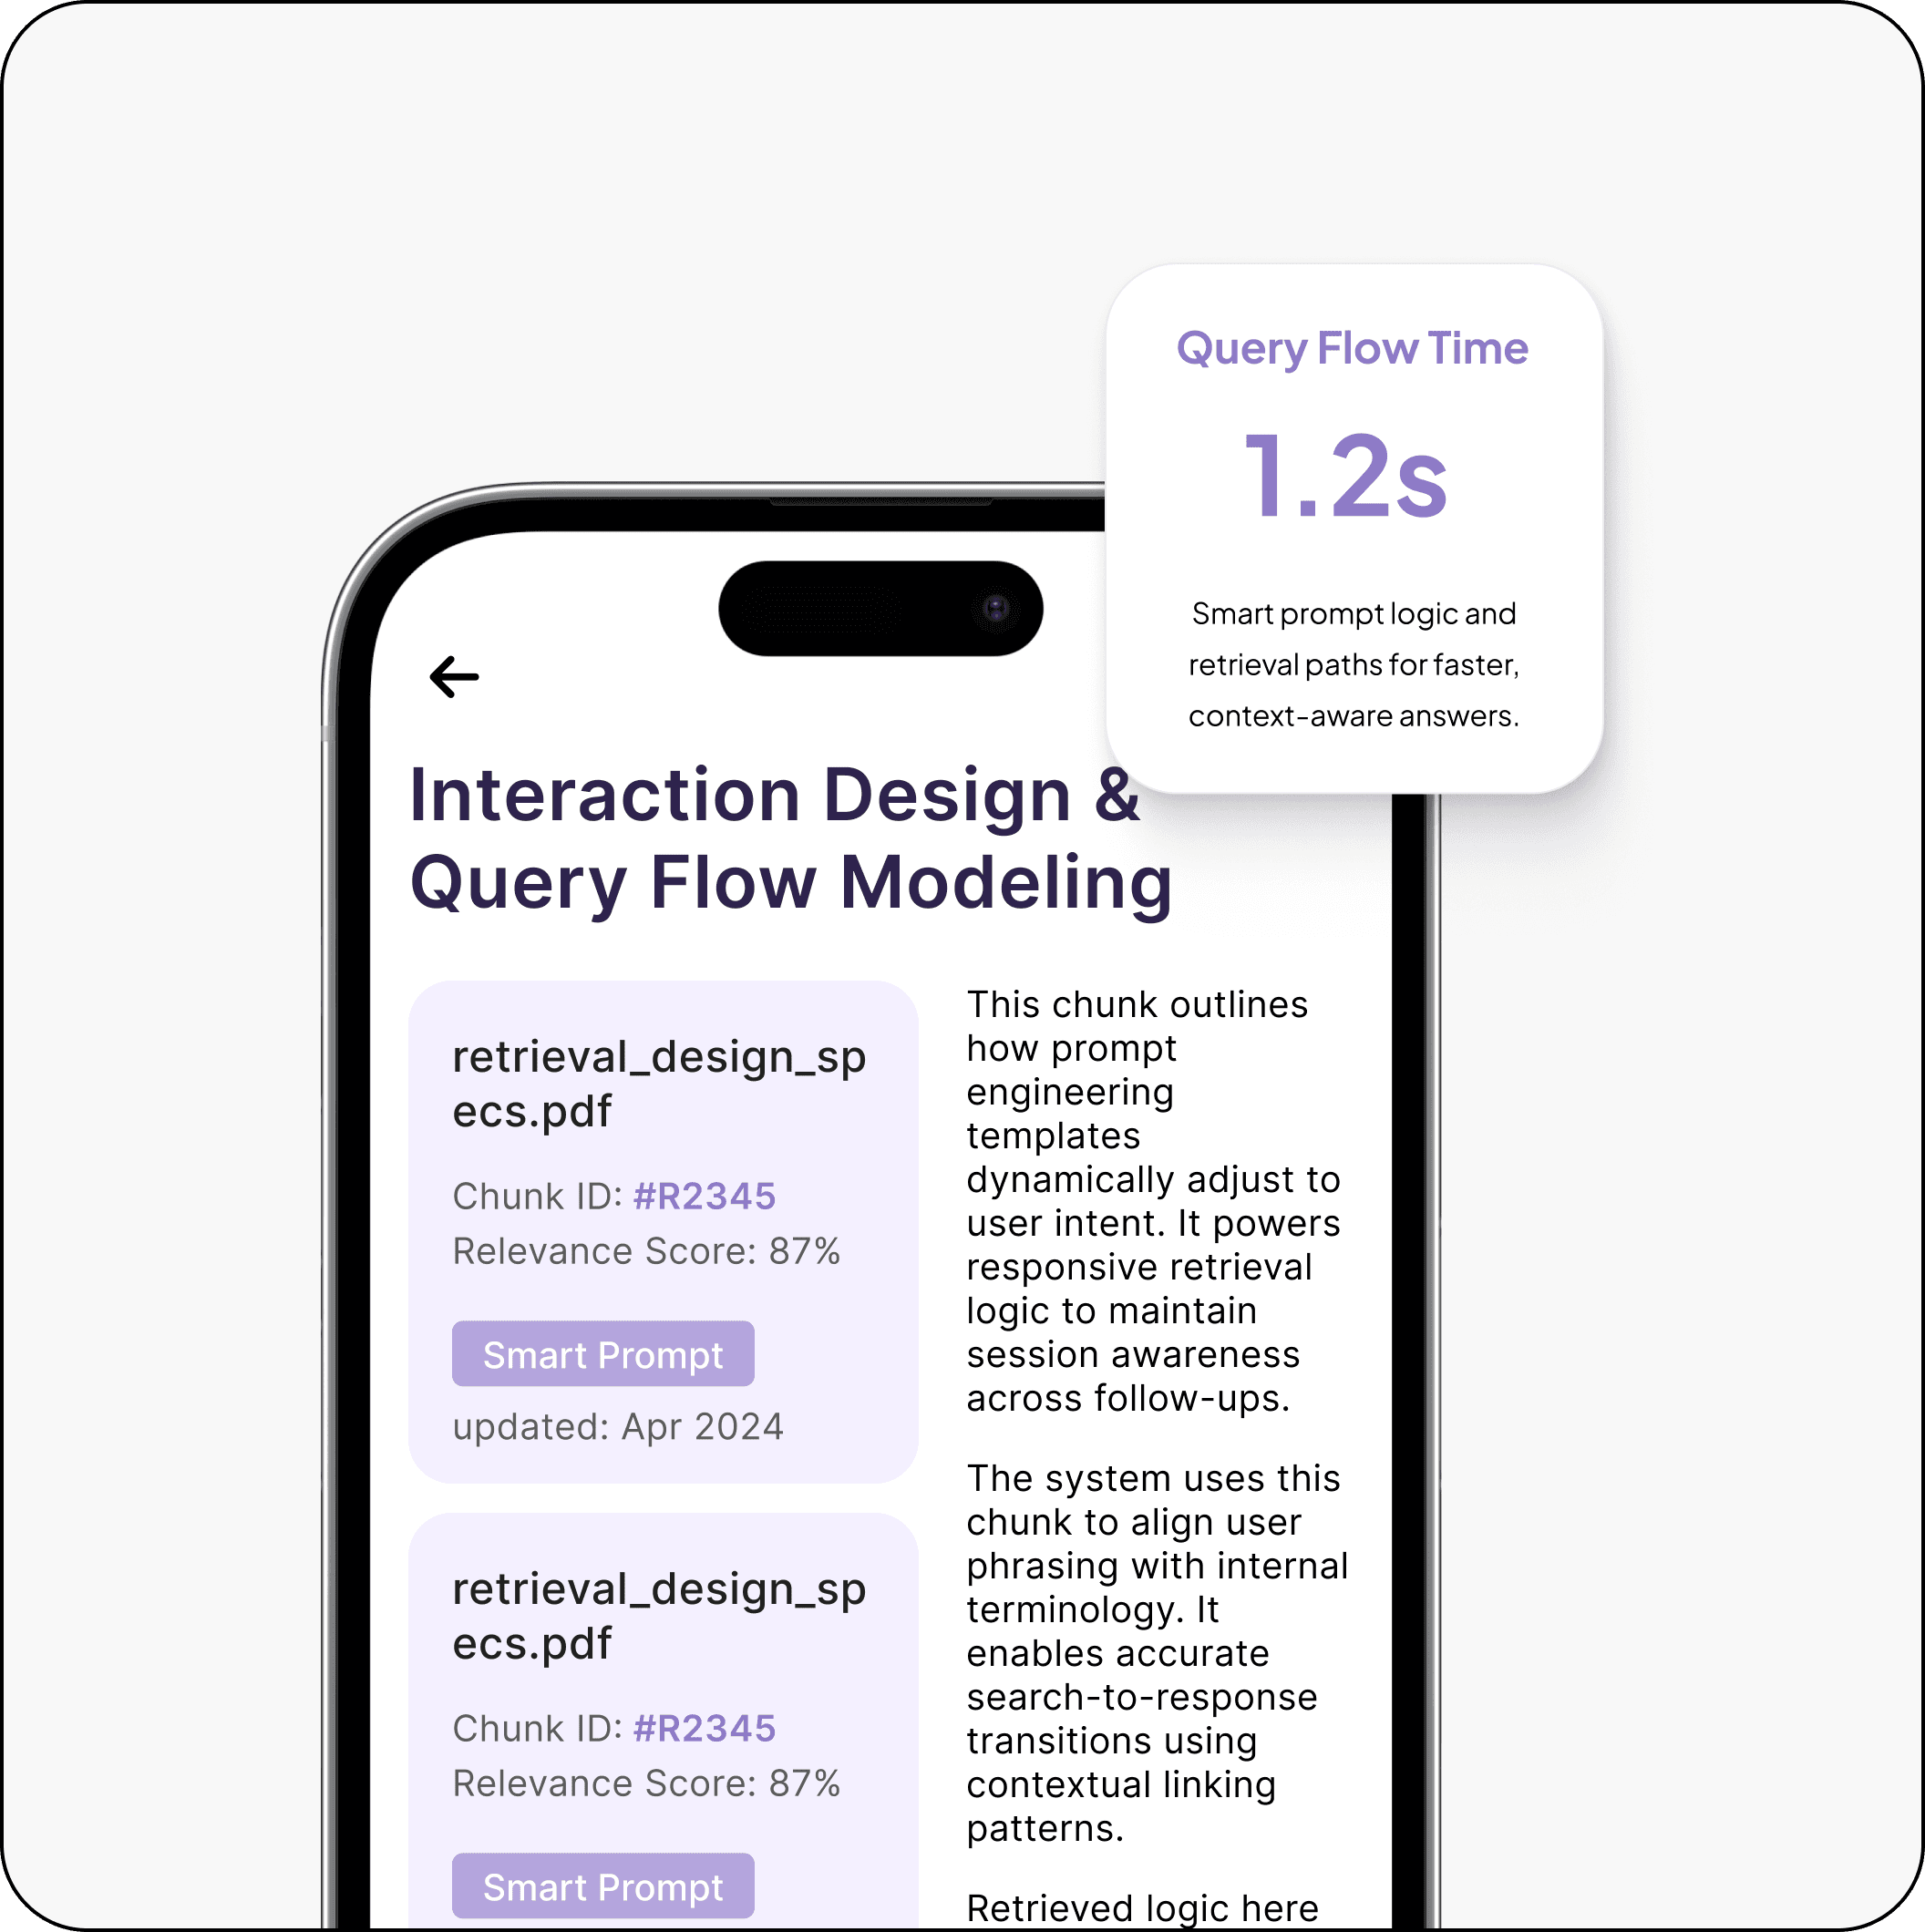
Our RAG developers construct smart retrieval workflows and prompt logic, optimizing how LLMs query, extract, and synthesize information in context-rich user sessions.
We deploy optimized retrievers and LLM readers using tuned embeddings, efficient indexes, and scalable APIs—balancing response speed and content precision.
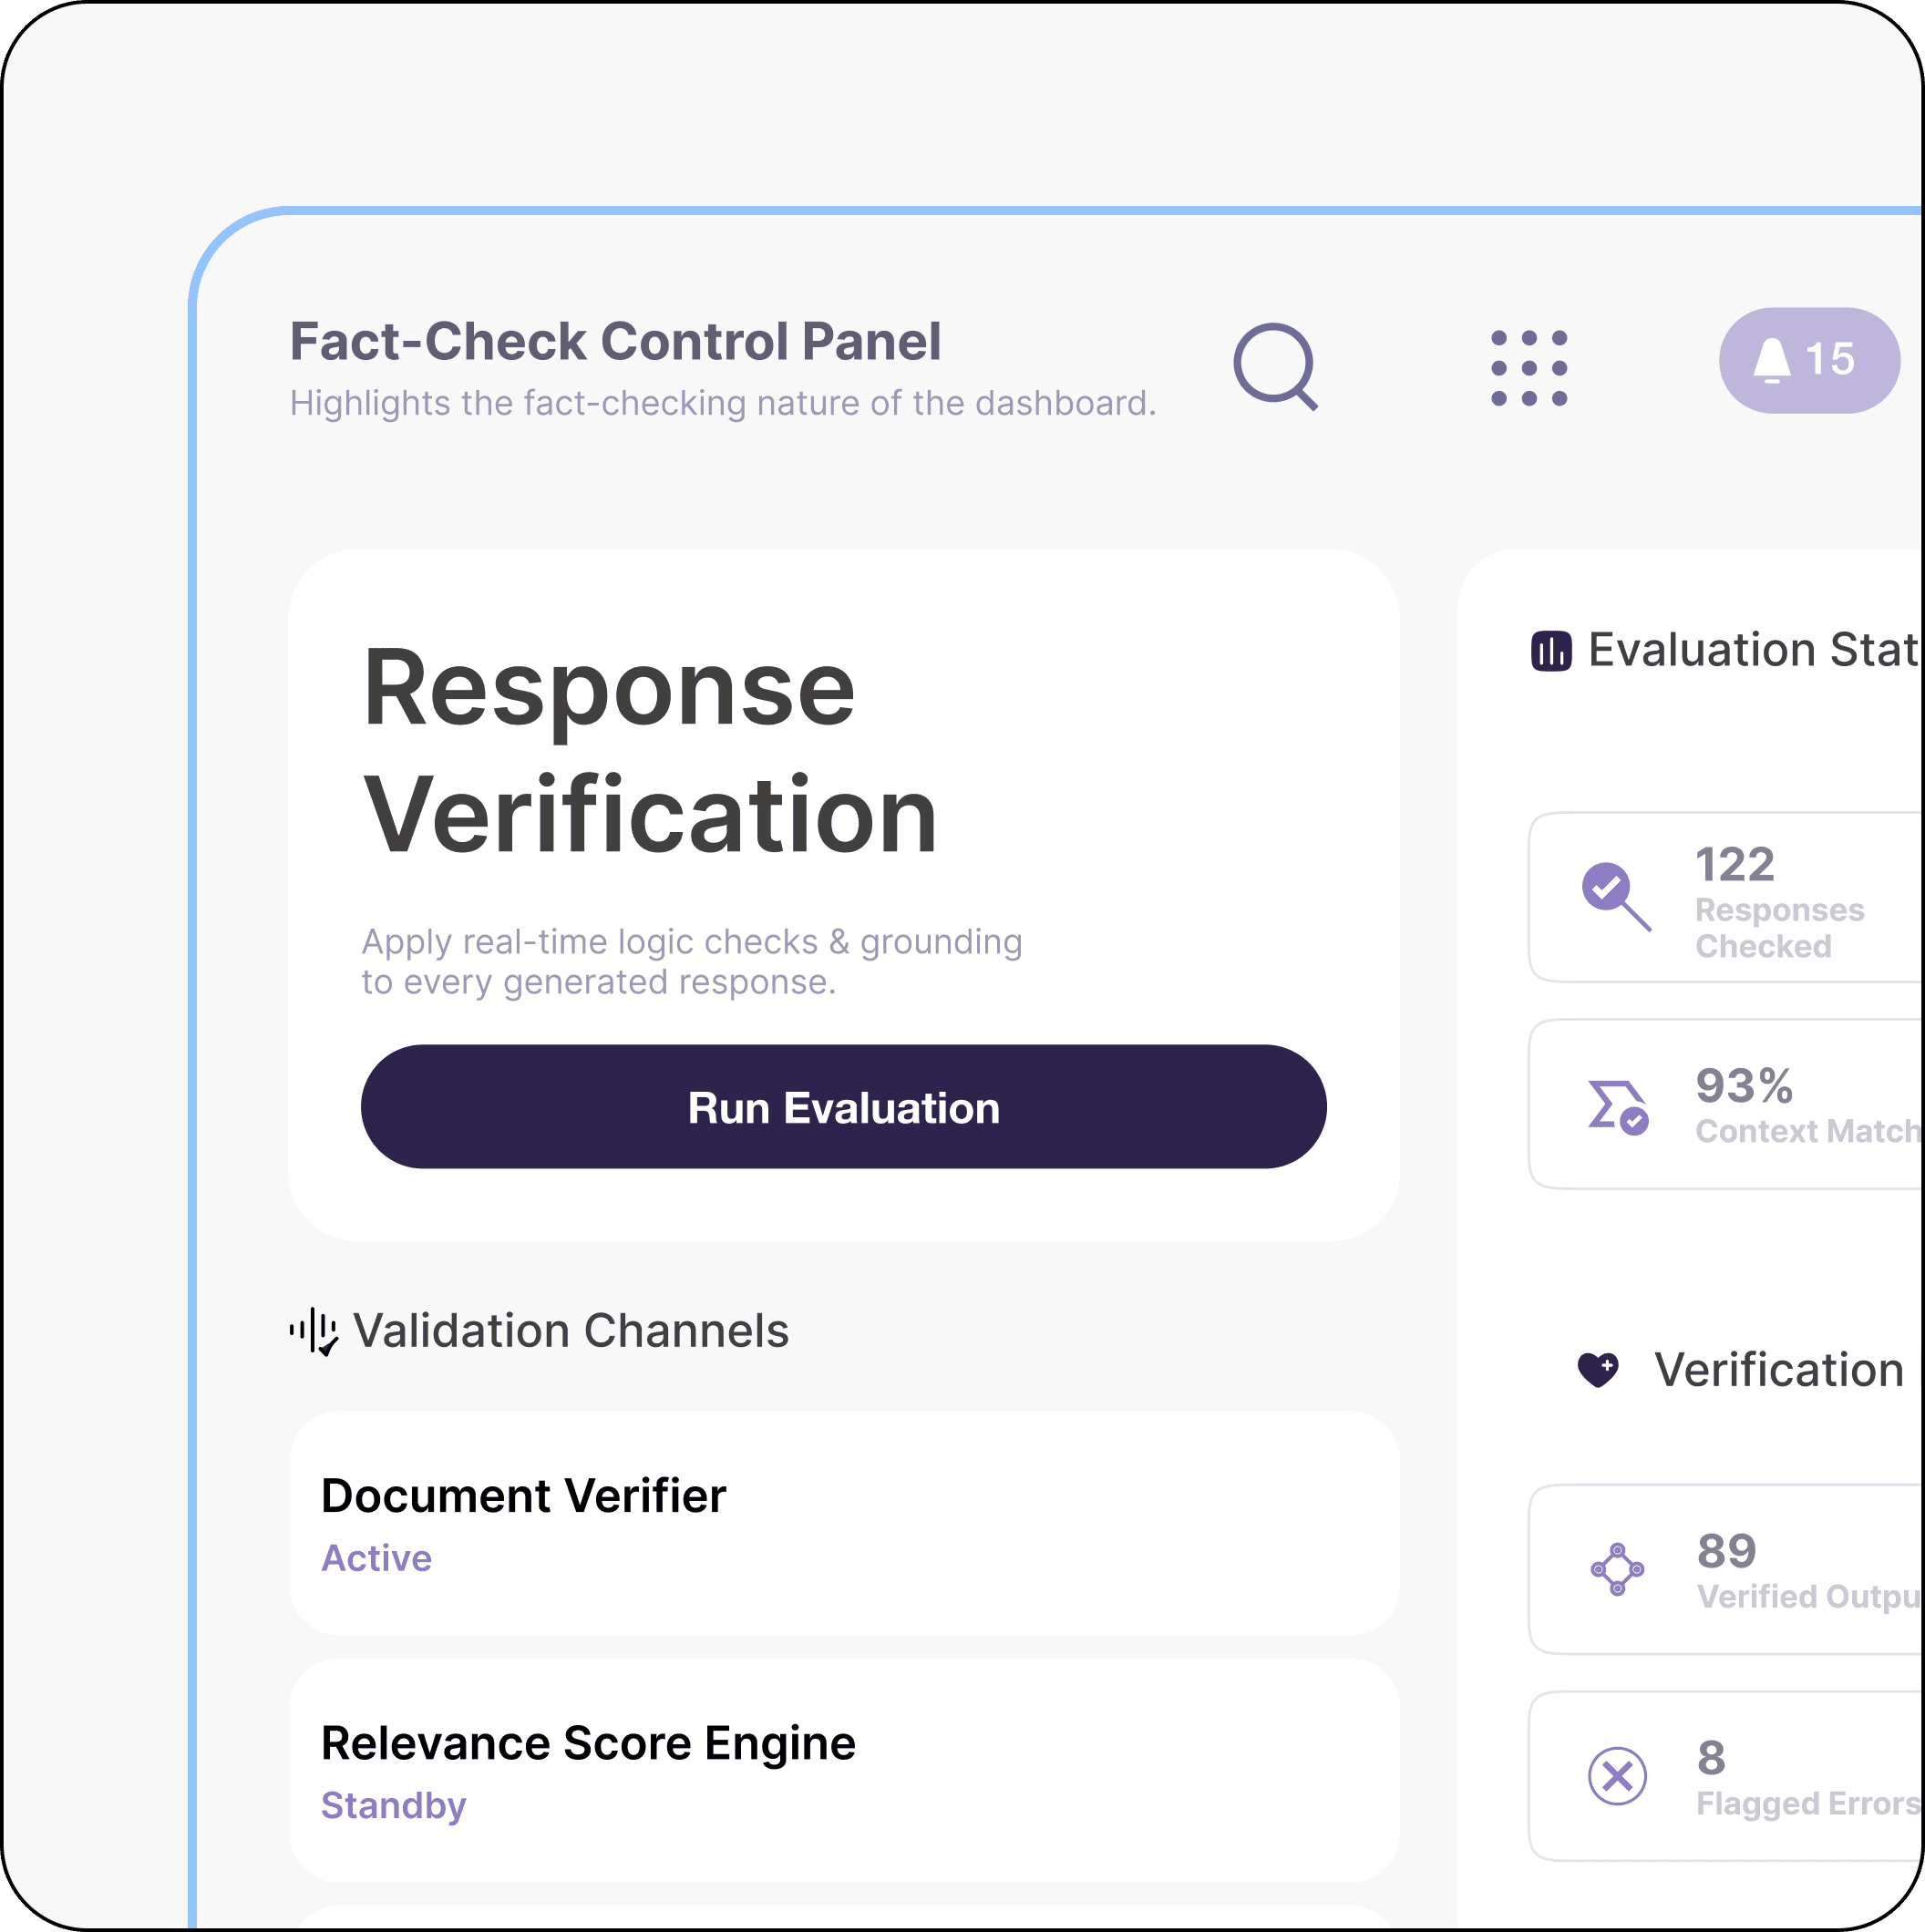
We evaluate generated outputs using logic checks, relevance scoring, and grounding validation to improve contextual alignment, source traceability, and response reliability.
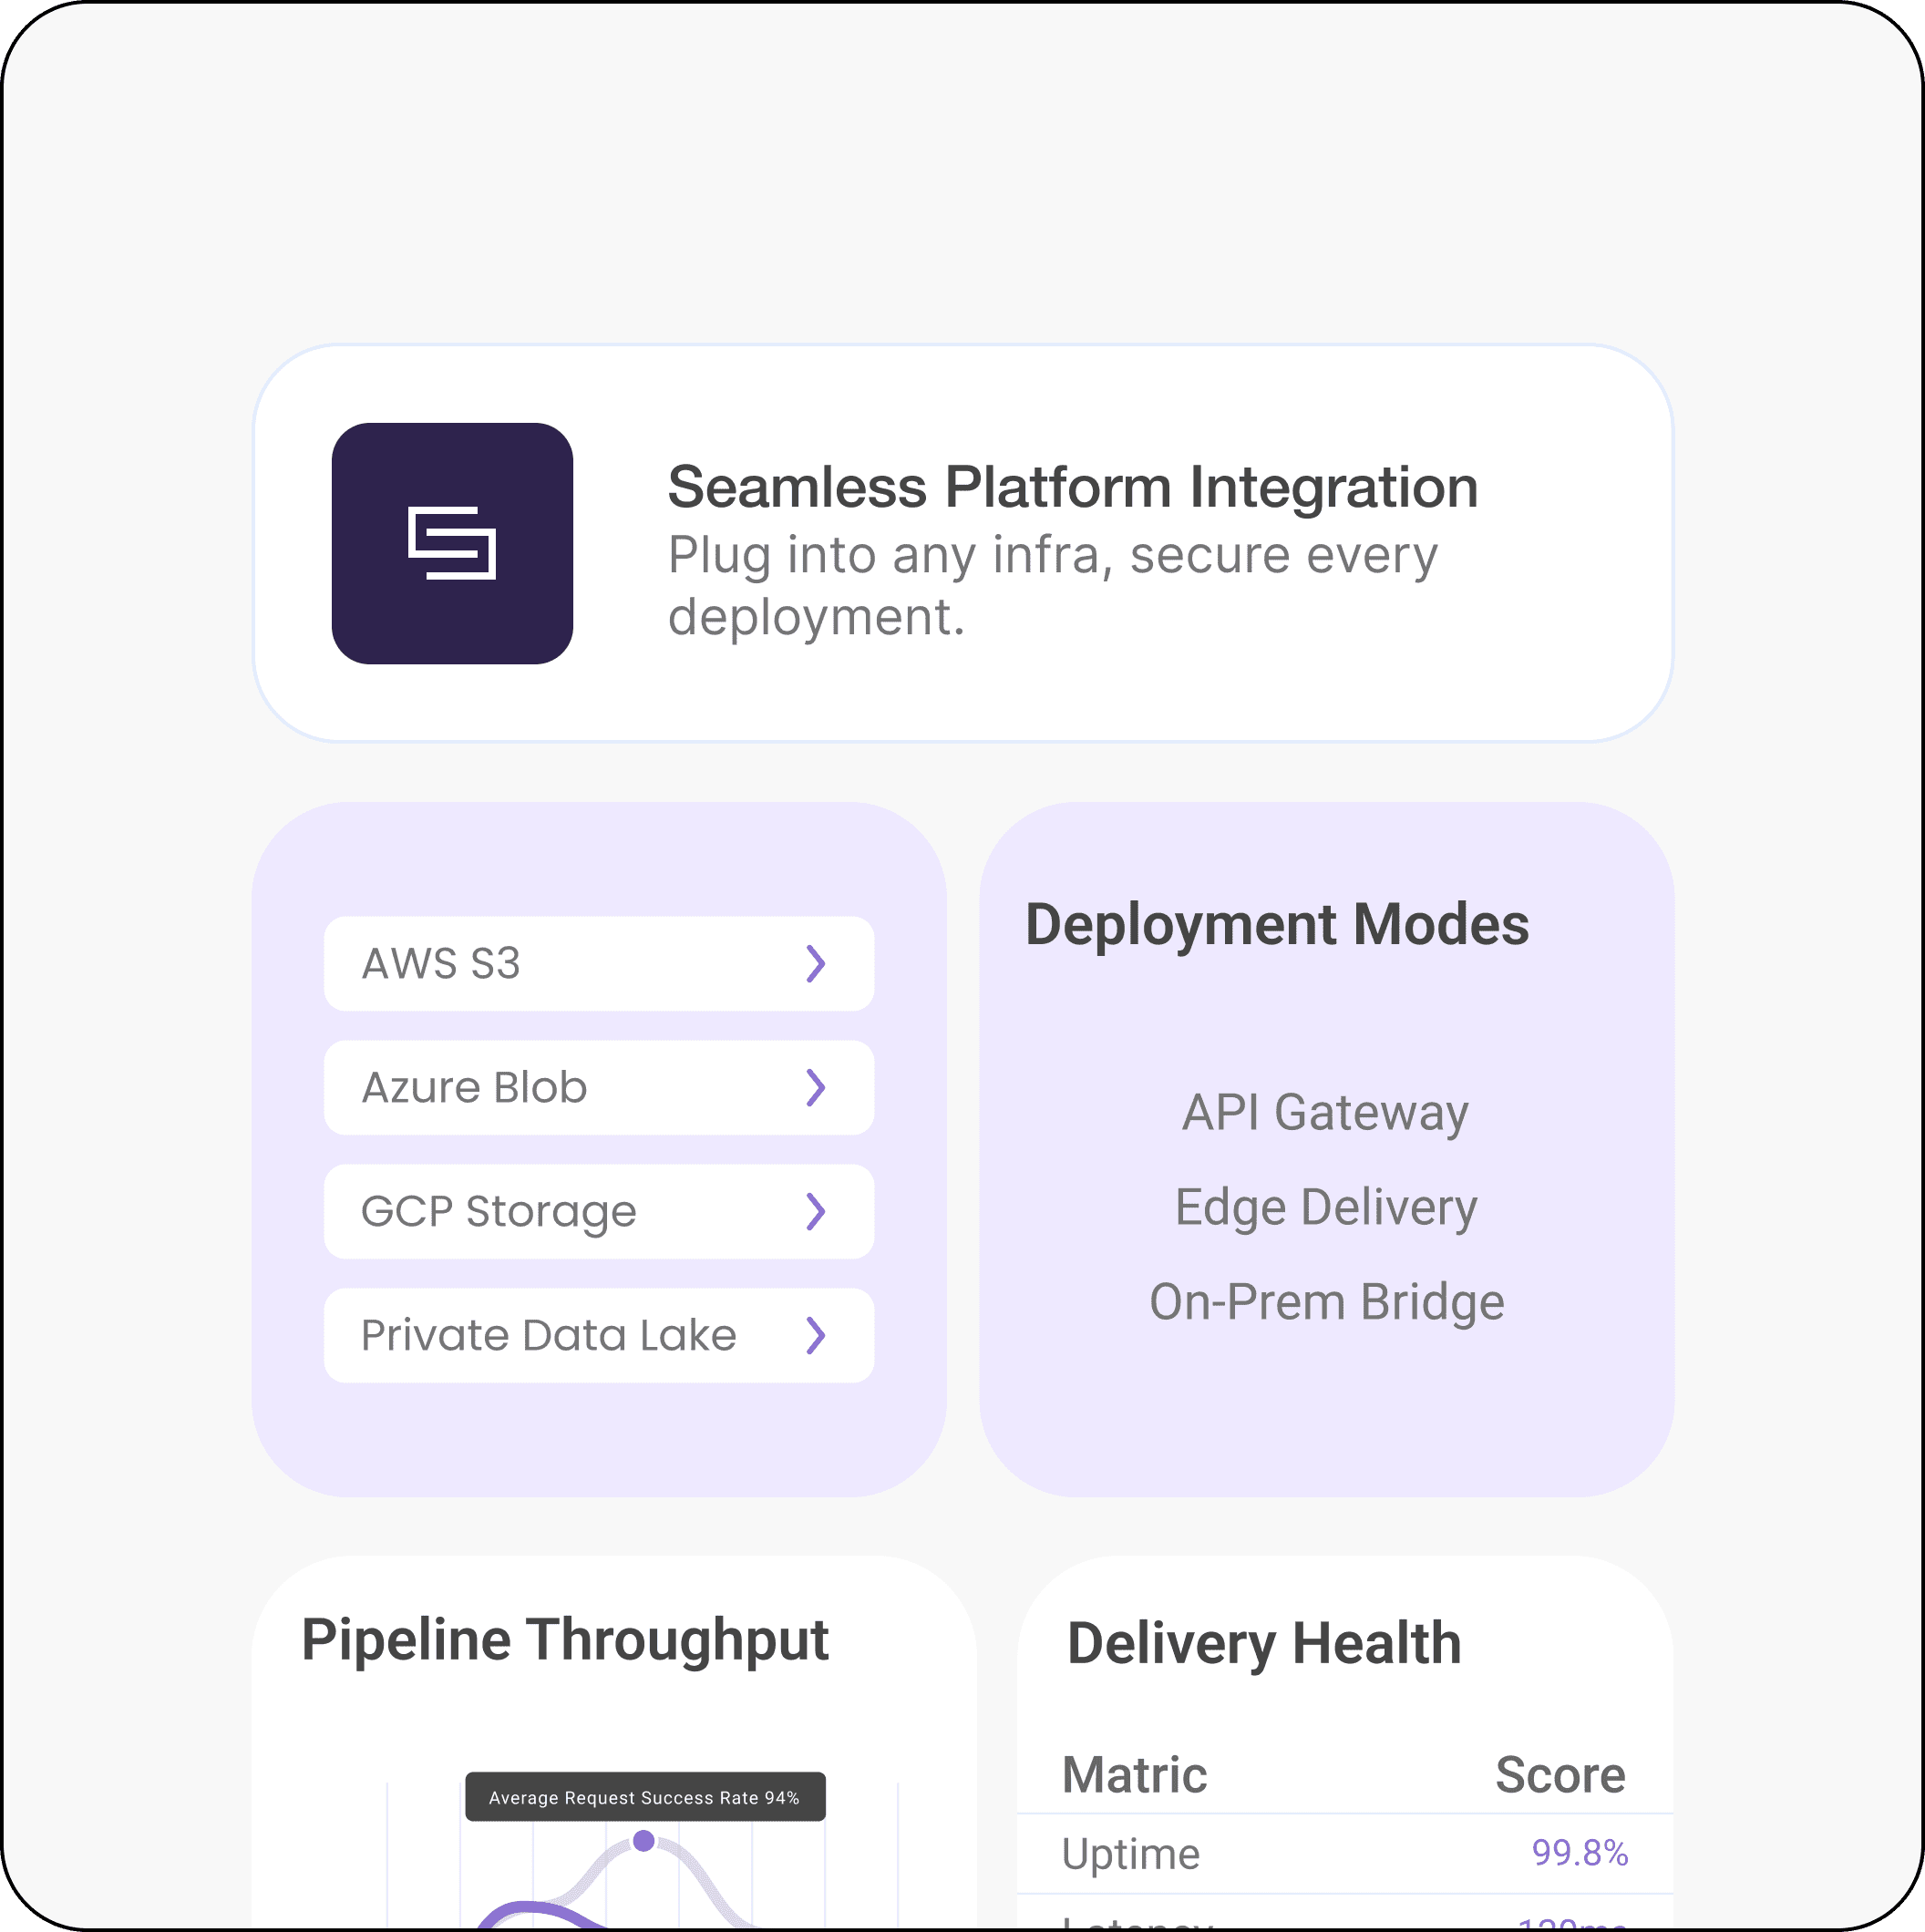
Our RAG engineers integrate retrieval pipelines with cloud environments, intranet systems, private data lakes, and existing enterprise applications. We apply access controls, encryption, and deployment configurations based on your infrastructure and security requirements.
We provide continuous support for model refresh, index refinement, and policy mapping—ensuring your RAG system evolves with data, usage, and security needs.
Retrieval-Augmented Generation (RAG) Solutions We Offer
Our Retrieval-Augmented Generation (RAG) solutions are built to production standards—helping enterprises enhance AI-powered search, intelligent Q&A, and document automation at scale.
RAG-Powered Knowledge Bots
Deploy conversational agents grounded in trusted sources to answer internal or customer-facing queries with precision.
Search-Integrated Copilot Tools
Enable smart copilots that pull live data from docs, tickets, or systems to assist with workflows and decisions.
Enterprise Q&A Automation
Build domain-tuned Q&A engines that return traceable, context-rich responses from enterprise knowledge bases.
Custom Retriever-Reader Pipelines
Fine-tune retrievers and generators with private embeddings to maximize recall and grounded generation.
Context-Aware Document Assistants
Add generative layers on top of internal docs for summarizing, highlighting, or converting to tasks.
Real-Time Insight Summarizers
Process live data streams, calls, or chats into actionable summaries and decisions with traceable sources.
Enterprise RAG Solutions for Knowledge-Driven Workflows
We architect advanced custom RAG services and solutions that fuse retrieval precision with generative AI flexibility—built to scale with your enterprise data. Whether enhancing enterprise search, surfacing contextual insights, or powering internal copilots, our expert RAG Developers and architects ensure high-quality results at every step of the journey.
Private RAG pipelines for querying enterprise documents and FAQs
Hybrid search systems for retrieving high-relevance results across silos
AI assistants grounded in internal content for HR, legal, IT, and ops
Summarization of multi-format content—PDFs, chat threads, and knowledge bases
Auto-parsing of form responses, surveys, and feedback datasets
Why Choose GeekyAnts As Your RAG Development Company
Choose GeekyAnts as your RAG development company to design, build, integrate, and maintain retrieval-augmented AI systems. With 20+ years of engineering experience, 550+ engagements, and 450+ engineers, we deliver RAG solutions for businesses across the USA and global markets.
We combine retriever-reader architectures, prompt-grounding logic, vector databases, and scalable infrastructure to support enterprise search, contextual copilots, document intelligence, and knowledge automation.
Our RAG engineers work with proprietary content, private enterprise data, and modern LLM stacks while accounting for source traceability, access control, deployment requirements, and ongoing retrieval performance.
RAG System Architects
We design domain-specific tools as part of our comprehensive RAG development services—from intelligent AI assistants to enterprise-grade Q&A bots—anchored in trusted, retrievable content.
Applied Retrieval Intelligence
We align retrieval workflows with business needs—powering support automation, document intelligence, and knowledge recall.
Scalable LLM-Retriever Engineering
Our team engineer integrated pipelines with optimized retrievers, tuned embeddings, and multi-environment deployment.
Query Grounding & Response Design
We build multi-hop chains and prompt layers that ensure context relevance and source traceability in every response.
Optimized Indexing & Performance
Our CoE fine-tunes latency, ranking quality, and recall accuracy using enterprise-grade vector stores and APIs.
Secure & Contextual Deployment
We support private-cloud and hybrid RAG deployment with access control, compliance, and system integrations.
Industries for Which We Deliver RAG Solutions
We deliver RAG solutions through a practical, enterprise-first approach. Our RAG solutions expertise spans multiple domains, solving challenges in knowledge retrieval, data fragmentation, and contextual accuracy. From internal Q&A systems in healthcare to legal document discovery and support copilots in enterprise ops, we design scalable RAG architectures that turn scattered content into precise, actionable insights.
Technology Stack for RAG Development
- GPT
- LlamaIndex
- Prompt Engineering
- Lang chain
- React Native
- React
- Android
- Flutter
- Angular
- Next.js
- VueJS
- SvelteJS
- Expo
- gluestack-ui
- Native iOS
- MongoDB
- PostgreSQL
- MariaDB
- Firestore
- Amazon DynamoDB
- MySQL
- Jenkins
- Manual Testing
- Selenium
- Figma
- Illustrator
Book A Free Discovery Call
Our team will review your RAG use case, data sources, integration requirements, security needs, and deployment environment. We will outline a practical path for retrieval architecture, grounding, validation, and enterprise integration while keeping your project inputs protected under our NDA policy
Contact us
Learn More About Our Retrieval-Augmented Generation (RAG) Solutions and Services
The cost of building a custom RAG solution with GeekyAnts depends on the complexity, data requirements, integrations, and scale of deployment. On average:
- Basic RAG integration (using pre-existing retrieval and generation components) starts around $30,000 – $70,000.
- Custom RAG solutions (domain-specific retrieval systems, fine-tuned generators, tailored pipelines) typically range from $70,000 – $200,000+.
We design RAG systems that balance cost-efficiency, scalability, and performance, with flexible engagement models to fit your business needs.
RAG development services connect large language models with relevant enterprise data before generating a response. This process helps AI applications provide more accurate, current, and context-aware answers. GeekyAnts designs retrieval, grounding, and validation workflows that support enterprise search, internal Q&A, document automation, and AI assistants.
A RAG system built by GeekyAnts includes:
- A retriever module that searches external knowledge bases or indexes for relevant documents or facts.
- A generator module (typically a large language model) that produces answers or content, grounded in the retrieved data.
An orchestration layer that connects retrieval and generation, manages prompts, and ensures seamless AI workflows.
In a GeekyAnts-built RAG system, the retriever indexes your structured or unstructured data (e.g., via vector databases). When a query comes in, the retriever fetches the most relevant documents. These documents are passed to the language model, which uses them to generate context-rich, accurate responses. This setup ensures outputs are tied to real, verifiable data.
Traditional language models generate responses based on their training data alone. RAG systems, as designed by GeekyAnts, enhance this by adding live retrieval from external knowledge sources. This means RAG models provide outputs that are more accurate, current, and explainable—ideal for enterprise and domain-specific use cases.
Yes. GeekyAnts specializes in building custom RAG solutions tailored to your domain, whether it’s healthcare, fintech, legal, or enterprise support. We fine-tune retrievers, curate domain-specific knowledge bases, and adapt generation models to align with your business context and compliance requirements.
Yes. GeekyAnts can integrate RAG solutions with existing knowledge bases, enterprise search tools, analytics dashboards, CRM and ERP platforms, cloud environments, chatbots, and virtual assistants. We use modular APIs and services to connect retrieval and generation components with your current architecture, data sources, access controls, and business workflows.
RAG systems can retrieve from diverse sources, including:
- Internal documentation and knowledge bases
- Public or proprietary datasets
- CRM and ERP systems
- API-fed dynamic data (e.g. news feeds, product catalogs)
- Vector databases of embeddings
We help identify and structure the best sources for your RAG system.
GeekyAnts designs enterprise RAG systems around the organization’s infrastructure and security requirements. Depending on the environment, this includes access controls, encryption, private-cloud or hybrid deployment configurations, secure connections to enterprise data sources, and source traceability. These controls are incorporated into retrieval pipelines and system integrations rather than treated as a separate layer after deployment.
A RAG development company should be able to manage knowledge-source planning, retrieval architecture, LLM integration, grounding, validation, enterprise integration, security, deployment, and ongoing evaluation. GeekyAnts provides enterprise RAG development services designed around each organization’s data sources, user queries, workflows, infrastructure, access requirements, and retrieval-performance needs.
