
30% of a senior architect's time goes into reading RFPs and writing proposals rather than designing systems or solving engineering problems.
A 50-page enterprise RFP lands in an inbox. Two hours later, the architect has concluded what they suspected on page three: React Native frontend, Node backend, PostgreSQL, and Stripe for payments. The decision was predictable, but the process was manual and time-consuming.
This manual work of extracting requirements, spotting contradictions, and drafting a coherent proposal repeats for each RFP. Our teams built an AI-powered co-pilot to change that.
What the AI Presales Co-Pilot Does
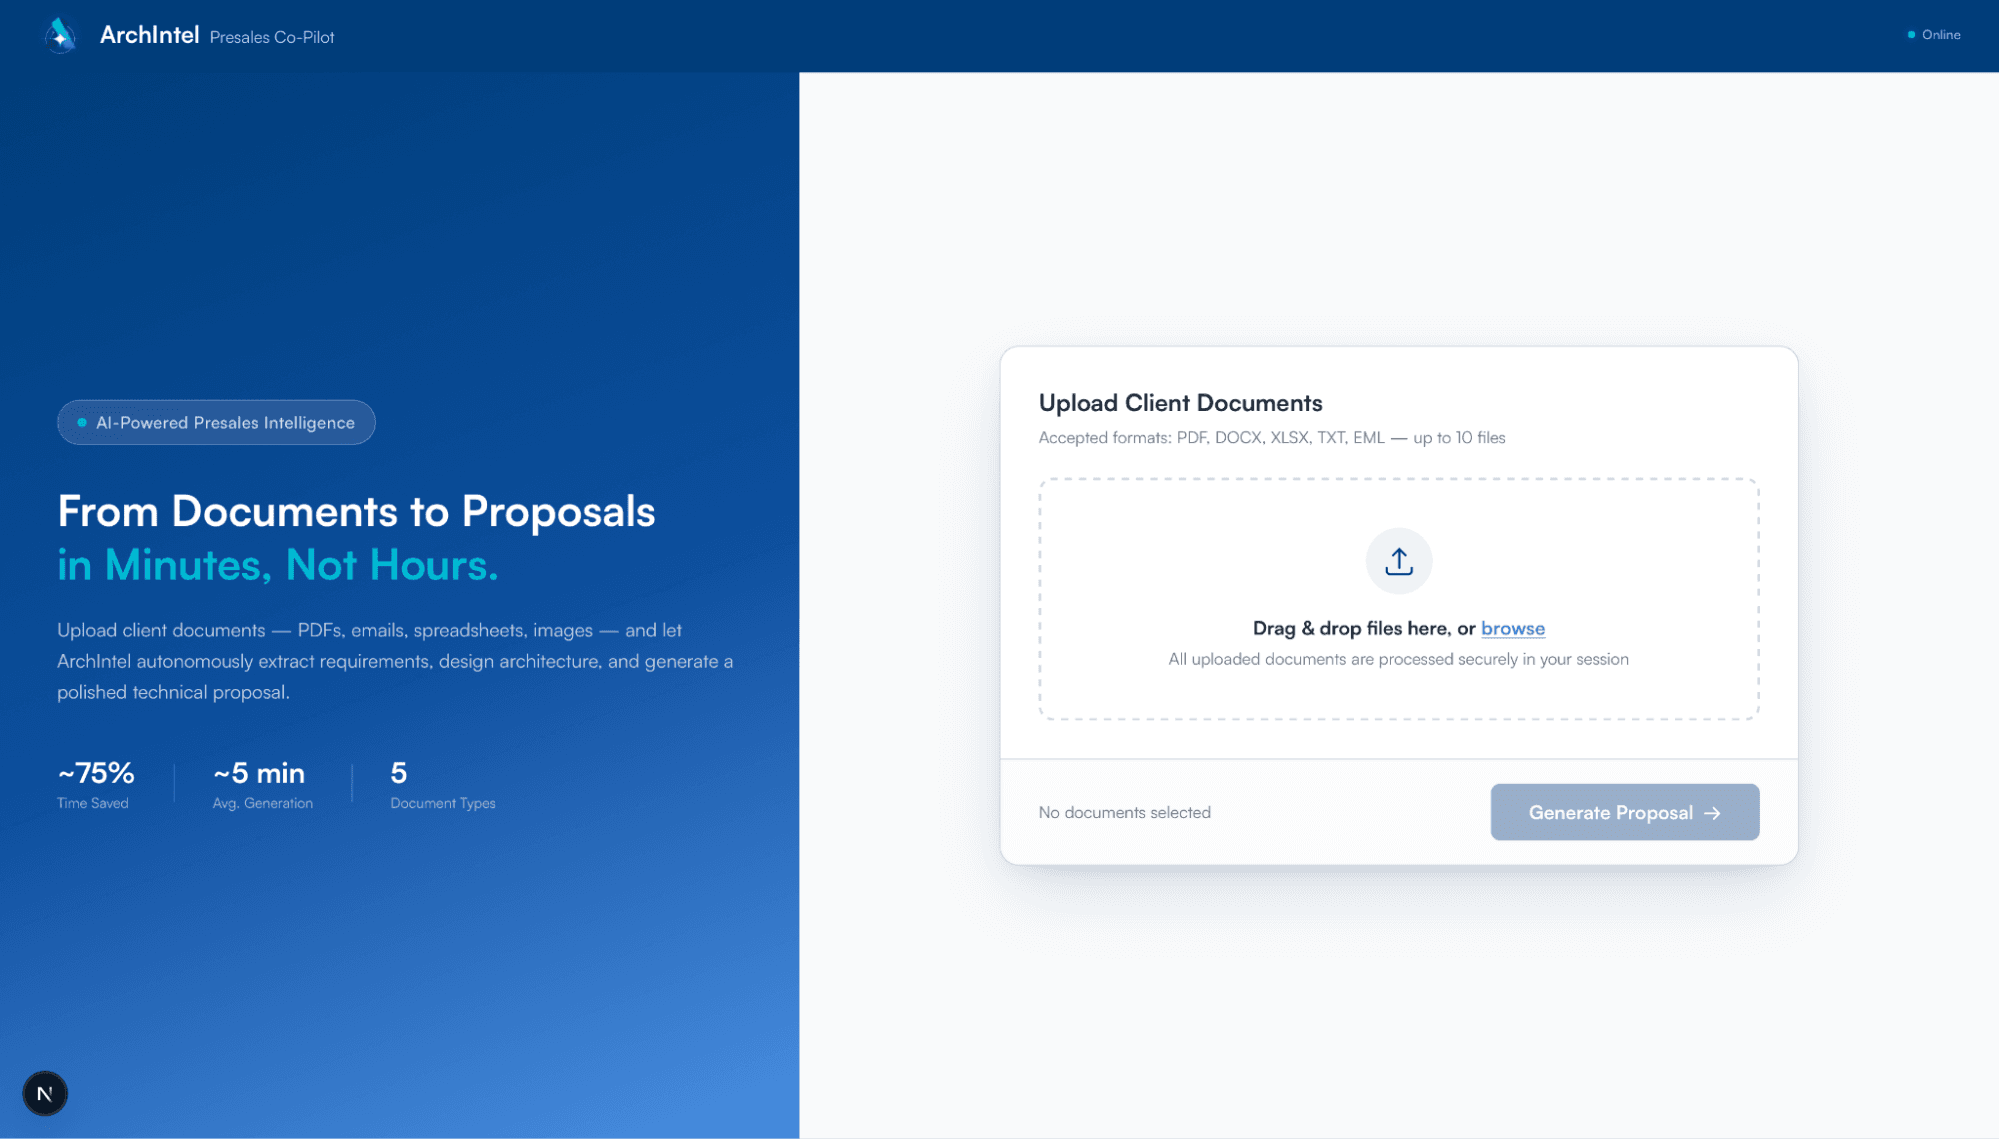
This system assists with the presales cycle. You upload a client's documents—PDFs, Word docs, Excel sheets, or emails—and the system produces a draft technical proposal that an architect can review and refine in 15 minutes instead of writing from scratch for 3 hours.
The value extends beyond document generation to reasoning:
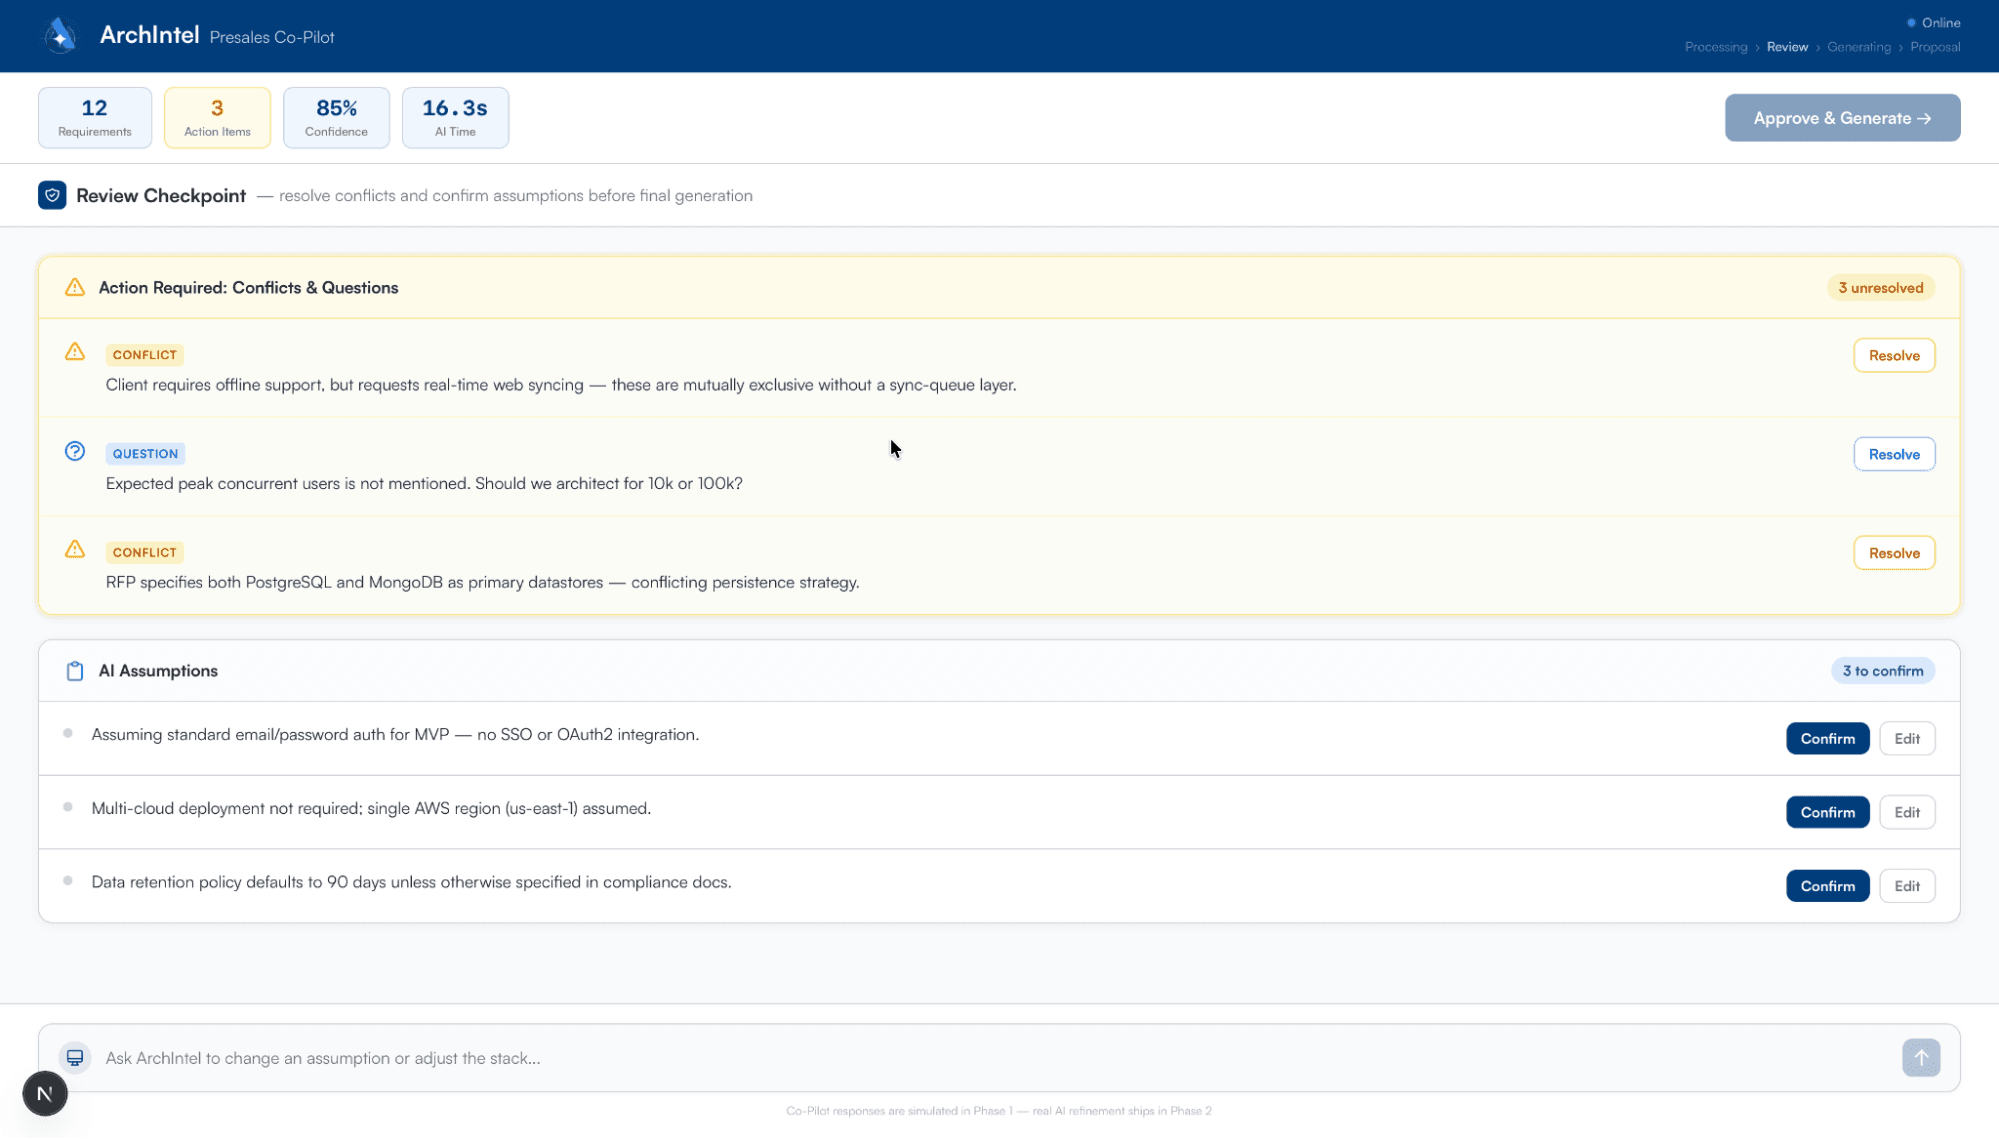
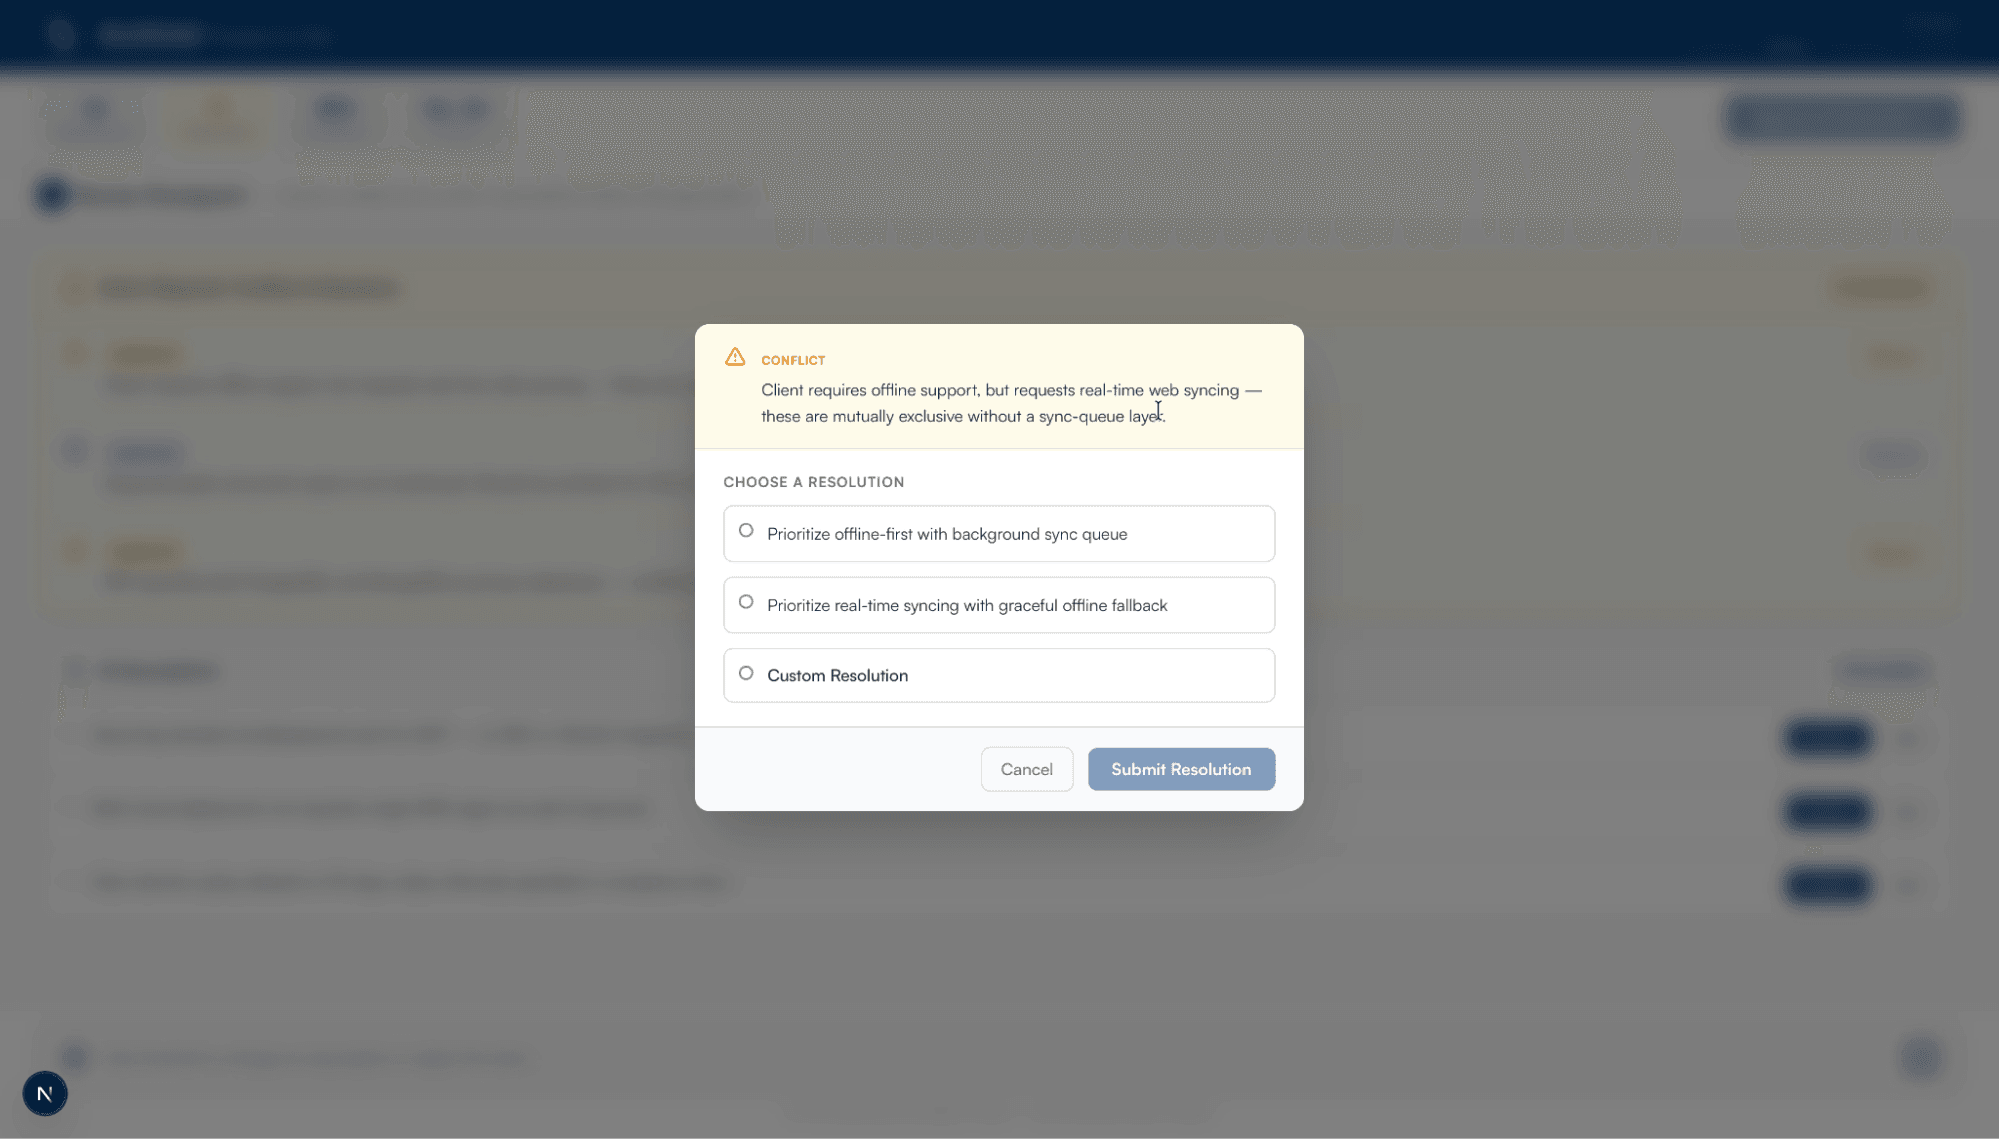
- Detects Contradictions: It flags tensions, such as a request for Native Mobile only paired with Critical SEO.
- Surfaces Assumptions: It states the assumptions it is making (e.g., assuming Stripe for payments) so an architect can confirm or override them.
- Confidence Scoring: It scores its own decisions, indicating where reviewers should focus attention.
How It Works: Four Specialized Agents
The system runs four specialized AI agents in sequence. The entire pipeline runs over a WebSocket connection, streaming progress to the dashboard in real time.
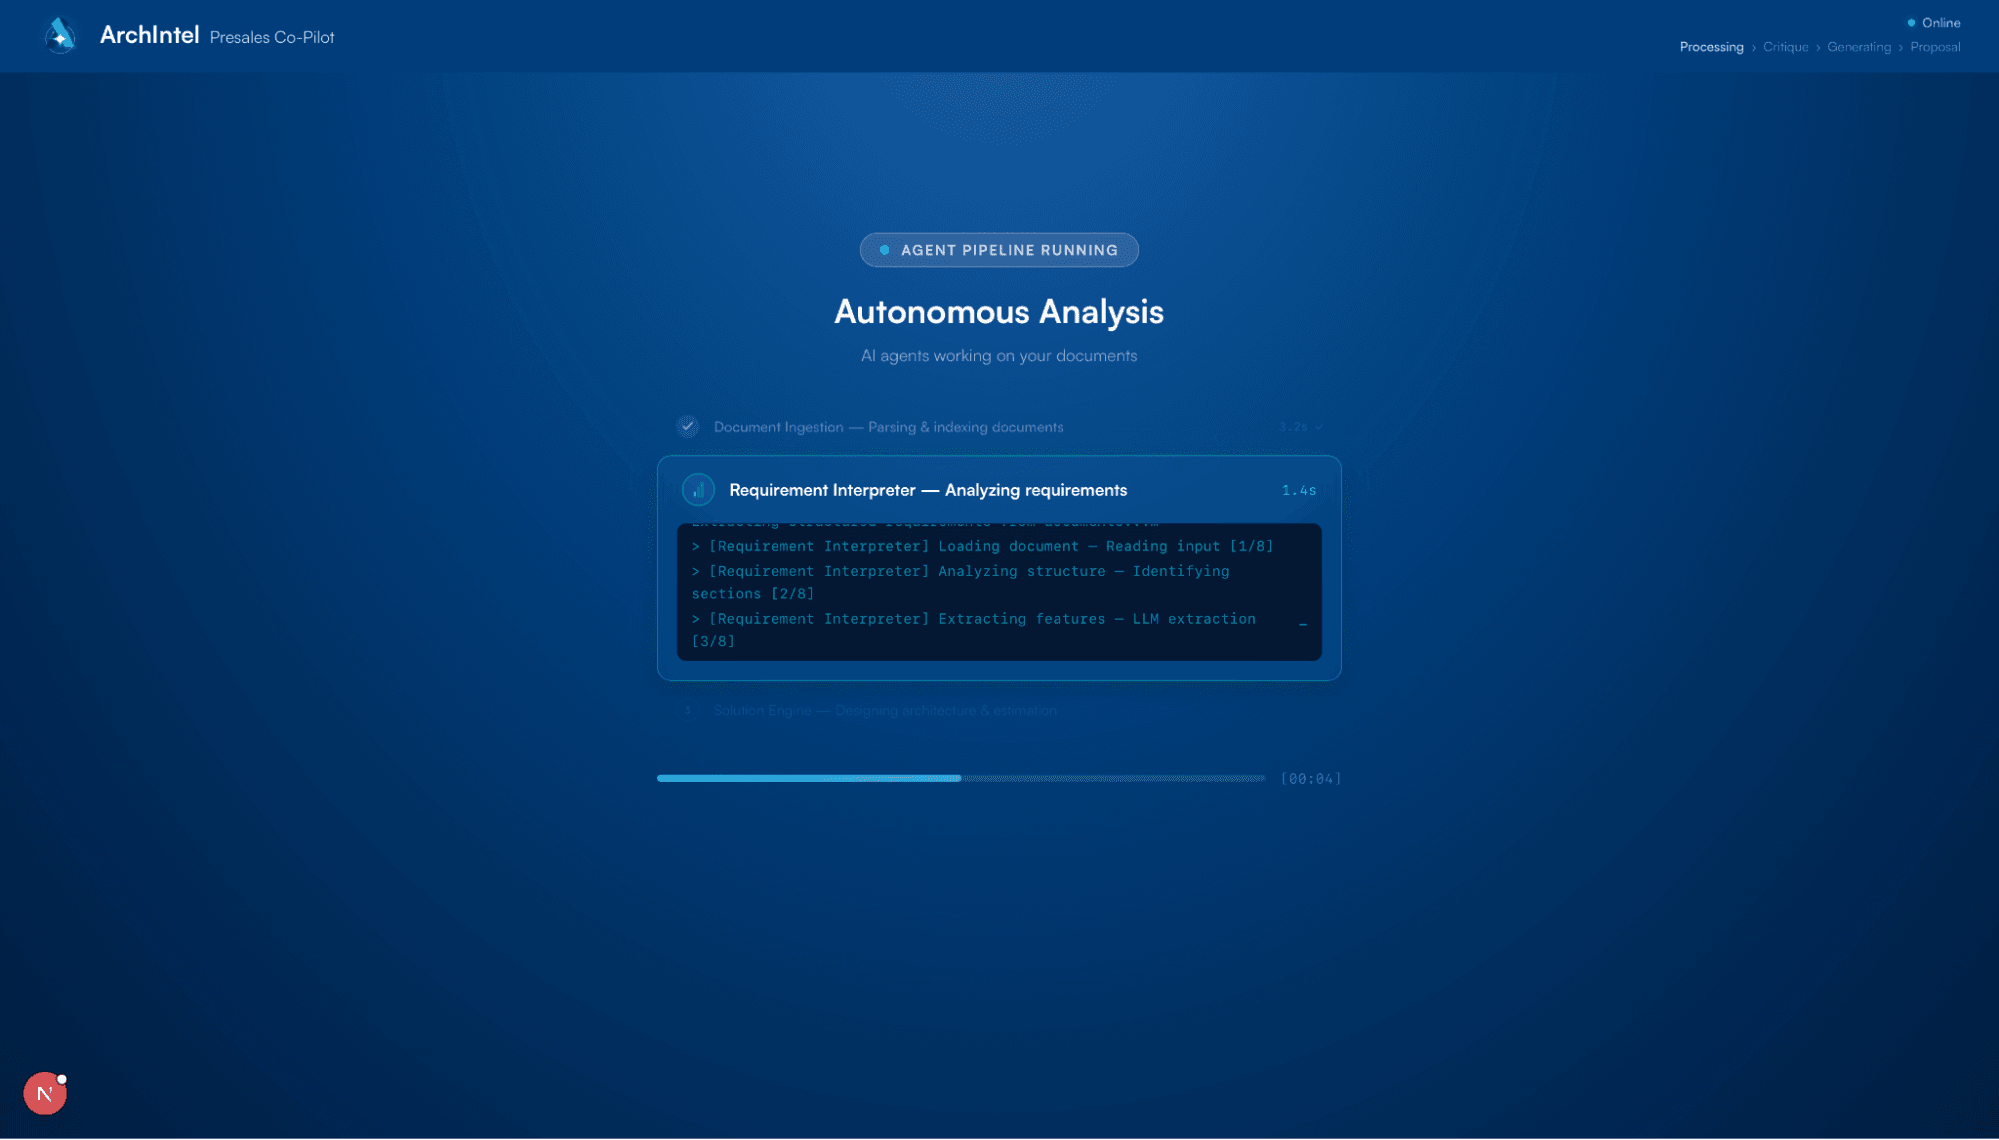
Agent 1: Requirement Interpreter
This agent parses raw, unstructured documents using format-specific tools (PyMuPDF, pandas, etc.). It extracts features, technical constraints, and non-functional requirements.
- Pattern Enrichment: If a two-sided marketplace is mentioned, the system suggests features like ratings and booking based on a built-in knowledge base.
- Conflict Detection: A rule engine identifies over-engineering or technical mismatches during initial analysis.
Agent 2: Solution Engine
This agent produces tech stack recommendations and effort estimates. It uses a hybrid approach: deterministic rules suggest the baseline stack (e.g., NestJS/PostgreSQL), while the LLM validates that choice against the specific client context. Effort estimation provides optimistic-to-pessimistic ranges (e.g., "120–210 hours") to reflect real-world uncertainty.
Agent 3: Self-Critique
Before a proposal is written, a critique agent reviews the solution for consistency. If an assumption contradicts a user input, the system sends a clarifying question back to the architect via WebSockets. Only when the critique approves does the pipeline proceed to generation.
Agent 4: Proposal Composer
The final agent selects a template (MVP, Enterprise, or Standard) and generates a Markdown proposal. The output covers Problem Understanding, Tech Stack, Architecture Overview, and Risk Mitigation.
The Pipeline at a Glance
Stage | Role | Output |
|---|---|---|
1. Parse | Ingestion of any file type | Combined raw text |
2. Extract | Conflict & pattern detection | Structured requirements JSON |
3. Design | Rule-based stack matching | Solution + effort mapping |
4. Review | Validation & User Clarification | Approved technical solution |
5. Write | Template-based generation | Polished Markdown/PDF proposal |
Engineering Insights
Rule-based systems and LLMs complement each other: Conflict detection and effort mapping do not need an LLM—they need deterministic rules. LLMs handle ambiguity and prose generation.
Transparency is the primary feature. The reasoning trace provides more value than the document itself. By showing why assumptions were made, the system enables architects to review proposals 5–10x faster.
The Technical Stack
- Backend: Python with FastAPI for async orchestration.
- AI Layer: OpenRouter (Claude, GPT-4, and Gemini) for multi-model reasoning.
- Communication: WebSockets for real-time streaming to a React-based frontend.
- Knowledge Base: JSON-based datasets for requirement patterns and stack decision rules.
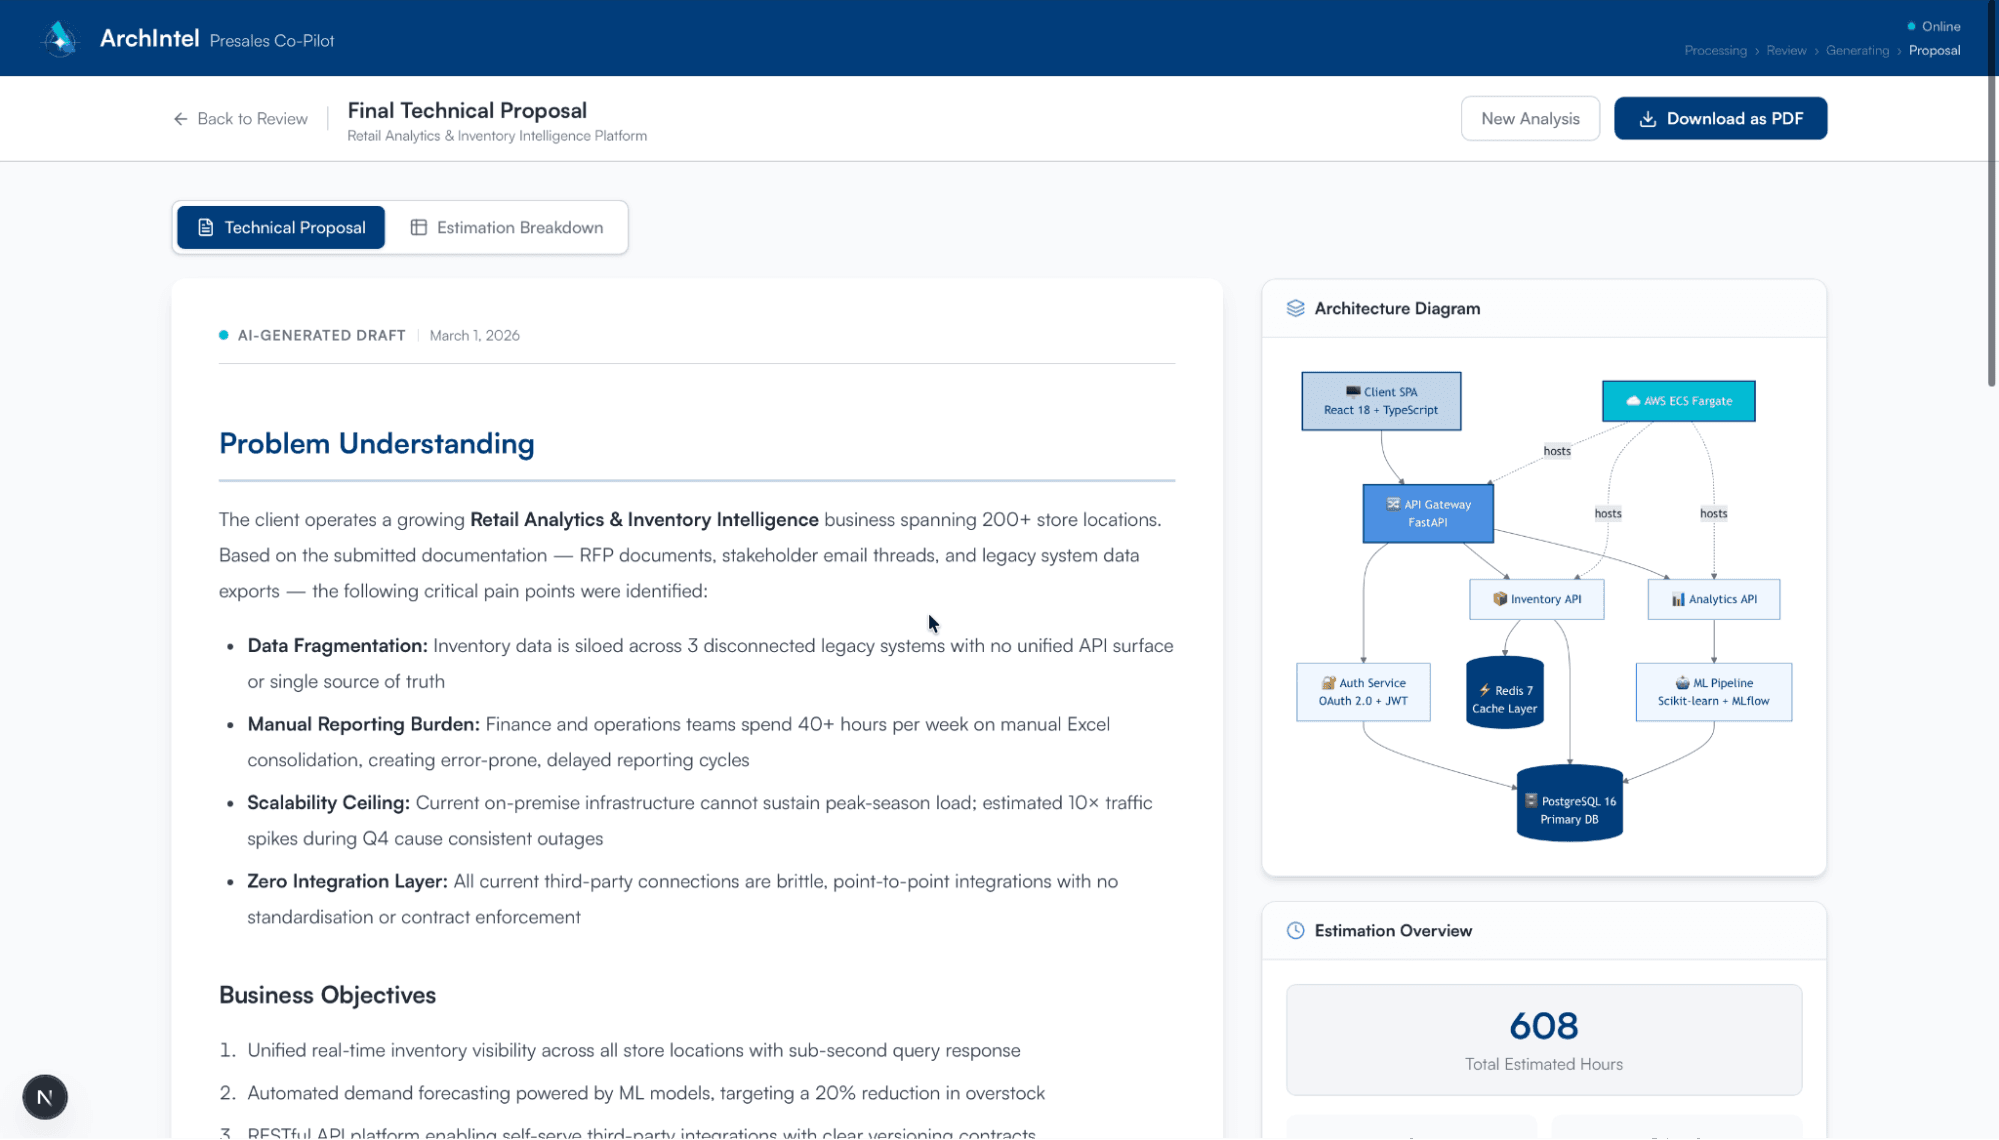
Presales reasoning is repeatable. AI systems that make reasoning transparent and reviewable accelerate the path from RFP to proposal.