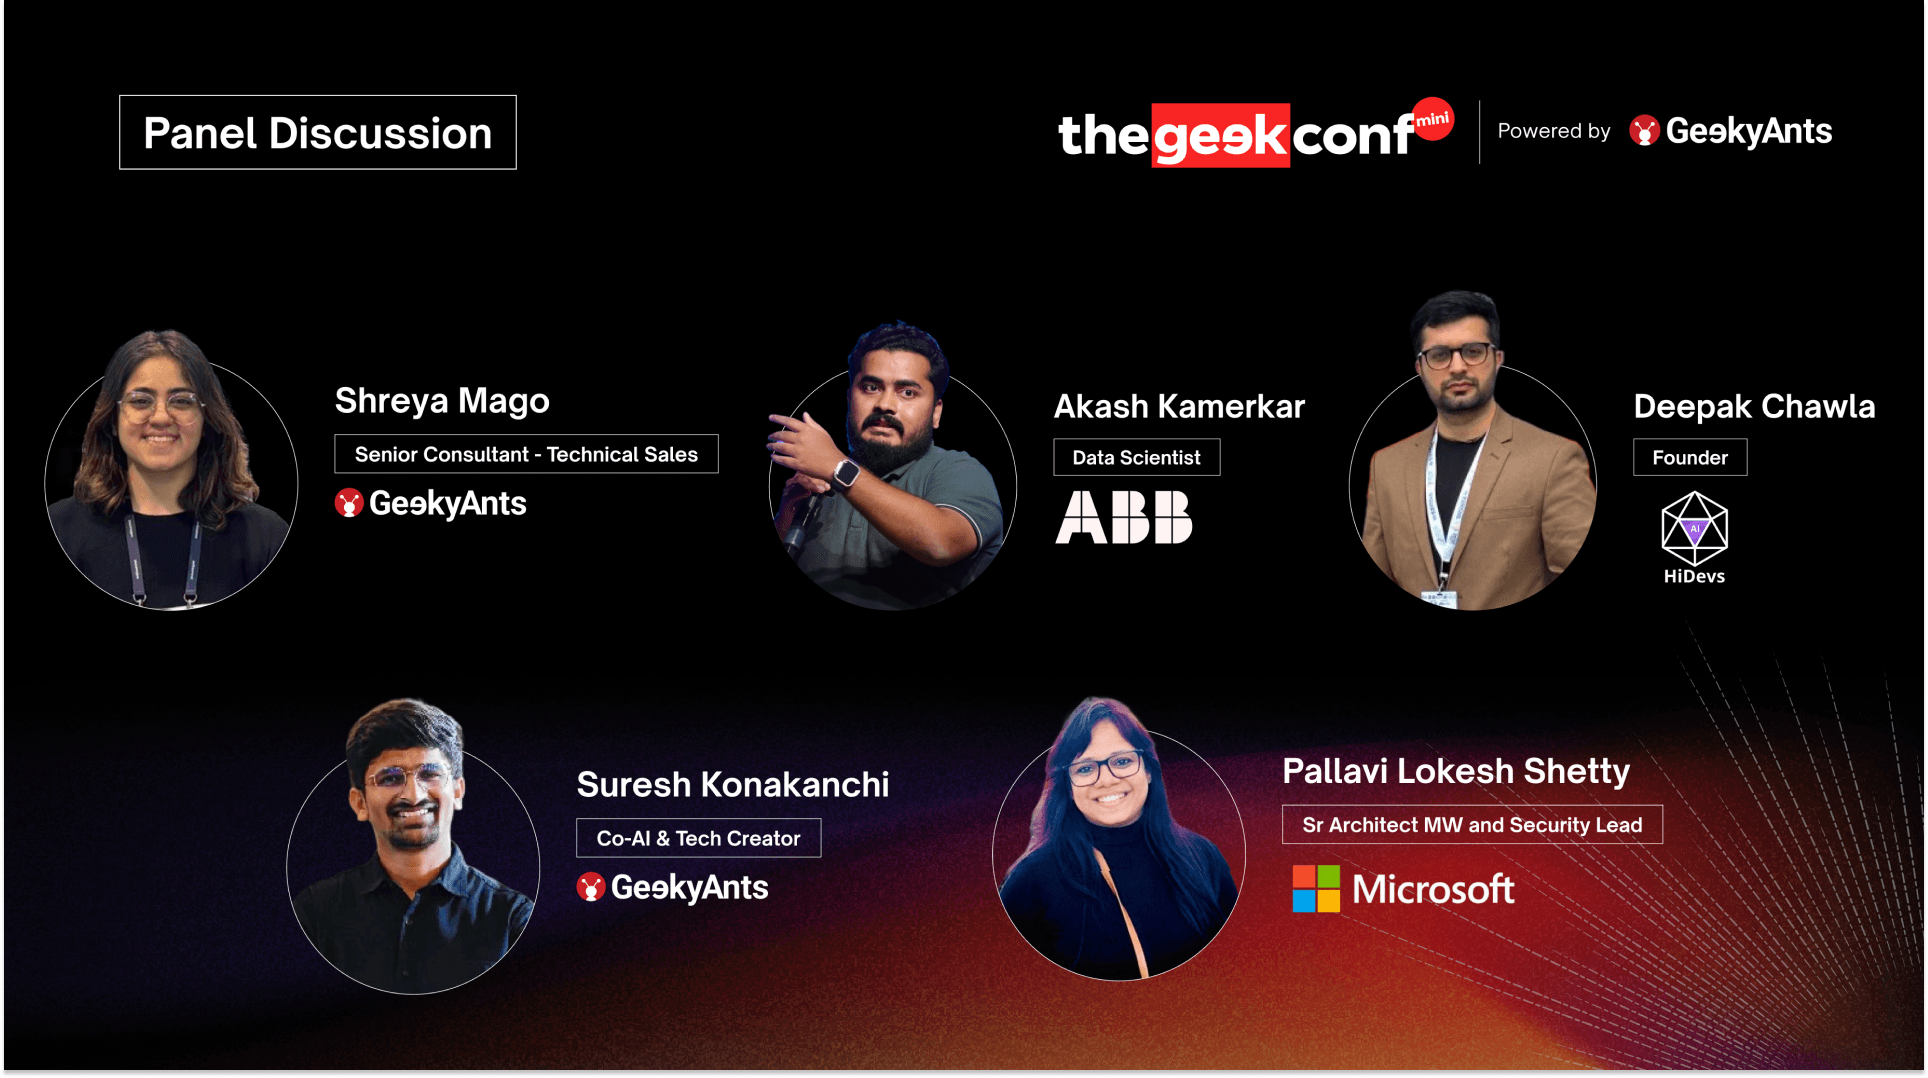

Editor's Note: This blog is adapted from a panel discussion at thegeekconf mini 2026, hosted by GeekyAnts. The session brought together Pallavi Lokesh Shetty, Akash Kamerkar, Deepak Chawla, and Suresh Konakanchi — architects, engineering leaders, and technical consultants with backgrounds spanning manufacturing, enterprise AI, full-stack engineering, and cloud platforms. Together, they cut through the noise around building AI-first products, drawing a sharp line between teams that treat AI as an add-on and teams that architect for it from the ground up, making the case for why design decisions at the MVP stage determine how far a product can scale.
Speed, Accuracy, or Scalability — It Depends on Who You Serve
The panel opened with a foundational question — when building an AI-first MVP, what comes first: speed, accuracy, or scalability? The answer depends on who you serve. Banking and manufacturing demand accuracy first. Social products can afford to move fast and iterate. One panelist framed the order: build with speed, drive to accuracy, then stop at scale.
Data and the User Come Before Everything
Before any of that, the panel stressed two things — understand the persona you are building for, and get your data right. Garbage in, garbage out came up multiple times as the single most important principle at the MVP stage.
Pre-trained Models Over Custom Builds
On pre-trained versus custom models, the panel leaned toward using what exists in the market. Building a custom model demands enormous investment in time, data, and compute. By the time you finish, the market has moved ahead. The exception is when an organization has significant proprietary data and wants an expert agent built on that data. For everyone else, start with available models on platforms like Hugging Face and move fast.
The Biggest MVP Mistake: Building for Engineers, Not Users
The biggest architectural mistake teams make at the MVP stage is building from an engineering perspective instead of a user perspective. Most MVPs follow the order: product, validation, user. The panel suggested reversing it — start with the user, understand the problem, then build.
Three Non-Negotiables When Moving to Production
On moving from MVP to production, the panel identified three non-negotiables: observability, a feedback loop, and security. You need to know what requests come in, what tools get called, how many tokens get consumed, and what comes out. Without that data from day one, you cannot make an informed decision to scale. Red teaming before production is critical — not for toxicity filters alone, but for prompt injection and data extraction through the agent itself.
Token Economics vs. the Rise of SLMs
Token economics came up as a production-stage concern. At prototype scale, token costs are manageable. At a million users, the math changes. One panelist disagreed and pointed to SLMs as the longer-term answer — purpose-built small models that run on edge devices without token costs. The rest of the panel agreed the direction is right but put the timeline at three to five years.
Rethinking AI Architecture from the Ground Up
The panel discussed what redesigning AI architecture from scratch would look like. One panelist argued that LLMs built on text data cannot reach AGI because human cognition is image-based, not text-based. Another countered that today's models are multimodal — vision, voice, and image interpretation are all available now and closing that gap.
Audience: Evaluation, Jobs, and Sustainability
The audience raised three strong questions. On evaluation — the panel's answer was that evaluation never stops. A continuous feedback loop is the correct state for any AI product in production. On jobs — the panel's position was that specific technology skills still matter, but the direction of training is toward full-stack builders who work with agents. On sustainability — the panel acknowledged the resource consumption of large AI systems as a real concern and pointed to historical hardware miniaturization as a reason for optimism.
Build Now. Don't Wait.
The session closed on the question of whether to wait for AI to stabilize before building. The panel's answer was clear: don't wait. Build from the perspective of user value. The technology will keep changing. The use case and the persona are what stay constant. Test every new model that arrives against what you have, and keep moving.