
K3s in Action: Why We Chose It First, and How It Scales with Us
For teams shipping MVPs or managing early-stage products, the infrastructure question is no longer “Should we use Kubernetes?”—it’s “How do we use Kubernetes without slowing ourselves down or overspending?”
When building infrastructure for fast-moving teams or early-stage products, you want something simple, reliable, and doesn't create more work than it solves. For us, K3s has been that middle ground—allowing production-level stability without demanding complex architecture or heavy engineering overhead from day one.
While it's marketed as a lightweight Kubernetes distribution, K3s isn’t just a tool for dev or test workloads. We've found it capable enough to run production-facing services, power developer self-service needs, and accelerate our MVP delivery pipeline.
This article shares our experience using K3s in real-world conditions, some technical steps on how we use it, and how we’ve planned for a future migration to EKS or more robust environments if scale demands it.
Low Learning Curve for Devs and Infra Teams
K3s, developed by Rancher Labs (now part of SUSE), is a certified Kubernetes distribution built for resource-constrained environments. It’s known for:
- Bundled core Kubernetes binaries into a single binary under ~100MB.
- Uses SQLite or lightweight etcd for the datastore.
- Designed to run on minimal hardware (512MB RAM is sufficient for simple clusters).
- Built-in load balancer, local storage, and simplified TLS handling.
We adopted K3s primarily because it allowed:
- Developers to run the same orchestrator locally as in staging or production.
- Teams to quickly boot up environments on edge VMs or low-cost cloud instances.
- The DevOps team to focus engineering efforts on security, CI/CD, and system design—without spending time debugging the Kubernetes control plane.
K3s is Kubernetes minus the friction—perfect for devs focusing on application logic, not cluster bootstrapping.
How We Use K3s Technically
Here’s a glimpse into our setup and tooling around K3s:
Bootstrapping a Cluster
We typically bootstrap single-node clusters for environments like feature testing or developer sandboxing. For production-facing workloads, we use HA (High Availability) multi-node clusters with embedded etcd.
Single-node install:
curl -sfL <https://get.k3s.io> | sh -


Join an agent node:
curl -sfL <https://get.k3s.io> | K3S_URL=https://<server-ip>:6443 K3S_TOKEN=<secret> sh -


HA install (embedded etcd with multiple control planes):
curl -sfL <https://get.k3s.io> | INSTALL_K3S_EXEC="server --cluster-init" sh -
For TLS, load balancing, and DNS:
- We use Traefik (bundled) or nginx-ingress depending on team preference.
- cert-manager issues TLS certs via Let’s Encrypt.
- Internal DNS handled by CoreDNS.
CI/CD Integration
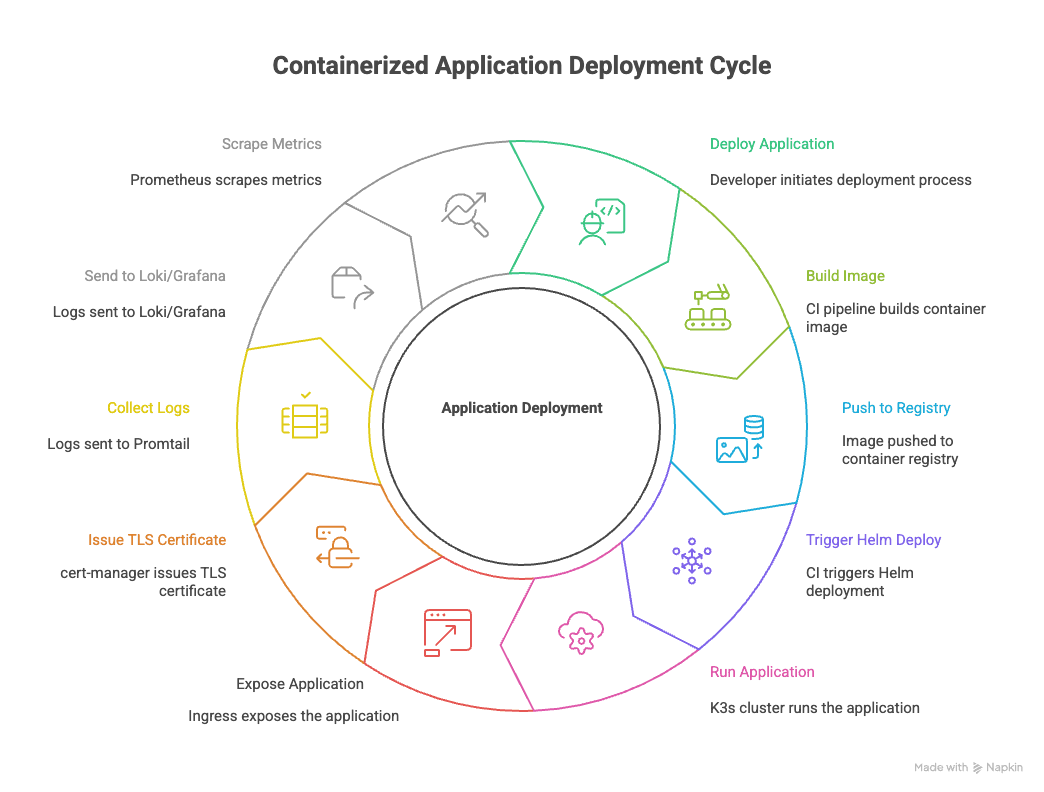
In production and staging environments, we deploy containerized applications using GitLab CI and GitHub Actions and ArgoCD, tied tightly with K3s.
Here’s how it works:
CI/CD Flow Overview
- Step 1: Build & Push Artifacts
GitHub/GitLab pipelines build and push Docker images to our container registry (GitHub Packages or GitLab Registry).
- Step 2: Helm/Manifest Deployment
Pipelines invoke helm upgrade --install or apply raw manifests for service, deployment, ingress, etc., to K3s clusters running in staging or production.
Each app has a Helm chart template for values-based configuration overrides.
- Step 4: Health Checks & Rollbacks
Post-deploy, we trigger synthetic health checks.
If a deployment fails readiness/liveness checks, GitHub/GitLab pipeline reverts using Helm’s rollback capabilities.
We intentionally avoid complexity like dynamic ephemeral clusters or DNS rewriting per branch—because our goal is stability, not show-off automation.
Security and Observability
- TLS bootstrapping, rotation, and etcd encryption are handled automatically by K3s.
- We ship logs via Fluent Bit to a central Loki/Grafana stack.
- Prometheus scrapes metrics from pods and node exporters.
What Worked Well
Here are some highlights from our experience:
Dev-Prod Parity
One of the best wins: our developers now work on the same orchestrator locally as we use for production workloads. No surprises. They can boot up an app with full Ingress, logs, and services
This dramatically reduced the “works on my machine” problem.
Speed + Simplicity
We have seen environments spin up in under 30 seconds, whether it’s a fresh cluster or an internal testing setup. This allows faster iterations and full autonomy for internal teams—without DevOps bottlenecks.
Lower Operational Burden
- No kubeadm complexities.
- Easier node recovery (just re-run the agent install).
- Control plane restarts or config reloads take seconds—not minutes.
Planning to Scale
K3s works well now—but we’ve planned for eventual scaling, especially if:
- We move into multiple regions or AZs.
- RPS starts going above expected thresholds.
- We need tighter integrations with AWS-native services (like ALB Ingress or IRSA for IAM roles).
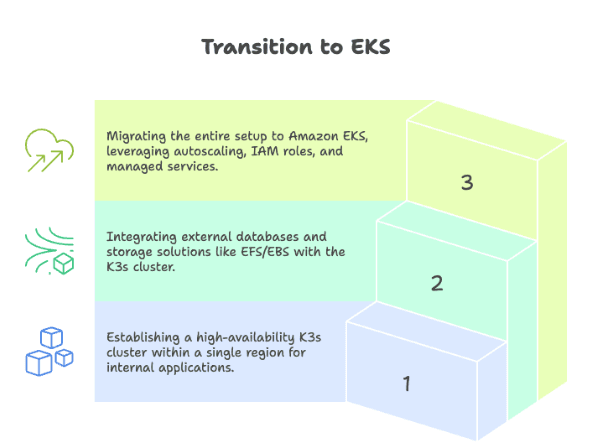
Our plan looks like this:
Phase | Cluster Design | Notes |
|---|---|---|
Now | K3s (HA clusters) | Lightweight, fast iterations, internal + some external services |
Mid | K3s + EFS/EBS + External DB | Add managed storage, move DBs out of cluster |
Scale | Migrate to EKS | Keep manifest compatibility, adopt autoscaling, ALB, IAM roles, etc. |
We’re designing our Helm charts, manifests, and secrets management to be cloud-agnostic, so EKS migration is mostly about bootstrapping infra—not rewriting workloads.
Why It’s Not Just a Dev-Test Cluster
We often see K3s dismissed as a dev-only tool, but we’re using it for actual product workloads:
- Handles read-heavy APIs under load.
- Hosts staging + internal sandbox environments.
- Developer bootstrapped clusters are used to test real IaC/CD flows.
This ensures that the dev-test-prod journey stays consistent, which helps debug earlier and reduces incident turnaround times.
End to End flow
This helps us making the solution cloud agnostic.
TL;DR:
- K3s helped us deploy fast and stay production-ready for MVPs and internal tooling.
- Simple setup, dev-prod parity, and low ops overhead made it ideal.
- We're future-proofing with Helm/manifest reusability for EKS migration when scale hits.
Final Thoughts
We’re not suggesting K3s as the ultimate Kubernetes replacement, but it’s proven to be a strategic choice for where we are. It gives us the agility of local-first development, the power of Kubernetes, and the focus to build important pieces like:
- CI/CD automation
- Observability
- Multi-tenancy
- Secrets and security
The point isn’t just about saving cost—it’s about saving complexity early, focusing engineering effort where it matters most, and keeping our path to scale open.
If you’re in the early or mid-stage of a project, or you’re looking to empower your developers without overwhelming your infrastructure team, K3s might just be the right fit.